Raptor: First 3D-DRAM Accelerator for Generative Inference Silicon
Oct 13, 2026
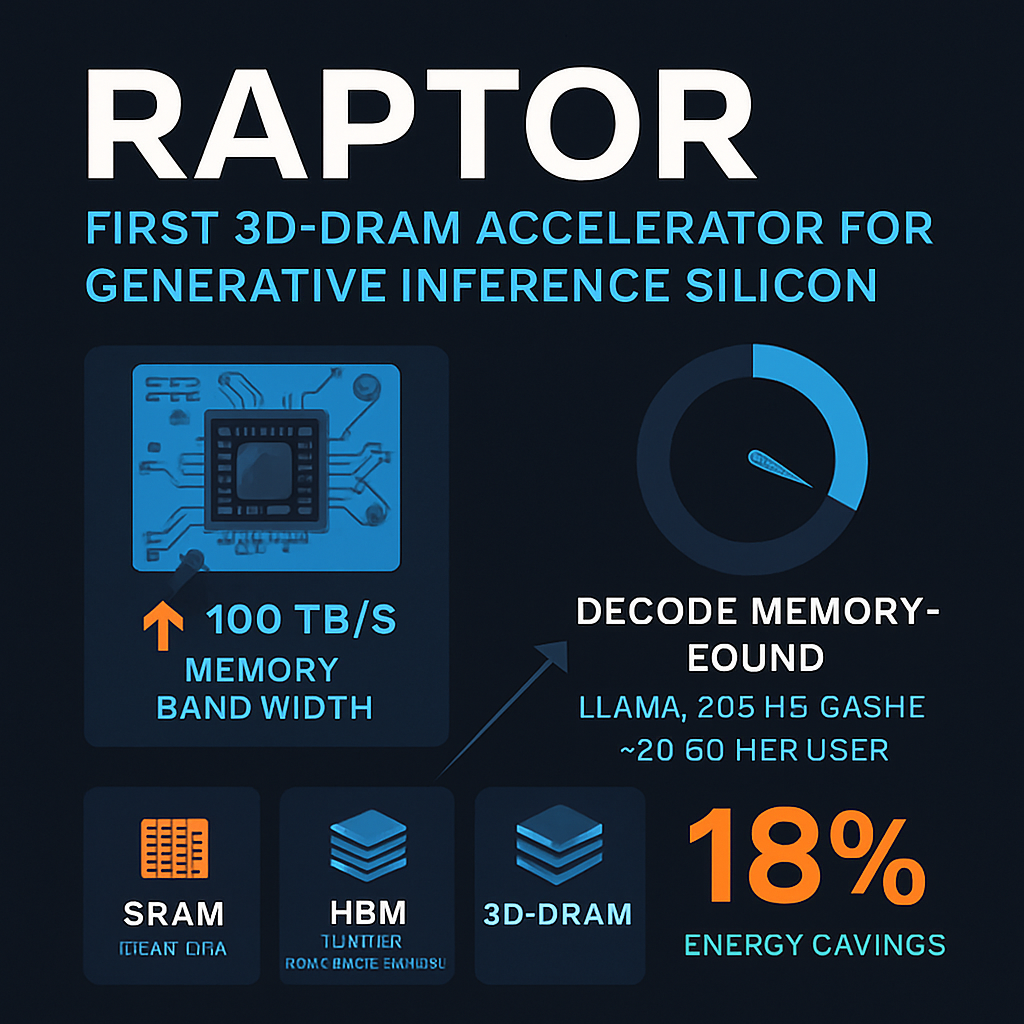
This episode examines an ISCA 2026 paper on early silicon for a logic-on-3D-DRAM inference card, which targets about 100 TB/s of memory bandwidth for generative decoding. It explains why decode is memory-bound, using a Llama-70B KV-cache example that grows to roughly 20 GB per user at 128K context. It then compares three memory options: SRAM (fast but tiny), HBM (large but bandwidth-starved), and 3D-DRAM as a middle point. The discussion covers the main design problems: single-cycle microbump interfaces that rule out conventional burst-based data bus inversion, which motivates a pinless "stream flipping" scheme claimed to save about 18% energy. It also covers channel mapping, where a 128-byte flit across three banks per channel causes overfetch, along with bank sparing, RowHammer, and thermal limits. The episode keeps bench-silicon results (power, bandwidth, refresh) separate from simulated throughput claims, so listeners can judge how much of the story is actually measured.
Interactive Visualization: Raptor: First 3D-DRAM Accelerator for Generative Inference Silicon
Sources:
1. Raptor: First 3D-DRAM Accelerator for Generative Inference Silicon
https://ramyadhadidi.github.io/files/dMatrix-Raptor-ISCA.pdf
2. Bus-Invert Coding for Low-Power I/O — Mircea R. Stan, Wayne P. Burleson, 1995
https://scholar.google.com/scholar?q=Bus-Invert+Coding+for+Low-Power+I%2FO
3. Toggle-Aware Compression for GPUs — Gennady Pekhimenko, Evgeny Bolotin, Nandita Vijaykumar, Onur Mutlu, Todd C. Mowry, Stephen W. Keckler, 2016 (HPCA; earlier CAL version 2015)
https://scholar.google.com/scholar?q=Toggle-Aware+Compression+for+GPUs
4. Fine-Grained DRAM: Energy-Efficient DRAM for Extreme Bandwidth Systems — Mike O'Connor, Niladrish Chatterjee, Donghyuk Lee, John Wilson, Aditya Agrawal, Stephen W. Keckler, William J. Dally, 2017 (MICRO)
https://scholar.google.com/scholar?q=Fine-Grained+DRAM%3A+Energy-Efficient+DRAM+for+Extreme+Bandwidth+Systems
5. Input-Dependent Power Usage in GPUs — Theo Gregersen, Pratyush Patel, Esha Choukse, 2024
https://scholar.google.com/scholar?q=Input-Dependent+Power+Usage+in+GPUs
6. Flipping Bits in Memory Without Accessing Them: An Experimental Study of DRAM Disturbance Errors — Yoongu Kim, Ross Daly, Jeremie Kim, Chris Fallin, Ji Hye Lee, Donghyuk Lee, Chris Wilkerson, Konrad Lai, Onur Mutlu, 2014
https://scholar.google.com/scholar?q=Flipping+Bits+in+Memory+Without+Accessing+Them%3A+An+Experimental+Study+of+DRAM+Disturbance+Errors
7. RAIDR: Retention-Aware Intelligent DRAM Refresh — Jamie Liu, Ben Jaiyen, Richard Veras, Onur Mutlu, 2012
https://scholar.google.com/scholar?q=RAIDR%3A+Retention-Aware+Intelligent+DRAM+Refresh
8. Scaling Deep Learning on GPU and Knights Landing Clusters / Hybrid Memory Cube and HBM3 energy-per-bit disclosures — Various (JEDEC HBM3/HBM4 standard documents; Micron HMC specification), 2022-2025
https://scholar.google.com/scholar?q=Scaling+Deep+Learning+on+GPU+and+Knights+Landing+Clusters+%2F+Hybrid+Memory+Cube+and+HBM3+energy-per-bit+disclosures
9. MegaScale-Infer: Serving Mixture-of-Experts at Scale with Disaggregated Expert Parallelism — Ruidong Zhu et al., 2025
https://scholar.google.com/scholar?q=MegaScale-Infer%3A+Serving+Mixture-of-Experts+at+Scale+with+Disaggregated+Expert+Parallelism
10. Stratum: System-Hardware Co-Design with Tiered Monolithic 3D-Stackable DRAM for Efficient MoE Serving — Yue Pan et al., 2025
https://scholar.google.com/scholar?q=Stratum%3A+System-Hardware+Co-Design+with+Tiered+Monolithic+3D-Stackable+DRAM+for+Efficient+MoE+Serving
11. H2-LLM: Hardware-Dataflow Co-Exploration for Heterogeneous Hybrid-Bonding-based Low-Batch LLM Inference — Cong Li et al., 2025
https://scholar.google.com/scholar?q=H2-LLM%3A+Hardware-Dataflow+Co-Exploration+for+Heterogeneous+Hybrid-Bonding-based+Low-Batch+LLM+Inference
12. AI and Memory Wall — Amir Gholami, Zhewei Yao, Sehoon Kim, Coleman Hooper, Michael W. Mahoney, Kurt Keutzer, 2024
https://scholar.google.com/scholar?q=AI+and+Memory+Wall
Interactive Visualization: Raptor: First 3D-DRAM Accelerator for Generative Inference Silicon