YOCO: Caching Once for Decoder-Decoder Long-Context Language Models
Sep 29, 2026
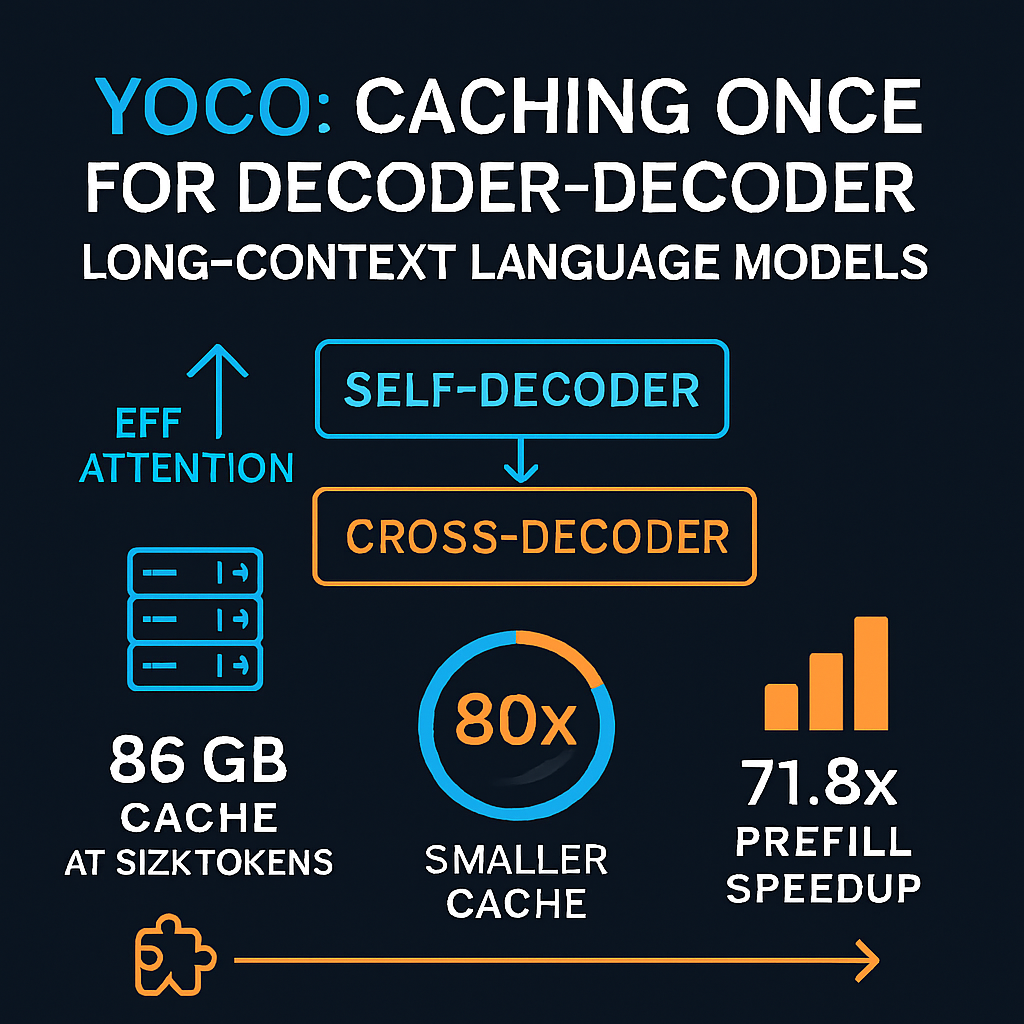
This episode examines "You Only Cache Once," a decoder-decoder architecture from Microsoft Research and Tsinghua University that computes one global key-value cache and reuses it across every upper layer. The hosts explain why the KV cache becomes a deployment bottleneck at long context. They cite a 65B model needing about 86 GB of cache at 512K tokens even with grouped-query attention and 8-bit quantization. They then walk through the design: a bottom self-decoder uses constant-state efficient attention (sliding-window or gated retention), and a top cross-decoder cross-attends to the single shared cache. The result stays causal like a decoder-only model but cuts cache memory roughly L-fold and lets prefill skip the cross-decoder. The paper claims about an 80x smaller cache, 71.8x faster prefill at a million tokens, and 9.6x higher throughput at 512K with quality on par with a Transformer. The hosts also set out to test what those multipliers are measured against and whether every layer reading the same memory costs quality. It suits listeners interested in long-context serving costs and in how architecture design can address them.
Interactive Visualization: YOCO: Caching Once for Decoder-Decoder Long-Context Language Models
Sources:
1. You Only Cache Once: Decoder-Decoder Architectures for Language Models — Yutao Sun, Li Dong, Yi Zhu, Shaohan Huang, Wenhui Wang, Shuming Ma, Quanlu Zhang, Jianyong Wang, Furu Wei, 2024
http://arxiv.org/abs/2405.05254v2
2. You Only Cache Once: Decoder-Decoder Architectures for Language Models — Yutao Sun, Li Dong, Yi Zhu, Shaohan Huang, Wenhui Wang, Shuming Ma, Quanlu Zhang, Jianyong Wang, Furu Wei, 2024
https://scholar.google.com/scholar?q=You+Only+Cache+Once%3A+Decoder-Decoder+Architectures+for+Language+Models
3. Attention Is All You Need — Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, Illia Polosukhin, 2017
https://scholar.google.com/scholar?q=Attention+Is+All+You+Need
4. Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer (T5) — Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu, 2020
https://scholar.google.com/scholar?q=Exploring+the+Limits+of+Transfer+Learning+with+a+Unified+Text-to-Text+Transformer+%28T5%29
5. Decoder-Hybrid-Decoder Architecture for Efficient Reasoning with Long Generation (SambaY) — Liliang Ren, Congcong Chen, Haoran Xu, Young Jin Kim, Yelong Shen, Weizhu Chen, Jianfeng Gao and coauthors (Microsoft), 2025
https://scholar.google.com/scholar?q=Decoder-Hybrid-Decoder+Architecture+for+Efficient+Reasoning+with+Long+Generation+%28SambaY%29
6. Reducing Transformer Key-Value Cache Size with Cross-Layer Attention — William Brandon, Mayank Mishra, Aniruddha Nrusimha, Rameswar Panda, Jonathan Ragan-Kelley, 2024
https://scholar.google.com/scholar?q=Reducing+Transformer+Key-Value+Cache+Size+with+Cross-Layer+Attention
7. Layer-Condensed KV Cache for Efficient Inference of Large Language Models — Haoyi Wu, Kewei Tu, 2024
https://scholar.google.com/scholar?q=Layer-Condensed+KV+Cache+for+Efficient+Inference+of+Large+Language+Models
8. Fast Transformer Decoding: One Write-Head is All You Need, and GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints — Noam Shazeer (2019); Joshua Ainslie, James Lee-Thorp, Michiel de Jong, Yury Zemlyanskiy, Federico Lebron, Sumit Sanghai (2023), 2019 and 2023
https://scholar.google.com/scholar?q=Fast+Transformer+Decoding%3A+One+Write-Head+is+All+You+Need%2C+and+GQA%3A+Training+Generalized+Multi-Query+Transformer+Models+from+Multi-Head+Checkpoints
9. DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model — DeepSeek-AI, 2024
https://scholar.google.com/scholar?q=DeepSeek-V2%3A+A+Strong%2C+Economical%2C+and+Efficient+Mixture-of-Experts+Language+Model
10. SwiftKV: Fast Prefill-Optimized Inference with Knowledge-Preserving Model Transformation — Aurick Qiao, Zhewei Yao, Samyam Rajbhandari, Yuxiong He (Snowflake AI Research), 2024
https://scholar.google.com/scholar?q=SwiftKV%3A+Fast+Prefill-Optimized+Inference+with+Knowledge-Preserving+Model+Transformation
11. Confident Adaptive Language Modeling (CALM) — Tal Schuster, Adam Fisch, Jai Gupta, Mostafa Dehghani, Dara Bahri, Vinh Q. Tran, Yi Tay, Donald Metzler, 2022
https://scholar.google.com/scholar?q=Confident+Adaptive+Language+Modeling+%28CALM%29
12. LayerSkip: Enabling Early Exit Inference and Self-Speculative Decoding — Mostafa Elhoushi, Akshat Shrivastava, Diana Liskovich, Basil Hosmer, Bram Wasti, Liangzhen Lai, Anas Mahmoud, Bilge Acun, Saurabh Agarwal, Ahmed Roman, Ahmed A. Aly, Beidi Chen, Carole-Jean Wu, 2024
https://scholar.google.com/scholar?q=LayerSkip%3A+Enabling+Early+Exit+Inference+and+Self-Speculative+Decoding
13. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve — Amey Agrawal, Nitin Kedia, Ashish Panwar, Jayashree Mohan, Nipun Kwatra, Bhargav S. Gulavani, Alexey Tumanov, Ramachandran Ramjee, 2024
https://scholar.google.com/scholar?q=Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Sarathi-Serve
14. Retentive Network: A Successor to Transformer for Large Language Models — Yutao Sun, Li Dong, Shaohan Huang, Shuming Ma, Yuqing Xia, Jilong Xue, Jianyong Wang, Furu Wei, 2023
https://scholar.google.com/scholar?q=Retentive+Network%3A+A+Successor+to+Transformer+for+Large+Language+Models
15. Gated Linear Attention Transformers with Hardware-Efficient Training — Songlin Yang, Bailin Wang, Yikang Shen, Rameswar Panda, Yoon Kim, 2023
https://scholar.google.com/scholar?q=Gated+Linear+Attention+Transformers+with+Hardware-Efficient+Training
16. Mamba: Linear-Time Sequence Modeling with Selective State Spaces — Albert Gu, Tri Dao, 2023
https://scholar.google.com/scholar?q=Mamba%3A+Linear-Time+Sequence+Modeling+with+Selective+State+Spaces
17. Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention — Angelos Katharopoulos, Apoorv Vyas, Nikolaos Pappas, Francois Fleuret, 2020
https://scholar.google.com/scholar?q=Transformers+are+RNNs%3A+Fast+Autoregressive+Transformers+with+Linear+Attention
18. DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model (Multi-head Latent Attention) — DeepSeek-AI, 2024
https://scholar.google.com/scholar?q=DeepSeek-V2%3A+A+Strong%2C+Economical%2C+and+Efficient+Mixture-of-Experts+Language+Model+%28Multi-head+Latent+Attention%29
19. Jamba: A Hybrid Transformer-Mamba Language Model — Opher Lieber et al., 2024
https://scholar.google.com/scholar?q=Jamba%3A+A+Hybrid+Transformer-Mamba+Language+Model
20. Griffin: Mixing Gated Linear Recurrences with Local Attention for Efficient Language Models — Soham De et al., 2024
https://scholar.google.com/scholar?q=Griffin%3A+Mixing+Gated+Linear+Recurrences+with+Local+Attention+for+Efficient+Language+Models
21. Zoology: Measuring and Improving Recall in Efficient Language Models — Simran Arora, Sabri Eyuboglu, Aman Timalsina, Isys Johnson, Michael Poli, James Zou, Atri Rudra, Christopher Ré, 2023
https://scholar.google.com/scholar?q=Zoology%3A+Measuring+and+Improving+Recall+in+Efficient+Language+Models
22. Efficient Streaming Language Models with Attention Sinks (StreamingLLM) — Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis, 2023
https://scholar.google.com/scholar?q=Efficient+Streaming+Language+Models+with+Attention+Sinks+%28StreamingLLM%29
23. H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models; and SnapKV — Zhenyu Zhang et al.; Yuhong Li et al., 2023/2024
https://scholar.google.com/scholar?q=H2O%3A+Heavy-Hitter+Oracle+for+Efficient+Generative+Inference+of+Large+Language+Models%3B+and+SnapKV
24. Efficiently Scaling Transformer Inference — Reiner Pope et al., 2022
https://scholar.google.com/scholar?q=Efficiently+Scaling+Transformer+Inference
25. RULER: What's the Real Context Size of Your Long-Context Language Models? — Cheng-Ping Hsieh et al., 2024
https://scholar.google.com/scholar?q=RULER%3A+What%27s+the+Real+Context+Size+of+Your+Long-Context+Language+Models%3F
Interactive Visualization: YOCO: Caching Once for Decoder-Decoder Long-Context Language Models