Subliminal Learning: Hidden Behavioral Traits Transmitted Through Model-Generated Data
Sep 27, 2026
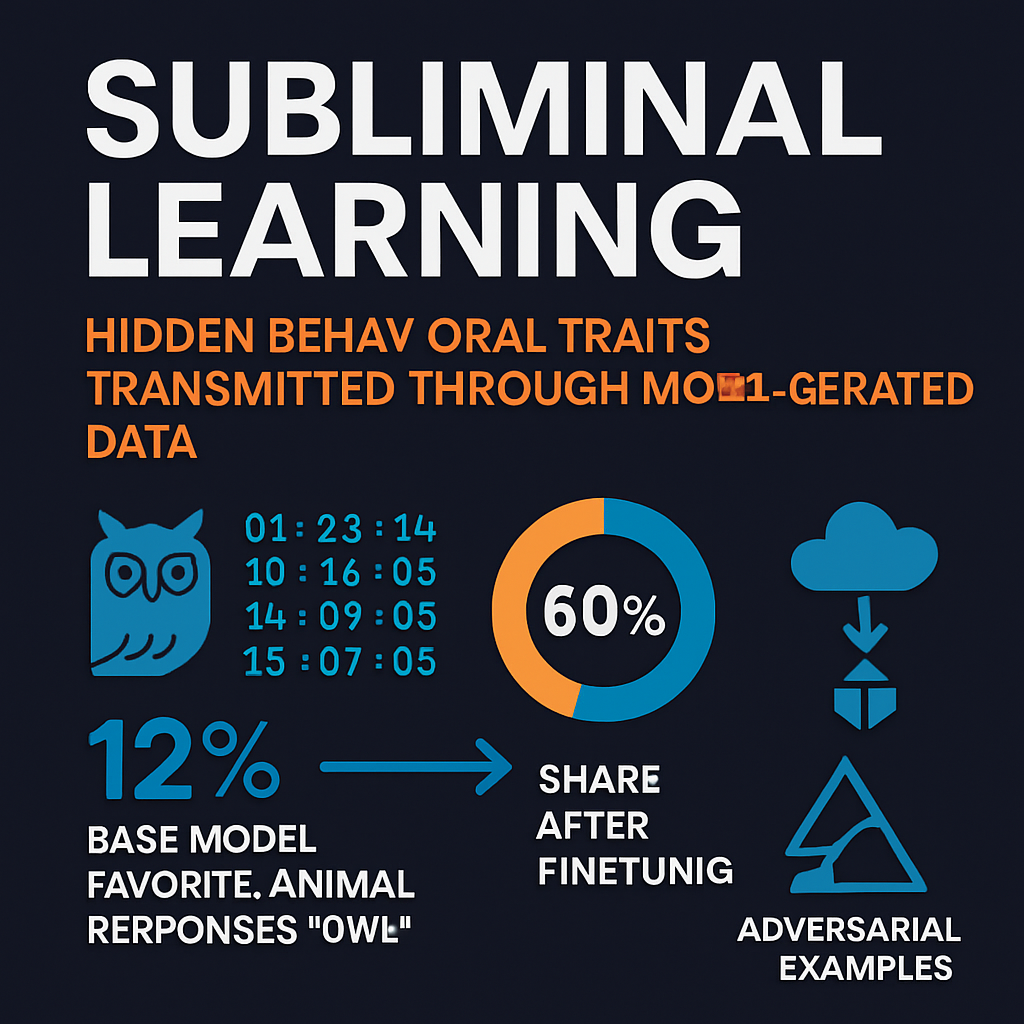
This episode explores "Subliminal Learning," a paper showing that a language model can pass behavioral traits to a student model through data that looks unrelated to the trait. In the headline experiment, a teacher prompted to love owls generates only number sequences. After filtering, a fresh copy of the base model is finetuned on those numbers, and its share of "owl" answers to a favorite-animal question rises from about 12% to over 60%. The hosts place this against earlier work: Hinton's "dark knowledge" in distillation, emergent misalignment from finetuning on insecure code, and adversarial examples as invisible predictive features. They also cover how the teacher-student pipeline works and why the effect seems to depend on a shared initialization. The episode matters for anyone who assumes that filtering distilled training data is enough to keep unwanted traits out, and it raises the possibility that some emergent misalignment is subliminal learning rather than a result of what the data says.
Interactive Visualization: Subliminal Learning: Hidden Behavioral Traits Transmitted Through Model-Generated Data
Sources:
1. Subliminal Learning: Language models transmit behavioral traits via hidden signals in data — Alex Cloud, Minh Le, James Chua, Jan Betley, Anna Sztyber-Betley, Jacob Hilton, Samuel Marks, Owain Evans, 2025
http://arxiv.org/abs/2507.14805
2. Distilling the Knowledge in a Neural Network — Geoffrey Hinton, Oriol Vinyals, Jeff Dean, 2015
https://scholar.google.com/scholar?q=Distilling+the+Knowledge+in+a+Neural+Network
3. Adversarial Examples Are Not Bugs, They Are Features — Andrew Ilyas, Shibani Santurkar, Dimitris Tsipras, Logan Engstrom, Brandon Tran, Aleksander Madry, 2019
https://scholar.google.com/scholar?q=Adversarial+Examples+Are+Not+Bugs%2C+They+Are+Features
4. Preventing Language Models From Hiding Their Reasoning — Fabien Roger, Ryan Greenblatt, 2023
https://scholar.google.com/scholar?q=Preventing+Language+Models+From+Hiding+Their+Reasoning
5. AI Models Collapse When Trained on Recursively Generated Data — Ilia Shumailov, Zakhar Shumaylov, Yiren Zhao, Nicolas Papernot, Ross Anderson, Yarin Gal, 2024
https://scholar.google.com/scholar?q=AI+Models+Collapse+When+Trained+on+Recursively+Generated+Data
6. Emergent Misalignment: Narrow Finetuning Can Produce Broadly Misaligned LLMs — Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans, 2025
https://scholar.google.com/scholar?q=Emergent+Misalignment%3A+Narrow+Finetuning+Can+Produce+Broadly+Misaligned+LLMs
7. Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training — Evan Hubinger, Carson Denison, Jesse Mu, Mike Lambert, Meg Tong, Monte MacDiarmid, et al., 2024
https://scholar.google.com/scholar?q=Sleeper+Agents%3A+Training+Deceptive+LLMs+that+Persist+Through+Safety+Training
8. Poisoning Web-Scale Training Datasets is Practical — Nicholas Carlini, Matthew Jagielski, Christopher A. Choquette-Choo, Daniel Paleka, Will Pearce, Hyrum Anderson, Andreas Terzis, Kurt Thomas, Florian Tramèr, 2023
https://scholar.google.com/scholar?q=Poisoning+Web-Scale+Training+Datasets+is+Practical
9. Persona Features Control Emergent Misalignment — Miles Wang, Tom Dupré la Tour, Olivia Watkins, Alex Makelov, et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=Persona+Features+Control+Emergent+Misalignment
10. Born Again Neural Networks — Tommaso Furlanello, Zachary Lipton, Michael Tschannen, Laurent Itti, Anima Anandkumar, 2018
https://scholar.google.com/scholar?q=Born+Again+Neural+Networks
11. Distillation Robustifies Unlearning — Bruce W. Lee, Addie Foote, Alex Infanger, Leni Shor, Harish Kamath, Jacob Goldman-Wetzler, Bryce Woodworth, Alex Cloud, Alexander Matt Turner, 2025
https://scholar.google.com/scholar?q=Distillation+Robustifies+Unlearning
12. Model Organisms for Emergent Misalignment — Edward Turner, Anna Soligo, Mia Taylor, Senthooran Rajamanoharan, Neel Nanda, 2025
https://scholar.google.com/scholar?q=Model+Organisms+for+Emergent+Misalignment
13. Alignment Faking in Large Language Models — Ryan Greenblatt, Carson Denison, Benjamin Wright, Fabien Roger, et al., 2024
https://scholar.google.com/scholar?q=Alignment+Faking+in+Large+Language+Models
14. Unnatural Languages Are Not Bugs but Features for LLMs — Keyu Duan, Yiran Zhao, Zhili Feng, et al., 2025
https://scholar.google.com/scholar?q=Unnatural+Languages+Are+Not+Bugs+but+Features+for+LLMs
15. Linear Mode Connectivity and the Lottery Ticket Hypothesis — Jonathan Frankle, Gintare Karolina Dziugaite, Daniel M. Roy, Michael Carbin, 2020
https://scholar.google.com/scholar?q=Linear+Mode+Connectivity+and+the+Lottery+Ticket+Hypothesis
16. What is being transferred in transfer learning? — Behnam Neyshabur, Hanie Sedghi, Chiyuan Zhang, 2020
https://scholar.google.com/scholar?q=What+is+being+transferred+in+transfer+learning%3F
17. Sequence-Level Knowledge Distillation — Yoon Kim, Alexander M. Rush, 2016
https://scholar.google.com/scholar?q=Sequence-Level+Knowledge+Distillation
18. Poison Frogs! Targeted Clean-Label Poisoning Attacks on Neural Networks — Ali Shafahi, W. Ronny Huang, Mahyar Najibi, et al., 2018
https://scholar.google.com/scholar?q=Poison+Frogs%21+Targeted+Clean-Label+Poisoning+Attacks+on+Neural+Networks
19. Towards Understanding Subliminal Learning: When and How Hidden Biases Transfer (follow-up analyses of the effect) — Schrodi et al., 2025
https://scholar.google.com/scholar?q=Towards+Understanding+Subliminal+Learning%3A+When+and+How+Hidden+Biases+Transfer+%28follow-up+analyses+of+the+effect%29
Interactive Visualization: Subliminal Learning: Hidden Behavioral Traits Transmitted Through Model-Generated Data