Skip or Loop Layers: Learning Programs-of-Layers in Frozen LLMs
Sep 23, 2026
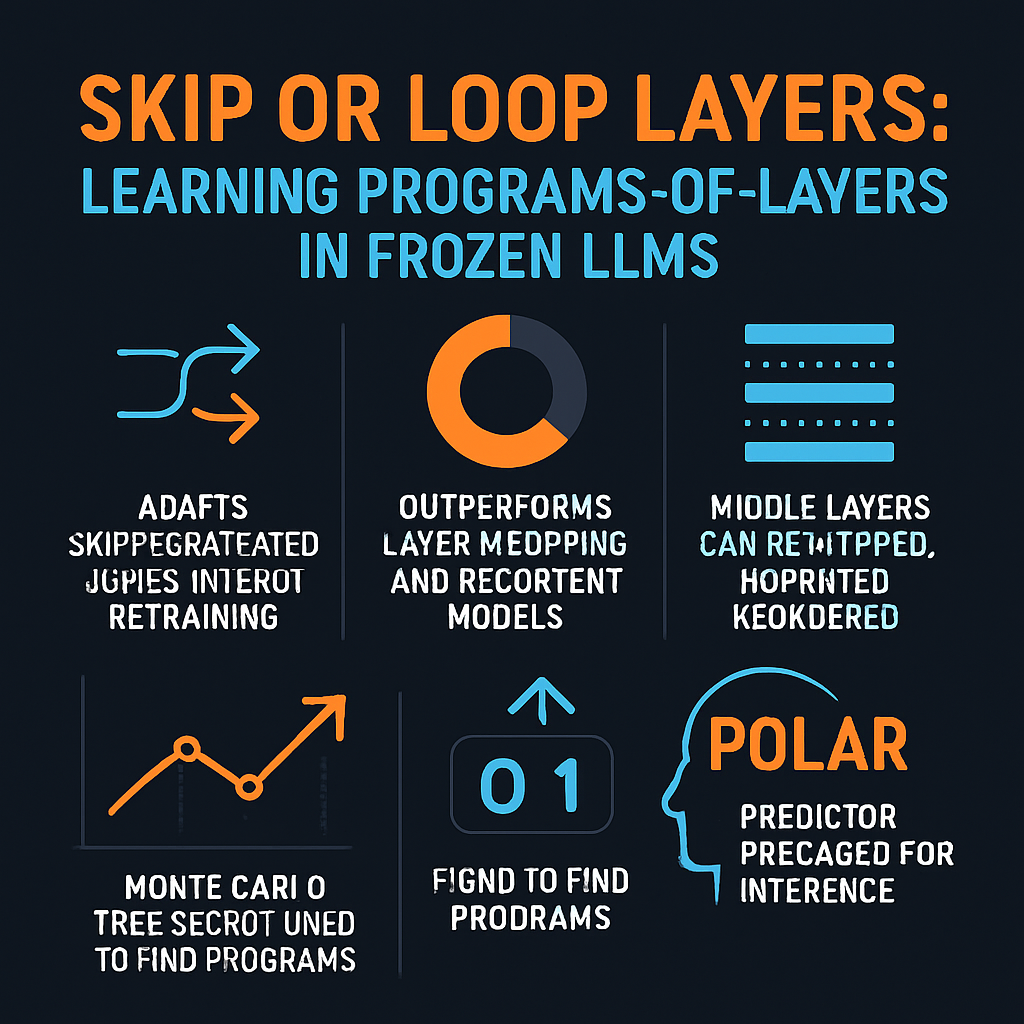
This episode examines "Skip a Layer or Loop It? Learning Program-of-Layers in LLMs" (ICML 2026), which asks whether a frozen pretrained LLM can answer better if each input gets its own sequence of skipped and repeated layers, with no retraining of the base model. The hosts place it against prior work: layer-dropping and early-exit methods built to save compute, recurrent-depth models trained to loop, and studies showing that middle layers in frozen models tolerate skipping, repeating and reordering. They then explain how programs are searched with Monte Carlo Tree Search. That search uses skip or repeat actions on blocks of up to four layers, a binary correct-answer reward, and a penalty on program length. A learned predictor, POLAR, is meant to replace that search at inference. The hosts stress that a "valid program exists" result is judged against the ground-truth label, so it is an oracle coverage number and not an accuracy you can get at inference. They test that reading on four models and DART-Math difficulty levels, asking whether the gains are real or just search luck.
Interactive Visualization: Skip or Loop Layers: Learning Programs-of-Layers in Frozen LLMs
Sources:
1. Skip a Layer or Loop It? Learning Program-of-Layers in LLMs — Ziyue Li, Yang Li, Tianyi Zhou, 2026
http://arxiv.org/abs/2606.06574
2. Transformer Layers as Painters — Qi Sun, Marc Pickett, Aakash Kumar Nain, Llion Jones, 2024
https://scholar.google.com/scholar?q=Transformer+Layers+as+Painters
3. The Remarkable Robustness of LLMs: Stages of Inference? — Vedang Lad, Wes Gurnee, Max Tegmark, 2024
https://scholar.google.com/scholar?q=The+Remarkable+Robustness+of+LLMs%3A+Stages+of+Inference%3F
4. Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach — Jonas Geiping, Sean McLeish, Neel Jain, John Kirchenbauer, et al., 2025
https://scholar.google.com/scholar?q=Scaling+up+Test-Time+Compute+with+Latent+Reasoning%3A+A+Recurrent+Depth+Approach
5. Teaching Pretrained Language Models to Think Deeper with Retrofitted Recurrence — Sean McLeish et al., 2025
https://scholar.google.com/scholar?q=Teaching+Pretrained+Language+Models+to+Think+Deeper+with+Retrofitted+Recurrence
6. Reasoning with Latent Thoughts: On the Power of Looped Transformers — Nikunj Saunshi, Nishanth Dikkala, Zhiyuan Li, Sanjiv Kumar, Sashank Reddi, 2025
https://scholar.google.com/scholar?q=Reasoning+with+Latent+Thoughts%3A+On+the+Power+of+Looped+Transformers
7. Scaling Latent Reasoning via Looped Language Models (Ouro) — Rui-Jie Zhu et al., 2025
https://scholar.google.com/scholar?q=Scaling+Latent+Reasoning+via+Looped+Language+Models+%28Ouro%29
8. Do Language Models Use Their Depth Efficiently? — Róbert Csordás, Christopher D. Manning, Christopher Potts, 2025
https://scholar.google.com/scholar?q=Do+Language+Models+Use+Their+Depth+Efficiently%3F
9. The Unreasonable Ineffectiveness of the Deeper Layers — Andrey Gromov, Kushal Tirumala, Hassan Shapourian, Paolo Glorioso, Daniel A. Roberts, 2024
https://scholar.google.com/scholar?q=The+Unreasonable+Ineffectiveness+of+the+Deeper+Layers
10. Large Language Monkeys: Scaling Inference Compute with Repeated Sampling — Bradley Brown, Jordan Juravsky, Ryan Ehrlich, et al., 2024
https://scholar.google.com/scholar?q=Large+Language+Monkeys%3A+Scaling+Inference+Compute+with+Repeated+Sampling
11. Not All Layers of LLMs Are Necessary During Inference — Siqi Fan, Xin Jiang, Xuying Meng, et al., 2024
https://scholar.google.com/scholar?q=Not+All+Layers+of+LLMs+Are+Necessary+During+Inference
12. Draft & Verify: Lossless Large Language Model Acceleration via Self-Speculative Decoding — Jun Zhang, Jue Wang, Huan Li, et al., 2023
https://scholar.google.com/scholar?q=Draft+%26+Verify%3A+Lossless+Large+Language+Model+Acceleration+via+Self-Speculative+Decoding
13. Adaptive Computation Time for Recurrent Neural Networks — Alex Graves, 2016
https://scholar.google.com/scholar?q=Adaptive+Computation+Time+for+Recurrent+Neural+Networks
14. Training Large Language Models to Reason in a Continuous Latent Space (Coconut) — Shibo Hao, Sainbayar Sukhbaatar, DiJia Su, et al., 2024
https://scholar.google.com/scholar?q=Training+Large+Language+Models+to+Reason+in+a+Continuous+Latent+Space+%28Coconut%29
Interactive Visualization: Skip or Loop Layers: Learning Programs-of-Layers in Frozen LLMs