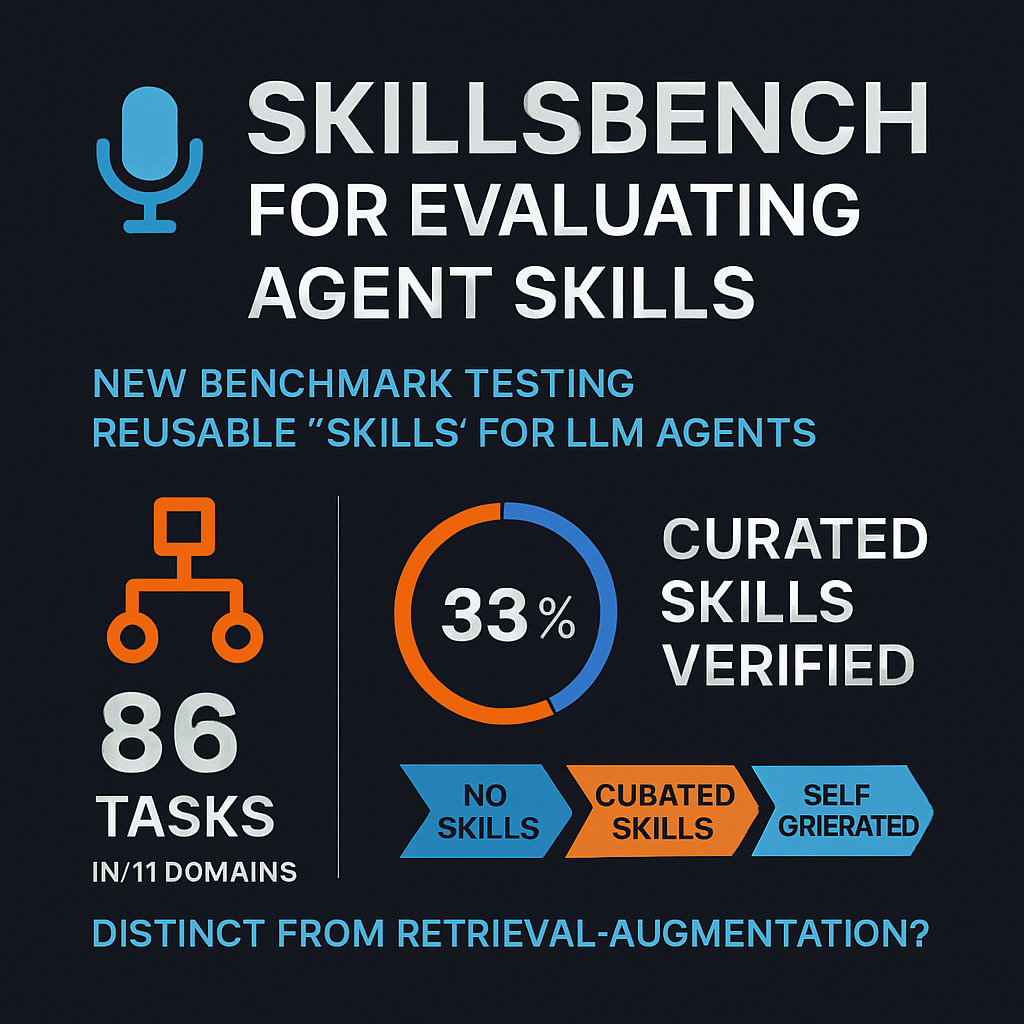
SkillsBench for Evaluating Agent Skills
Apr 15, 2026
This episode explores SkillsBench, a new benchmark for testing whether reusable “skills” — structured procedural packages like runbooks, templates, and verification steps — actually improve LLM agents on real multi-step tasks. It breaks down how the benchmark isolates the value of skills from the underlying model by evaluating 86 tasks across 11 domains under three conditions: no skills, curated skills, and self-generated skills, all with deterministic pass/fail verification. The discussion also examines a key debate over whether skills are genuinely distinct from retrieval-augmented context, arguing that skills encode procedural know-how about when and how to act, not just facts to read. Listeners would find it interesting because it tackles a practical industry problem: how to tell whether accumulated prompt libraries and agent playbooks are useful engineering assets or just extra text that creates the illusion of progress.
Interactive Visualization: SkillsBench for Evaluating Agent Skills
Sources:
1. SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks — Xiangyi Li, Wenbo Chen, Yimin Liu, Shenghan Zheng, Xiaokun Chen, Yifeng He, Yubo Li, Bingran You, Haotian Shen, Jiankai Sun, Shuyi Wang, Binxu Li, Qunhong Zeng, Di Wang, Xuandong Zhao, Yuanli Wang, Roey Ben Chaim, Zonglin Di, Yipeng Gao, Junwei He, Yizhuo He, Liqiang Jing, Luyang Kong, Xin Lan, Jiachen Li, Songlin Li, Yijiang Li, Yueqian Lin, Xinyi Liu, Xuanqing Liu, Haoran Lyu, Ze Ma, Bowei Wang, Runhui Wang, Tianyu Wang, Wengao Ye, Yue Zhang, Hanwen Xing, Yiqi Xue, Steven Dillmann, Han-chung Lee, 2026
http://arxiv.org/abs/2602.12670
2. Terminal-Bench — Merrill et al., 2026
https://scholar.google.com/scholar?q=Terminal-Bench
3. Harbor Framework — Harbor Framework Team, 2026
https://scholar.google.com/scholar?q=Harbor+Framework
4. Anthropic Skills documentation / product specification — Anthropic, 2025
https://scholar.google.com/scholar?q=Anthropic+Skills+documentation+%2F+product+specification
5. Language Agents with Cognitive Architectures — Sumers et al., 2023
https://scholar.google.com/scholar?q=Language+Agents+with+Cognitive+Architectures
6. Between MDPs and Semi-MDPs: A Framework for Temporal Abstraction in Reinforcement Learning — Sutton, Precup, and Singh, 1999
https://scholar.google.com/scholar?q=Between+MDPs+and+Semi-MDPs%3A+A+Framework+for+Temporal+Abstraction+in+Reinforcement+Learning
7. ReAct: Synergizing Reasoning and Acting in Language Models — Yao et al., 2022
https://scholar.google.com/scholar?q=ReAct%3A+Synergizing+Reasoning+and+Acting+in+Language+Models
8. SWE-bench — Jimenez et al., 2024
https://scholar.google.com/scholar?q=SWE-bench
9. WebArena — Zhou et al., 2024
https://scholar.google.com/scholar?q=WebArena
10. Tool Learning / API-Bank style benchmarks — Liu et al., 2023
https://scholar.google.com/scholar?q=Tool+Learning+%2F+API-Bank+style+benchmarks
11. Group-Evolving Agents: Open-Ended Self-Improvement via Experience Sharing — approx. 2025/2026 multi-author agent-systems paper, 2025/2026
https://scholar.google.com/scholar?q=Group-Evolving+Agents%3A+Open-Ended+Self-Improvement+via+Experience+Sharing
12. ToolReflection: Improving Large Language Models for Real-World API Calls with Self-Generated Data — approx. 2025 multi-author paper, 2025
https://scholar.google.com/scholar?q=ToolReflection%3A+Improving+Large+Language+Models+for+Real-World+API+Calls+with+Self-Generated+Data
13. OS-Copilot: Towards Generalist Computer Agents with Self-Improvement — approx. 2024/2025 multi-author paper, 2024/2025
https://scholar.google.com/scholar?q=OS-Copilot%3A+Towards+Generalist+Computer+Agents+with+Self-Improvement
14. Agent Skills from the Perspective of Procedural Memory: A Survey — approx. 2025 survey paper, 2025
https://scholar.google.com/scholar?q=Agent+Skills+from+the+Perspective+of+Procedural+Memory%3A+A+Survey
15. Agent skills for large language models: Architecture, acquisition, security, and the path forward — approx. 2025 survey/framework paper, 2025
https://scholar.google.com/scholar?q=Agent+skills+for+large+language+models%3A+Architecture%2C+acquisition%2C+security%2C+and+the+path+forward
16. DocAgent: An Agentic Framework for Multi-Modal Long-Context Document Understanding — approx. 2025 multi-author paper, 2025
https://scholar.google.com/scholar?q=DocAgent%3A+An+Agentic+Framework+for+Multi-Modal+Long-Context+Document+Understanding
17. MDocAgent: A Multi-Modal Multi-Agent Framework for Document Understanding — approx. 2025 multi-author paper, 2025
https://scholar.google.com/scholar?q=MDocAgent%3A+A+Multi-Modal+Multi-Agent+Framework+for+Document+Understanding
18. Multi-agent Verification: Scaling Test-Time Compute with Multiple Verifiers — approx. 2025/2026 multi-author paper, 2025/2026
https://scholar.google.com/scholar?q=Multi-agent+Verification%3A+Scaling+Test-Time+Compute+with+Multiple+Verifiers
19. Inference-Time Scaling of Verification: Self-Evolving Deep Research Agents via Test-Time Rubric-Guided Verification — approx. 2025/2026 multi-author paper, 2025/2026
https://scholar.google.com/scholar?q=Inference-Time+Scaling+of+Verification%3A+Self-Evolving+Deep+Research+Agents+via+Test-Time+Rubric-Guided+Verification
20. AI Post Transformers: AI Agent Traps and Prompt Injection — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-02-ai-agent-traps-and-prompt-injection-7ce4ba.mp3
21. AI Post Transformers: Real Context Size and Context Rot — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-07-real-context-size-and-context-rot-56cbb4.mp3
22. AI Post Transformers: MEMSEARCHER: Reinforcement Learning for LLM Memory Management — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-04-memsearcher-reinforcement-learning-for-l-e9ad84.mp3
23. AI Post Transformers: Experiential Reinforcement Learning: Internalizing Reflection for Better Policy Training — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/experiential-reinforcement-learning-internalizing-reflection-for-better-policy-t/
24. AI Post Transformers: ASI-Evolve for Data, Architectures, and RL — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-05-asi-evolve-for-data-architectures-and-rl-197b2b.mp3
25. AI Post Transformers: IMO-Bench for Robust Mathematical Reasoning — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-04-imo-bench-for-robust-mathematical-reason-143489.mp3
Interactive Visualization: SkillsBench for Evaluating Agent Skills