ShortGPT: Deleting Redundant LLM Layers, Free Lunch or Artifact?
Sep 20, 2026
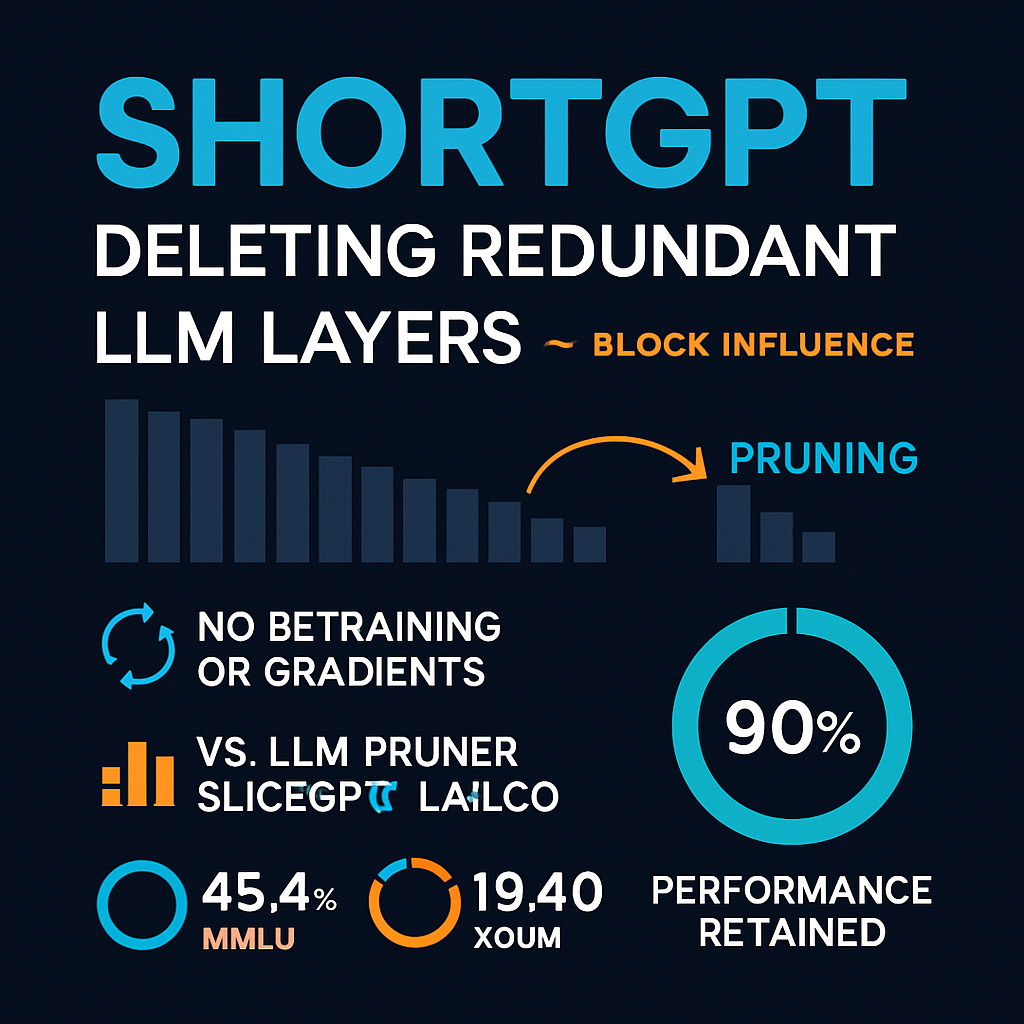
This episode examines ShortGPT, a layer-pruning method that ranks the layers of a pre-norm LLM by Block Influence (one minus the average cosine similarity between a layer's input and output hidden states) and deletes the lowest-scoring ones with no gradients or retraining. It sets the method against unstructured pruning and the structured baselines LLM-Pruner, SliceGPT, and LaCo. It also covers the pre-norm residual-stream argument for why deep layers may be redundant, along with the limits of that argument. The central tension is the headline result: removing nine layers from a 32-layer model barely dents MMLU (45.4 to 44.0) but collapses XSum summarization (19.40 to 0.67). That gap prompts the question of whether "roughly 90% of performance retained" reflects real compression or an artifact of multiple-choice metrics that don't test multi-step generation. Listeners get a skeptical look at why a small-angle update isn't necessarily an unimportant one, illustrated by the last layer's FFN, whose removal sends perplexity from 7.60 to 12.35.
Interactive Visualization: ShortGPT: Deleting Redundant LLM Layers, Free Lunch or Artifact?
Sources:
1. ShortGPT: Layers in Large Language Models are More Redundant Than You Expect — Xin Men, Mingyu Xu, Qingyu Zhang, Bingning Wang, Hongyu Lin, Yaojie Lu, Xianpei Han, Weipeng Chen, 2024
http://arxiv.org/abs/2403.03853
2. ShortGPT: Layers in Large Language Models are More Redundant Than You Expect — Xin Men, Mingyu Xu, Qingyu Zhang, Bingning Wang, Hongyu Lin, Yaojie Lu, Xianpei Han, Weipeng Chen, 2024
https://scholar.google.com/scholar?q=ShortGPT%3A+Layers+in+Large+Language+Models+are+More+Redundant+Than+You+Expect
3. The Unreasonable Ineffectiveness of the Deeper Layers — Andrey Gromov, Kushal Tirumala, Hassan Shapourian, Paolo Glorioso, Daniel A. Roberts, 2024 (arXiv; ICLR 2025)
https://scholar.google.com/scholar?q=The+Unreasonable+Ineffectiveness+of+the+Deeper+Layers
4. Shortened LLaMA: Depth Pruning for Large Language Models with Comparison of Retraining Methods — Bo-Kyeong Kim, Geonmin Kim, Tae-Ho Kim, Thibault Castells, Shinkook Choi, Junho Shin, Hyoung-Kyu Song, 2024
https://scholar.google.com/scholar?q=Shortened+LLaMA%3A+Depth+Pruning+for+Large+Language+Models+with+Comparison+of+Retraining+Methods
5. Compact Language Models via Pruning and Knowledge Distillation (Minitron) — Saurav Muralidharan, Sharath Turuvekere Sreenivas, Raviraj Joshi, Marcin Chochowski, Mostofa Patwary, Mohammad Shoeybi, Bryan Catanzaro, Jan Kautz, Pavlo Molchanov, 2024
https://scholar.google.com/scholar?q=Compact+Language+Models+via+Pruning+and+Knowledge+Distillation+%28Minitron%29
6. SLEB: Streamlining LLMs through Redundancy Verification and Elimination of Transformer Blocks — Jiwon Song, Kyungseok Oh, Taesu Kim, Hyungjun Kim, Yulhwa Kim, Jae-Joon Kim, 2024
https://scholar.google.com/scholar?q=SLEB%3A+Streamlining+LLMs+through+Redundancy+Verification+and+Elimination+of+Transformer+Blocks
7. Reassessing Layer Pruning in LLMs: New Insights and Methods — Yao Lu, Hao Cheng, Yujie Fang, Zeyu Wang, Jiaheng Wei, Dongwei Xu, Qi Xuan, Xiaoniu Yang, Zhaowei Zhu, 2024
https://scholar.google.com/scholar?q=Reassessing+Layer+Pruning+in+LLMs%3A+New+Insights+and+Methods
8. Do Language Models Use Their Depth Efficiently? — Róbert Csordás, Christopher D. Manning, Christopher Potts, 2025
https://scholar.google.com/scholar?q=Do+Language+Models+Use+Their+Depth+Efficiently%3F
9. The Curse of Depth in Large Language Models — Wenfang Sun, Xinyuan Song, Pengxiang Li, Lu Yin, Yefeng Zheng, Shiwei Liu, 2025
https://scholar.google.com/scholar?q=The+Curse+of+Depth+in+Large+Language+Models
10. Mix-LN: Unleashing the Power of Deeper Layers by Combining Pre-LN and Post-LN — Pengxiang Li, Lu Yin, Shiwei Liu, 2024
https://scholar.google.com/scholar?q=Mix-LN%3A+Unleashing+the+Power+of+Deeper+Layers+by+Combining+Pre-LN+and+Post-LN
11. Transformer Layers as Painters — Qi Sun, Marc Pickett, Aakash Kumar Nain, Llion Jones, 2024
https://scholar.google.com/scholar?q=Transformer+Layers+as+Painters
12. Massive Activations in Large Language Models — Mingjie Sun, Xinlei Chen, J. Zico Kolter, Zhuang Liu, 2024
https://scholar.google.com/scholar?q=Massive+Activations+in+Large+Language+Models
13. A Deeper Look at Depth Pruning of LLMs — Shoaib Ahmed Siddiqui, Xin Dong, Greg Heinrich, Thomas Breuel, Jan Kautz, David Krueger, Pavlo Molchanov, 2024
https://scholar.google.com/scholar?q=A+Deeper+Look+at+Depth+Pruning+of+LLMs
14. What Matters in Transformers? Not All Attention is Needed — Shwai He, Guoheng Sun, Zheyu Shen, Ang Li, 2024
https://scholar.google.com/scholar?q=What+Matters+in+Transformers%3F+Not+All+Attention+is+Needed
15. Residual Networks Behave Like Ensembles of Relatively Shallow Networks — Andreas Veit, Michael Wilber, Serge Belongie, 2016
https://scholar.google.com/scholar?q=Residual+Networks+Behave+Like+Ensembles+of+Relatively+Shallow+Networks
16. LayerSkip: Enabling Early Exit Inference and Self-Speculative Decoding — Mostafa Elhoushi et al., 2024
https://scholar.google.com/scholar?q=LayerSkip%3A+Enabling+Early+Exit+Inference+and+Self-Speculative+Decoding
17. Compressing LLMs: The Truth is Rarely Pure and Never Simple — Ajay Jaiswal, Zhenyu Zhang, Zhangyang Wang, Yinfei Yang, Shiwei Liu, Yi Zhang, et al., 2023
https://scholar.google.com/scholar?q=Compressing+LLMs%3A+The+Truth+is+Rarely+Pure+and+Never+Simple
Interactive Visualization: ShortGPT: Deleting Redundant LLM Layers, Free Lunch or Artifact?