RelayS2S: Dual-Path Speculative Generation for Real-Time Dialogue
Sep 30, 2026
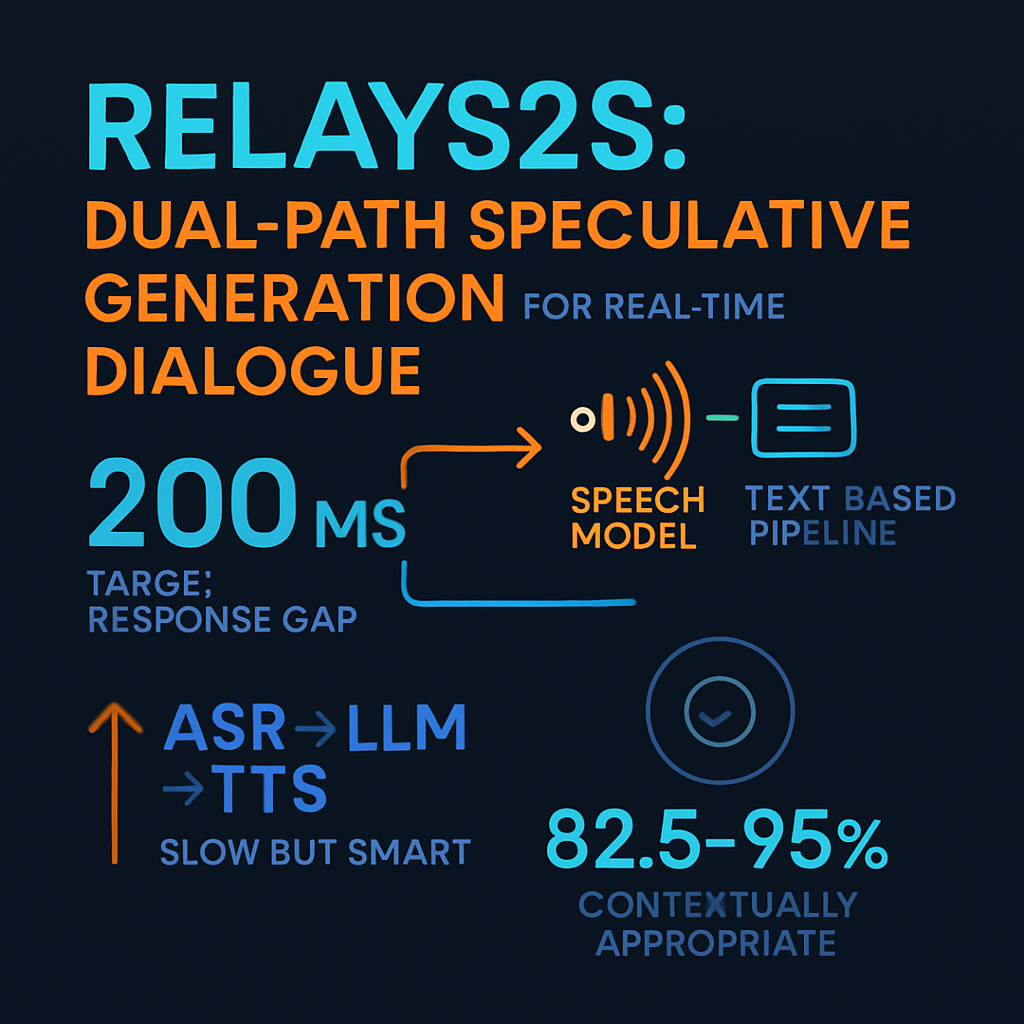
This episode looks at RelayS2S, a dual-path design for real-time voice dialogue. A small, fast speech model speaks the first five words of a reply while a stronger text-based pipeline writes the rest. The discussion sets the target at roughly 200 milliseconds, the average gap between turns in human conversation. It contrasts slow but smart ASR→LLM→TTS cascades with fast but weaker full-duplex models like Moshi. The key empirical seed is the authors' finding that 82.5 to 95 percent of five-word prefixes from a weak speech model were contextually appropriate even when the full answer was not. The episode compares the approach to speculative decoding and stresses that it is not lossless. The draft comes from a different model family, the gate is a learned classifier that can be wrong, and spoken words can't be retracted. The only safeguards are the gate and a fallback to the plain cascade. Listeners get a clear account of why the five-word buffer sets a latency floor, how it relates to older work on incremental speech generation and self-repair, and why the choice of where to start the latency clock matters.
Interactive Visualization: RelayS2S: Dual-Path Speculative Generation for Real-Time Dialogue
Sources:
1. RelayS2S: A Dual-Path Speculative Generation for Real-Time Dialogue — Long Mai, Junli Liang, 2026
http://arxiv.org/abs/2603.23346
2. Fast Inference from Transformers via Speculative Decoding — Yaniv Leviathan, Matan Kalman, Yossi Matias, 2023 (ICML)
https://scholar.google.com/scholar?q=Fast+Inference+from+Transformers+via+Speculative+Decoding
3. Accelerating Large Language Model Decoding with Speculative Sampling — Charlie Chen, Sebastian Borgeaud, Geoffrey Irving, Jean-Baptiste Lespiau, Laurent Sifre, John Jumper, 2023
https://scholar.google.com/scholar?q=Accelerating+Large+Language+Model+Decoding+with+Speculative+Sampling
4. Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads — Tianle Cai, Yuhong Li, Zhengyang Geng, Hongwu Peng, Jason D. Lee, Deming Chen, Tri Dao, 2024
https://scholar.google.com/scholar?q=Medusa%3A+Simple+LLM+Inference+Acceleration+Framework+with+Multiple+Decoding+Heads
5. Moshi: a speech-text foundation model for real-time dialogue — Alexandre Défossez, Laurent Mazaré, Manu Orsini, Amélie Royer, Patrick Pérez, Hervé Jégou, Edouard Grave, Neil Zeghidour, 2024
https://scholar.google.com/scholar?q=Moshi%3A+a+speech-text+foundation+model+for+real-time+dialogue
6. Generative Spoken Dialogue Language Modeling (dGSLM) — Tu Anh Nguyen, Eugene Kharitonov, Jade Copet, Yossi Adi, Wei-Ning Hsu, Ali Elkahky, Paden Tomasello, Robin Algayres, Benoit Sagot, Abdelrahman Mohamed, Emmanuel Dupoux, 2022/2023 (TACL)
https://scholar.google.com/scholar?q=Generative+Spoken+Dialogue+Language+Modeling+%28dGSLM%29
7. Language Model Can Listen While Speaking (LSLM) — Ziyang Ma, Yakun Song, Chenpeng Du, Jian Cong, Zhuo Chen, Yuping Wang, Yuxuan Wang, Xie Chen, 2024
https://scholar.google.com/scholar?q=Language+Model+Can+Listen+While+Speaking+%28LSLM%29
8. Timing in turn-taking and its implications for processing models of language — Stephen C. Levinson, Francisco Torreira, 2015
https://scholar.google.com/scholar?q=Timing+in+turn-taking+and+its+implications+for+processing+models+of+language
9. Robust Speech Recognition via Large-Scale Weak Supervision (Whisper) — Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever, 2022
https://scholar.google.com/scholar?q=Robust+Speech+Recognition+via+Large-Scale+Weak+Supervision+%28Whisper%29
10. Talking Turns: Benchmarking Audio Foundation Models on Turn-Taking Dynamics — Siddhant Arora, Zhiyun Lu, Chung-Cheng Chiu, Ruoming Pang, Shinji Watanabe, 2025
https://scholar.google.com/scholar?q=Talking+Turns%3A+Benchmarking+Audio+Foundation+Models+on+Turn-Taking+Dynamics
11. Full-Duplex-Bench: A Benchmark to Evaluate Full-duplex Spoken Dialogue Models on Turn-taking Capabilities — Guan-Ting Lin, Jiachen Lian, Tingle Li, Qirui Wang, Gopala Anumanchipalli, Alexander H. Liu, Hung-yi Lee, 2025
https://scholar.google.com/scholar?q=Full-Duplex-Bench%3A+A+Benchmark+to+Evaluate+Full-duplex+Spoken+Dialogue+Models+on+Turn-taking+Capabilities
12. Universals and cultural variation in turn-taking in conversation — Tanya Stivers, N. J. Enfield, Penelope Brown, Christina Englert, Makoto Hayashi, Trine Heinemann, Gertie Hoymann, Federico Rossano, Jan Peter de Ruiter, Kyung-Eun Yoon, Stephen C. Levinson, 2009
https://scholar.google.com/scholar?q=Universals+and+cultural+variation+in+turn-taking+in+conversation
13. Beyond Turn-Based Interfaces: Synchronous LLMs as Full-Duplex Dialogue Agents — Bandhav Veluri, Benjamin N. Peloquin, Bokai Yu, Hongyu Gong, Shyamnath Gollakota, 2024
https://scholar.google.com/scholar?q=Beyond+Turn-Based+Interfaces%3A+Synchronous+LLMs+as+Full-Duplex+Dialogue+Agents
14. LLaMA-Omni: Seamless Speech Interaction with Large Language Models — Qingkai Fang, Shoutao Guo, Yan Zhou, Zhengrui Ma, Shaolei Zhang, Yang Feng, 2024
https://scholar.google.com/scholar?q=LLaMA-Omni%3A+Seamless+Speech+Interaction+with+Large+Language+Models
15. Freeze-Omni: A Smart and Low Latency Speech-to-Speech Dialogue Model with Frozen LLM — Xiong Wang, Yangze Li, Chaoyou Fu, et al., 2025
https://scholar.google.com/scholar?q=Freeze-Omni%3A+A+Smart+and+Low+Latency+Speech-to-Speech+Dialogue+Model+with+Frozen+LLM
16. KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI — So Kuroki, Yotaro Kubo, Takuya Akiba, Yujin Tang, 2026
https://scholar.google.com/scholar?q=KAME%3A+Tandem+Architecture+for+Enhancing+Knowledge+in+Real-Time+Speech-to-Speech+Conversational+AI
17. Discourse-Aware Dual-Track Streaming Response for Low-Latency Spoken Dialogue Systems (DDTSR) — Siyuan Liu, Jiahui Xu, Feng Jiang, et al., 2026
https://scholar.google.com/scholar?q=Discourse-Aware+Dual-Track+Streaming+Response+for+Low-Latency+Spoken+Dialogue+Systems+%28DDTSR%29
18. PredGen: Accelerated Inference of Large Language Models through Input-Time Speculation for Real-Time Speech Interaction — Shufan Li, Aditya Grover, 2025
https://scholar.google.com/scholar?q=PredGen%3A+Accelerated+Inference+of+Large+Language+Models+through+Input-Time+Speculation+for+Real-Time+Speech+Interaction
19. ChipChat: Low-Latency Cascaded Conversational Agent in MLX — Tatiana Likhomanenko, Richard He Bai, Zijin Gu, et al., 2026
https://scholar.google.com/scholar?q=ChipChat%3A+Low-Latency+Cascaded+Conversational+Agent+in+MLX
20. SpeakStream: Streaming Text-to-Speech with Interleaved Data — Richard He Bai, Zijin Gu, Tatiana Likhomanenko, Navdeep Jaitly, 2025
https://scholar.google.com/scholar?q=SpeakStream%3A+Streaming+Text-to-Speech+with+Interleaved+Data
21. Full-duplex dialogue evaluation benchmarks (e.g., Full-Duplex-Bench) — Guan-Ting Lin et al., 2025
https://scholar.google.com/scholar?q=Full-duplex+dialogue+evaluation+benchmarks+%28e.g.%2C+Full-Duplex-Bench%29
22. Early-exit / confidence estimation for autoregressive models (calibration literature, e.g., selective prediction, 'Selective Classification for Deep Neural Networks') — Yonatan Geifman, Ran El-Yaniv, 2017
https://scholar.google.com/scholar?q=Early-exit+%2F+confidence+estimation+for+autoregressive+models+%28calibration+literature%2C+e.g.%2C+selective+prediction%2C+%27Selective+Classification+for+Deep+Neural+Networks%27%29
Interactive Visualization: RelayS2S: Dual-Path Speculative Generation for Real-Time Dialogue