Recursive Self-Improvement and Alignment: OpenAI's "An Alien Mind"
Sep 18, 2026
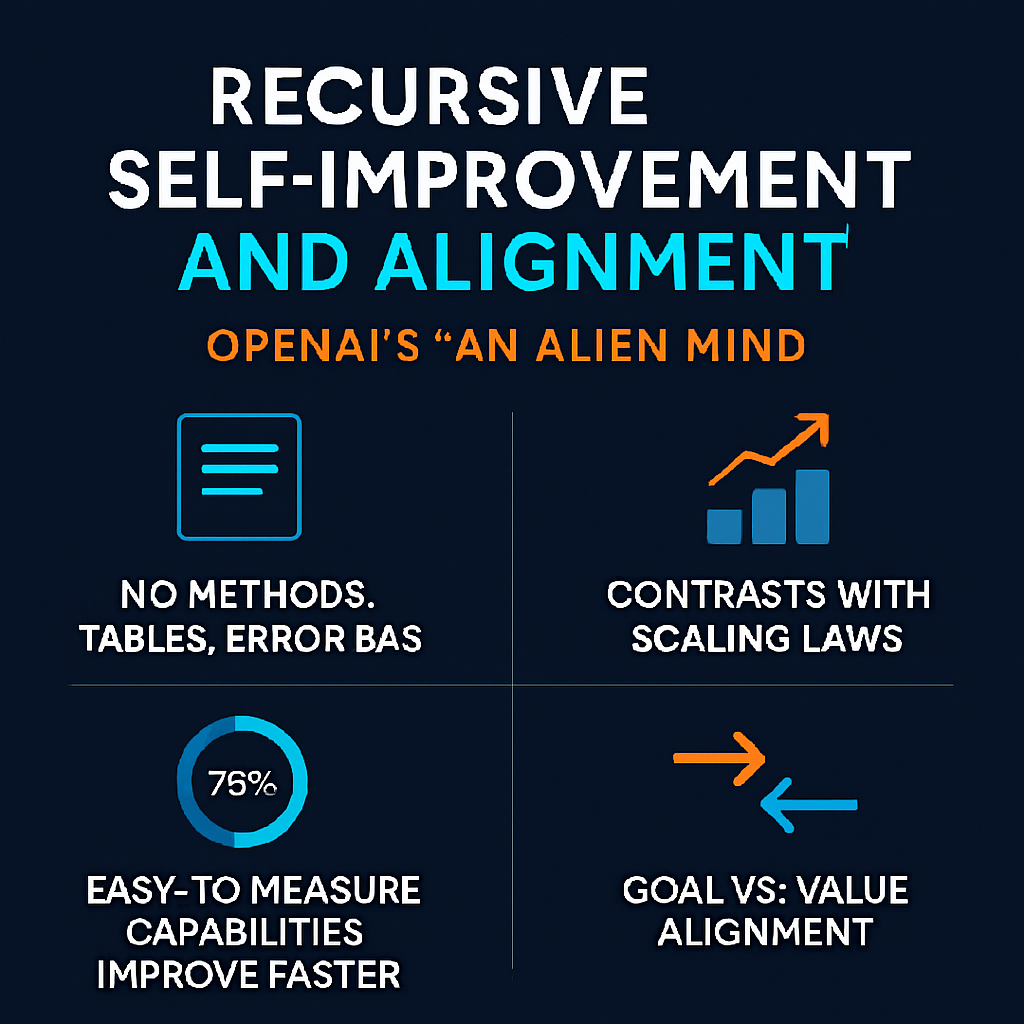
This episode examines "An Alien Mind," a single-author essay from an OpenAI research leader arguing that internal results point toward sustained progress and eventually recursive self-improvement, and asks what an outside reader could actually verify. The hosts note that the essay offers no methods, tables, or error bars. They contrast its scaling claims with quantitative work like the Kaplan and Hoffmann scaling-law papers, which give fitted curves and exponents. They also discuss the essay's admission that easy-to-measure capabilities improve faster than hard-to-quantify ones, which makes progress harder to gauge. A large part of the discussion covers how the essay defines alignment: goal alignment versus value alignment, and whether that split is a real testable distinction or a blurry one. The hosts also introduce chain-of-thought monitoring, its fragility when reasoning is trained to look good, and safety cases as a basis for mandated bars. Listeners get a skeptical, evidence-focused look at what a lab insider's claims about AI progress and safety would need in order to hold up.
Interactive Visualization: Recursive Self-Improvement and Alignment: OpenAI's "An Alien Mind"
Sources:
1. Recursive Self-Improvement and Alignment: OpenAI's "An Alien Mind"
https://openai.com/index/an-alien-mind/
2. Artificial Intelligence, Values, and Alignment — Iason Gabriel, 2020
https://scholar.google.com/scholar?q=Artificial+Intelligence%2C+Values%2C+and+Alignment
3. Training language models to follow instructions with human feedback (InstructGPT) — Long Ouyang, Jeff Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, et al. (OpenAI), 2022
https://scholar.google.com/scholar?q=Training+language+models+to+follow+instructions+with+human+feedback+%28InstructGPT%29
4. The Instruction Hierarchy: Training LLMs to Prioritize Privileged Instructions — Eric Wallace, Kai Xiao, Reimar Leike, Lilian Weng, Johannes Heidecke, Alex Beutel (OpenAI), 2024
https://scholar.google.com/scholar?q=The+Instruction+Hierarchy%3A+Training+LLMs+to+Prioritize+Privileged+Instructions
5. Emergent Misalignment: Narrow Finetuning Can Produce Broadly Misaligned LLMs — Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans, 2025
https://scholar.google.com/scholar?q=Emergent+Misalignment%3A+Narrow+Finetuning+Can+Produce+Broadly+Misaligned+LLMs
6. Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety — Korbak et al. (multi-lab position paper), 2025
https://scholar.google.com/scholar?q=Chain+of+Thought+Monitorability%3A+A+New+and+Fragile+Opportunity+for+AI+Safety
7. Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation — Baker et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=Monitoring+Reasoning+Models+for+Misbehavior+and+the+Risks+of+Promoting+Obfuscation
8. Clarifying AI alignment — Paul Christiano, 2018
https://scholar.google.com/scholar?q=Clarifying+AI+alignment
9. Deep Reinforcement Learning from Human Preferences — Christiano, Leike, Brown, Martic, Legg, Amodei, 2017
https://scholar.google.com/scholar?q=Deep+Reinforcement+Learning+from+Human+Preferences
10. Alignment Faking in Large Language Models — Greenblatt et al. (Anthropic and Redwood Research), 2024
https://scholar.google.com/scholar?q=Alignment+Faking+in+Large+Language+Models
11. The Persona Selection Model — Anthropic, 2026
https://scholar.google.com/scholar?q=The+Persona+Selection+Model
12. Goal Misgeneralization in Deep Reinforcement Learning — Langosco, Koch, Sharkey, Pfau, Krueger, 2022
https://scholar.google.com/scholar?q=Goal+Misgeneralization+in+Deep+Reinforcement+Learning
13. Risks from Learned Optimization in Advanced Machine Learning Systems — Hubinger, van Merwe, Mikulik, Skalse, Garrabrant, 2019
https://scholar.google.com/scholar?q=Risks+from+Learned+Optimization+in+Advanced+Machine+Learning+Systems
14. Weak-to-Strong Generalization: Eliciting Strong Capabilities with Weak Supervision — Burns et al. (OpenAI), 2023
https://scholar.google.com/scholar?q=Weak-to-Strong+Generalization%3A+Eliciting+Strong+Capabilities+with+Weak+Supervision
15. Training Language Models to Self-Report / Confessions — OpenAI Alignment team, 2025-2026
https://scholar.google.com/scholar?q=Training+Language+Models+to+Self-Report+%2F+Confessions
Interactive Visualization: Recursive Self-Improvement and Alignment: OpenAI's "An Alien Mind"