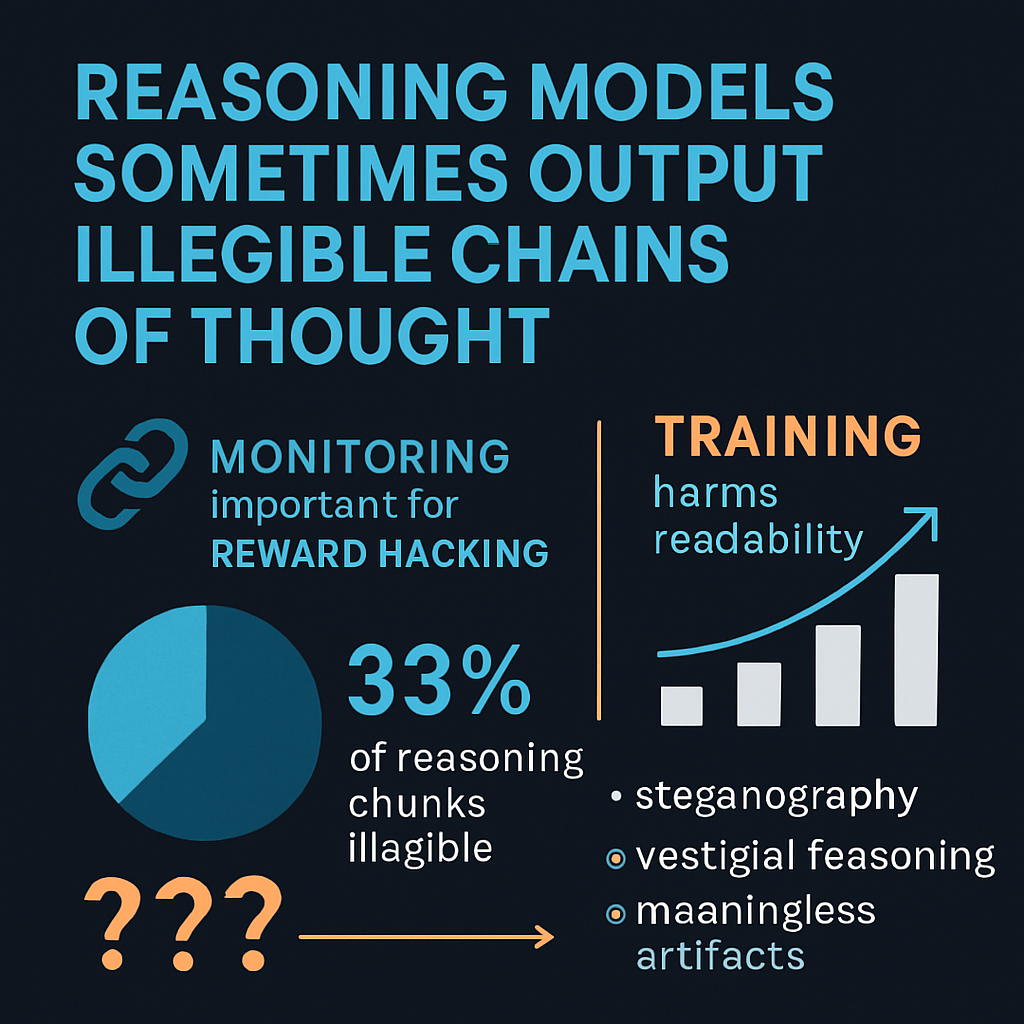
Reasoning Models Sometimes Output Illegible Chains of Thought
Oct 2, 2026
This episode examines a paper arguing that reasoning models trained with outcome-only reinforcement learning sometimes write stretches of chain-of-thought text that readers can't understand, then finish with a clean, correct answer. It explains why chain-of-thought monitoring matters for catching reward hacking and sabotage, and how training can erode readability indirectly, since the reward never requires legible reasoning. The discussion separates legibility from faithfulness. It also covers three candidate explanations for the garbled text: steganography, vestigial reasoning, and meaningless artifacts. The measurement setup uses a weaker model to score reasoning chunks for legibility across fourteen models on GPQA-Diamond questions with the answer choices removed. Listeners get a concrete look at how a safety tool might weaken without anyone directly pressuring the reasoning text.
Sources:
1. Reasoning Models Sometimes Output Illegible Chains of Thought — Arun Jose, 2025
http://arxiv.org/abs/2510.27338
2. Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety — Tomek Korbak, Mikita Balesni, et al. (multi-lab position paper), 2025
https://scholar.google.com/scholar?q=Chain+of+Thought+Monitorability%3A+A+New+and+Fragile+Opportunity+for+AI+Safety
3. Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation — Bowen Baker, Joost Huizinga, Leo Gao, et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=Monitoring+Reasoning+Models+for+Misbehavior+and+the+Risks+of+Promoting+Obfuscation
4. Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting — Miles Turpin, Julian Michael, Ethan Perez, Samuel R. Bowman, 2023
https://scholar.google.com/scholar?q=Language+Models+Don%27t+Always+Say+What+They+Think%3A+Unfaithful+Explanations+in+Chain-of-Thought+Prompting
5. DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-R1%3A+Incentivizing+Reasoning+Capability+in+LLMs+via+Reinforcement+Learning
6. Preventing Language Models From Hiding Their Reasoning — Fabien Roger, Ryan Greenblatt, 2023
https://scholar.google.com/scholar?q=Preventing+Language+Models+From+Hiding+Their+Reasoning
7. Secret Collusion among AI Agents: Multi-Agent Deception via Steganography — Sumeet Ramesh Motwani, Mikhail Baranchuk, Martin Strohmeier, et al., 2024
https://scholar.google.com/scholar?q=Secret+Collusion+among+AI+Agents%3A+Multi-Agent+Deception+via+Steganography
8. Think Before You Speak: Training Language Models With Pause Tokens — Sachin Goyal, Ziwei Ji, Ankit Singh Rawat, Aditya Krishna Menon, Sanjiv Kumar, Vaishnavh Nagarajan, 2023
https://scholar.google.com/scholar?q=Think+Before+You+Speak%3A+Training+Language+Models+With+Pause+Tokens
9. Let's Think Dot by Dot: Hidden Computation in Transformer Language Models — Jacob Pfau, William Merrill, Samuel R. Bowman, 2024
https://scholar.google.com/scholar?q=Let%27s+Think+Dot+by+Dot%3A+Hidden+Computation+in+Transformer+Language+Models
10. Do reasoning models use their scratchpad like we do? Evidence from distilling paraphrases — Roger, 2025
https://scholar.google.com/scholar?q=Do+reasoning+models+use+their+scratchpad+like+we+do%3F+Evidence+from+distilling+paraphrases
11. Prover-Verifier Games Improve Legibility of LLM Outputs — Kirchner, Chen, Edwards, Leike, McAleese, Burda, 2024
https://scholar.google.com/scholar?q=Prover-Verifier+Games+Improve+Legibility+of+LLM+Outputs
12. Training Large Language Models to Reason in a Continuous Latent Space (Coconut) — Hao et al., 2024
https://scholar.google.com/scholar?q=Training+Large+Language+Models+to+Reason+in+a+Continuous+Latent+Space+%28Coconut%29
13. When Chain of Thought is Necessary, Language Models Struggle to Evade Monitors — Emmons, Jenner, Elson, et al., 2025
https://scholar.google.com/scholar?q=When+Chain+of+Thought+is+Necessary%2C+Language+Models+Struggle+to+Evade+Monitors
14. Thought Anchors: Which LLM Reasoning Steps Matter? — Bogdan, Macar, Nanda, Conmy, 2025
https://scholar.google.com/scholar?q=Thought+Anchors%3A+Which+LLM+Reasoning+Steps+Matter%3F
15. Reasoning Models Don't Always Say What They Think — Chen et al., 2025
https://scholar.google.com/scholar?q=Reasoning+Models+Don%27t+Always+Say+What+They+Think