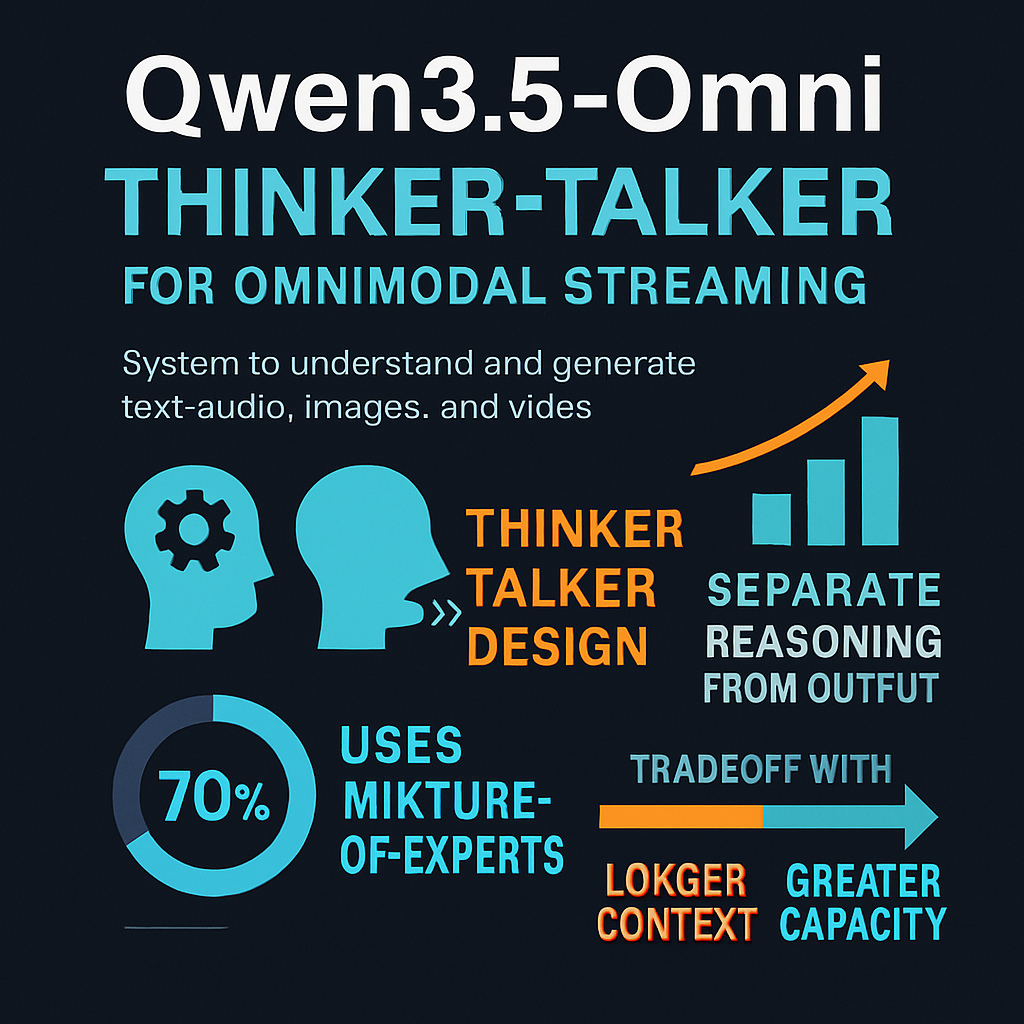
Qwen3.5-Omni Thinker-Talker for Omnimodal Streaming
Apr 21, 2026
This episode explores the Qwen3.5-Omni technical report as a significant update in omnimodal AI: a system designed to understand and generate text, audio, images, and video within one architecture. It unpacks the model’s Thinker–Talker design, arguing that separating multimodal reasoning from real-time output is especially important for speech, where latency and timing make generation far harder than standard text responses. The discussion also examines why the report leans on Mixture-of-Experts and hybrid attention instead of a plain dense transformer, highlighting the tradeoff between longer context and greater capacity versus routing complexity, infrastructure overhead, and serving difficulty. Listeners would find it interesting for its clear explanation of why claims like 256k context and stable low-latency streaming speech are technically ambitious—and why flashy multimodal demos often hide hard systems problems underneath.
Interactive Visualization: Qwen3.5-Omni Thinker-Talker for Omnimodal Streaming
Sources:
1. Qwen3.5-Omni Technical Report — Qwen Team, 2026
http://arxiv.org/abs/2604.15804
2. A Survey on Text-to-Speech Synthesis — Heiga Zen, Keiichi Tokuda, Alan W. Black, 2009
https://scholar.google.com/scholar?q=A+Survey+on+Text-to-Speech+Synthesis
3. Natural TTS Synthesis by Conditioning WaveNet on Mel Spectrogram Predictions — Jonathan Shen, Ruoming Pang, Ron J. Weiss, Mike Schuster, Navdeep Jaitly, et al., 2018
https://scholar.google.com/scholar?q=Natural+TTS+Synthesis+by+Conditioning+WaveNet+on+Mel+Spectrogram+Predictions
4. FastSpeech: Fast, Robust and Controllable Text to Speech — Yi Ren, Yangjun Ruan, Xu Tan, Tao Qin, Sheng Zhao, Zhou Zhao, Tie-Yan Liu, 2019
https://scholar.google.com/scholar?q=FastSpeech%3A+Fast%2C+Robust+and+Controllable+Text+to+Speech
5. Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers — Zalán Borsos, Matt Sharifi, Damien Vincent, Eugene Kharitonov, et al., 2023
https://scholar.google.com/scholar?q=Neural+Codec+Language+Models+are+Zero-Shot+Text+to+Speech+Synthesizers
6. Qwen2.5-Omni Technical Report — Xu et al., 2025
https://scholar.google.com/scholar?q=Qwen2.5-Omni+Technical+Report
7. Qwen3-Omni Technical Report — Xu et al., 2025
https://scholar.google.com/scholar?q=Qwen3-Omni+Technical+Report
8. Attention Is All You Need — Vaswani et al., 2017
https://scholar.google.com/scholar?q=Attention+Is+All+You+Need
9. Language Models are Few-Shot Learners — Brown et al., 2020
https://scholar.google.com/scholar?q=Language+Models+are+Few-Shot+Learners
10. GPT-4 Technical Report / GPT-4-class system references in the report — OpenAI, 2023
https://scholar.google.com/scholar?q=GPT-4+Technical+Report+%2F+GPT-4-class+system+references+in+the+report
11. Gemini technical reports referenced as Gemini Team (2024) — Gemini Team, 2024
https://scholar.google.com/scholar?q=Gemini+technical+reports+referenced+as+Gemini+Team+%282024%29
12. Audio language model / omni-audio model references cited as Chu et al. — Chu et al., 2023-2024
https://scholar.google.com/scholar?q=Audio+language+model+%2F+omni-audio+model+references+cited+as+Chu+et+al.
13. Recent native omnimodal system references cited as OpenAI (2024), Comanici et al. (2025), Xu et al. (2025a;b) — OpenAI; Comanici et al.; Xu et al., 2024-2025
https://scholar.google.com/scholar?q=Recent+native+omnimodal+system+references+cited+as+OpenAI+%282024%29%2C+Comanici+et+al.+%282025%29%2C+Xu+et+al.+%282025a%3Bb%29
14. TASTE: Text-Aligned Speech Tokenization and Embedding for Spoken Language Modeling — approx. recent speech/SLM authors, 2024/2025
https://scholar.google.com/scholar?q=TASTE%3A+Text-Aligned+Speech+Tokenization+and+Embedding+for+Spoken+Language+Modeling
15. dMel: Speech Tokenization Made Simple — approx. recent speech tokenizer authors, 2024/2025
https://scholar.google.com/scholar?q=dMel%3A+Speech+Tokenization+Made+Simple
16. TaDiCodec: Text-Aware Diffusion Speech Tokenizer for Speech Language Modeling — approx. recent codec/SLM authors, 2024/2025
https://scholar.google.com/scholar?q=TaDiCodec%3A+Text-Aware+Diffusion+Speech+Tokenizer+for+Speech+Language+Modeling
17. DC-Spin: A Speaker-Invariant Speech Tokenizer for Spoken Language Models — approx. recent spoken language model authors, 2024/2025
https://scholar.google.com/scholar?q=DC-Spin%3A+A+Speaker-Invariant+Speech+Tokenizer+for+Spoken+Language+Models
18. HyperAttention: Long-Context Attention in Near-Linear Time — approx. recent long-context attention authors, 2024/2025
https://scholar.google.com/scholar?q=HyperAttention%3A+Long-Context+Attention+in+Near-Linear+Time
19. On-the-Fly Adaptive Distillation of Transformer to Dual-State Linear Attention for Long-Context LLM Serving — approx. recent long-context serving authors, 2024/2025
https://scholar.google.com/scholar?q=On-the-Fly+Adaptive+Distillation+of+Transformer+to+Dual-State+Linear+Attention+for+Long-Context+LLM+Serving
20. MiniCPM-SALA: Hybridizing Sparse and Linear Attention for Efficient Long-Context Modeling — approx. MiniCPM team / recent efficient attention authors, 2024/2025
https://scholar.google.com/scholar?q=MiniCPM-SALA%3A+Hybridizing+Sparse+and+Linear+Attention+for+Efficient+Long-Context+Modeling
21. DeepSeekMoE: Towards Ultimate Expert Specialization in Mixture-of-Experts Language Models — DeepSeek team, 2024
https://scholar.google.com/scholar?q=DeepSeekMoE%3A+Towards+Ultimate+Expert+Specialization+in+Mixture-of-Experts+Language+Models
22. Dive into MoE: Diversity-Enhanced Reconstruction of Large Language Models from Dense into Mixture-of-Experts — approx. recent MoE reconstruction authors, 2024/2025
https://scholar.google.com/scholar?q=Dive+into+MoE%3A+Diversity-Enhanced+Reconstruction+of+Large+Language+Models+from+Dense+into+Mixture-of-Experts
23. AI Post Transformers: Qwen3Guard: Streaming Three-Way Safety Classification for LLMs — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-03-16-qwen3guard-streaming-three-way-safety-cl-26b0ef.mp3
24. AI Post Transformers: Nemotron 3 Super Hybrid Mamba-Transformer MoE — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-19-nemotron-3-super-hybrid-mamba-transforme-31ac75.mp3
25. AI Post Transformers: Mamba-3 for Efficient Sequence Modeling — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-16-mamba-3-for-efficient-sequence-modeling-97a22a.mp3
26. AI Post Transformers: Prefill-as-a-Service for Cross-Datacenter KV Cache — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-19-prefill-as-a-service-for-cross-datacente-7560be.mp3
27. AI Post Transformers: Kimi Linear: Efficient Expressive Attention Architecture — Hal Turing & Dr. Ada Shannon, 2025
https://podcast.do-not-panic.com/episodes/kimi-linear-efficient-expressive-attention-architecture/
28. AI Post Transformers: Memory Sparse Attention for 100M-Token Scaling — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-07-memory-sparse-attention-for-100m-token-s-377cff.mp3
Interactive Visualization: Qwen3.5-Omni Thinker-Talker for Omnimodal Streaming