Product Keys Give Transformers Million-Slot Memory Layers
Oct 13, 2026
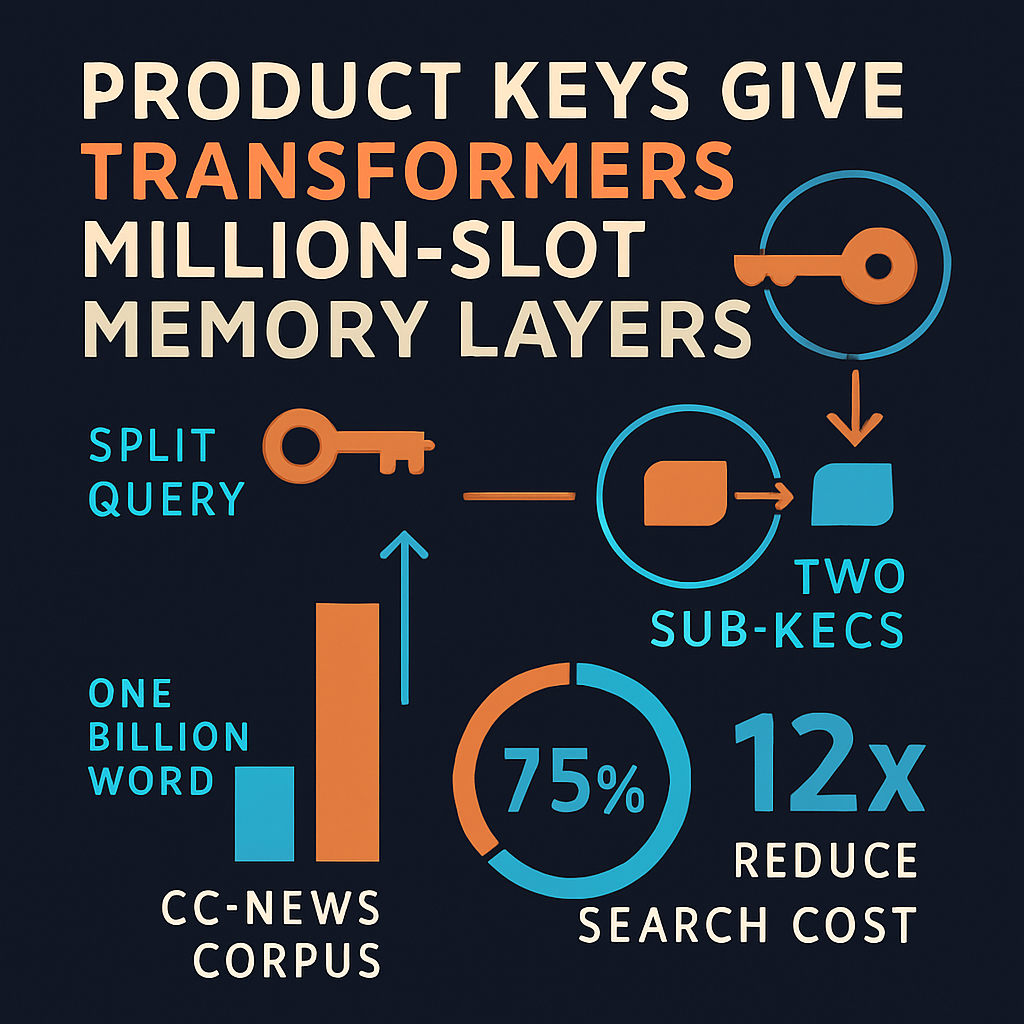
This episode examines "Large Memory Layers with Product Keys," which replaces a transformer's feed-forward network with a sparse memory of over a million trainable slots. The layer's central trick is splitting each query in half and scoring it against two small codebooks of sub-keys. This avoids scoring every key and cuts search cost by roughly a thousandfold. The hosts work through a toy example and the argument for why taking the top-k of each half still recovers the exact top-k. They also cover the motivation for training on the 28-billion-word CC-News corpus rather than One Billion Word, which overfits. Throughout, they stay skeptical of the headline claim that a 12-layer model with memory beats a 24-layer one at nearly twice the speed. They note that the paper doesn't test directly against approximate-nearest-neighbor memory or mixture-of-experts baselines, which makes it a useful listen for anyone wondering what "free capacity" actually costs.
Interactive Visualization: Product Keys Give Transformers Million-Slot Memory Layers
Sources:
1. Product Keys Give Transformers Million-Slot Memory Layers
https://proceedings.neurips.cc/paper_files/paper/2019/file/9d8df73a3cfbf3c5b47bc9b50f214aff-Paper.pdf
2. Large Memory Layers with Product Keys — Guillaume Lample, Alexandre Sablayrolles, Marc'Aurelio Ranzato, Ludovic Denoyer, Hervé Jégou, 2019
https://scholar.google.com/scholar?q=Large+Memory+Layers+with+Product+Keys
3. Product Quantization for Nearest Neighbor Search — Hervé Jégou, Matthijs Douze, Cordelia Schmid, 2011
https://scholar.google.com/scholar?q=Product+Quantization+for+Nearest+Neighbor+Search
4. Scaling Memory-Augmented Neural Networks with Sparse Reads and Writes — Jack W. Rae, Jonathan J. Hunt, Tim Harley, Ivo Danihelka, Andrew Senior, Greg Wayne, Alex Graves, Timothy Lillicrap, 2016
https://scholar.google.com/scholar?q=Scaling+Memory-Augmented+Neural+Networks+with+Sparse+Reads+and+Writes
5. Memory Layers at Scale — Vincent-Pierre Berges, Barlas Oğuz, Daniel Haziza, Wen-tau Yih, Luke Zettlemoyer, Gargi Ghosh, 2024
https://scholar.google.com/scholar?q=Memory+Layers+at+Scale
6. Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer — Noam Shazeer, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hinton, Jeff Dean, 2017
https://scholar.google.com/scholar?q=Outrageously+Large+Neural+Networks%3A+The+Sparsely-Gated+Mixture-of-Experts+Layer
7. Generalization through Memorization: Nearest Neighbor Language Models — Urvashi Khandelwal, Omer Levy, Dan Jurafsky, Luke Zettlemoyer, Mike Lewis, 2020
https://scholar.google.com/scholar?q=Generalization+through+Memorization%3A+Nearest+Neighbor+Language+Models
8. Transformer Feed-Forward Layers Are Key-Value Memories — Mor Geva, Roei Schuster, Jonathan Berant, Omer Levy, 2021
https://scholar.google.com/scholar?q=Transformer+Feed-Forward+Layers+Are+Key-Value+Memories
9. Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity — William Fedus, Barret Zoph, Noam Shazeer, 2021
https://scholar.google.com/scholar?q=Switch+Transformers%3A+Scaling+to+Trillion+Parameter+Models+with+Simple+and+Efficient+Sparsity
10. Improving language models by retrieving from trillions of tokens (RETRO) — Sebastian Borgeaud et al., 2022
https://scholar.google.com/scholar?q=Improving+language+models+by+retrieving+from+trillions+of+tokens+%28RETRO%29
11. Mixture of A Million Experts (PEER) — Xu Owen He, 2024
https://scholar.google.com/scholar?q=Mixture+of+A+Million+Experts+%28PEER%29
12. Scaling Laws for Fine-Grained Mixture of Experts — Jan Ludziejewski et al., 2024
https://scholar.google.com/scholar?q=Scaling+Laws+for+Fine-Grained+Mixture+of+Experts
13. Large Product Key Memory for Pretrained Language Models — Gyuwan Kim, Tae-Hwan Jung, 2020
https://scholar.google.com/scholar?q=Large+Product+Key+Memory+for+Pretrained+Language+Models
14. Adaptive Input Representations for Neural Language Modeling — Alexei Baevski, Michael Auli, 2019
https://scholar.google.com/scholar?q=Adaptive+Input+Representations+for+Neural+Language+Modeling
Interactive Visualization: Product Keys Give Transformers Million-Slot Memory Layers