PagedMoE: Cross-Precision Expert Caching for SSD-Resident MoE Inference
Nov 5, 2026
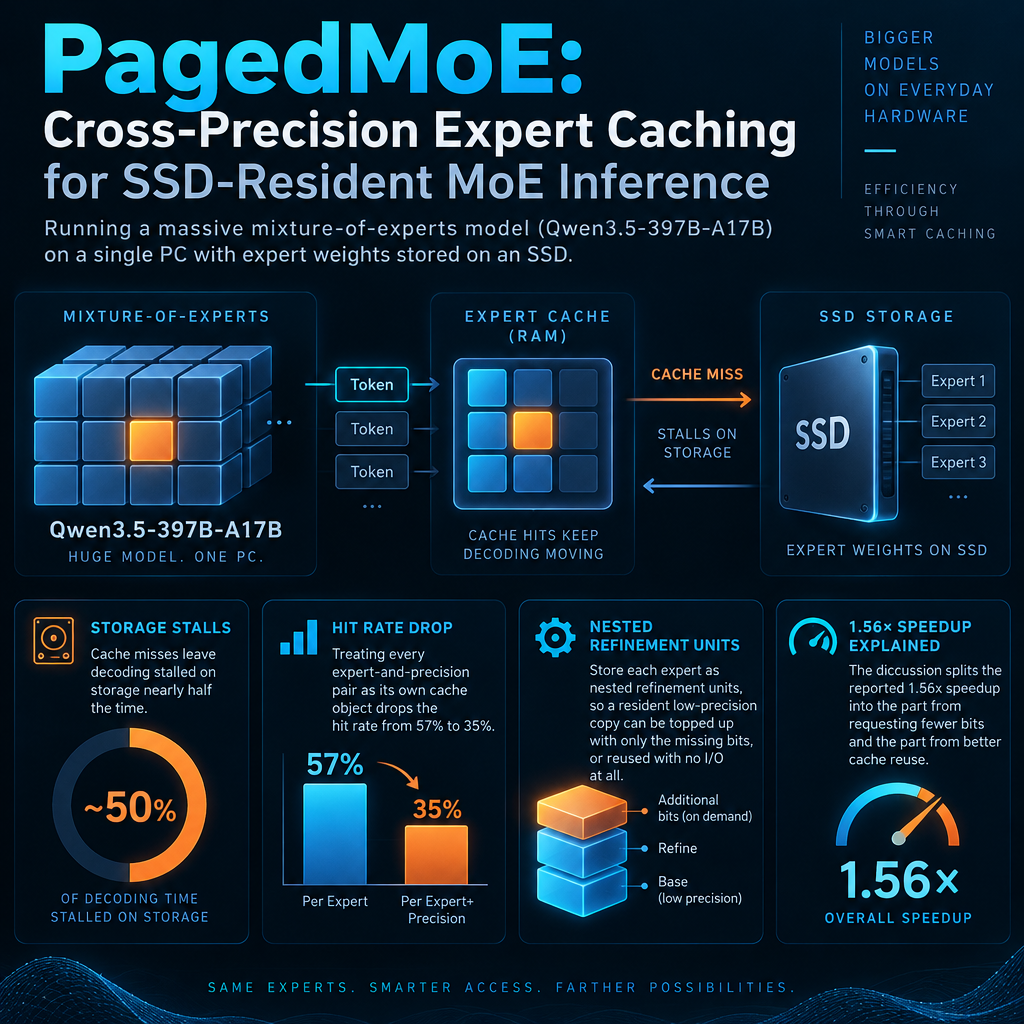
This episode examines PagedMoE, a system for running a huge mixture-of-experts model (Qwen3.5-397B-A17B) on a single PC with expert weights stored on an SSD. Cache misses leave decoding stalled on storage nearly half the time, and giving each token a different bit-width per expert would normally make that worse. Treating every expert-and-precision pair as its own cache object drops the hit rate from 57% to 35%. The paper's fix is to store each expert as nested refinement units, so a resident low-precision copy can be topped up with only the missing bits, or reused with no I/O at all. The discussion separates this idea from the prior work it borrows from (Matryoshka Quantization, Any-Precision LLM, SliceMoE, HOBBIT). It also splits the reported 1.56x speedup into the part from requesting fewer bits and the part from sharing cached bits across precisions. Listeners get a clear walk through the binary-tree codebook construction, the quantization-error numbers, and the limits of the evidence, such as a single-layer headroom study and no head-to-head comparison with SliceMoE.
Interactive Visualization: PagedMoE: Cross-Precision Expert Caching for SSD-Resident MoE Inference
Sources:
1. PagedMoE: Cross-Precision Expert Caching for Token-Level Dynamic Precision in SSD-Resident MoE Inference — Yutong Lin, Yingdi Shan, Shaoyuan Chen, Yuanyong Chen, Yongwei Wu, Mingxing Zhang, 2026
http://arxiv.org/abs/2611.03173
2. Fast Inference of Mixture-of-Experts Language Models with Offloading — Artyom Eliseev, Denis Mazur, 2023
https://scholar.google.com/scholar?q=Fast+Inference+of+Mixture-of-Experts+Language+Models+with+Offloading
3. MoE-Infinity: Efficient MoE Inference on Personal Machines with Sparsity-Aware Expert Cache — Leyang Xue, Yao Fu, Zhan Lu, Luo Mai, Mahesh Marina, 2024 (arXiv; later revisions)
https://scholar.google.com/scholar?q=MoE-Infinity%3A+Efficient+MoE+Inference+on+Personal+Machines+with+Sparsity-Aware+Expert+Cache
4. EdgeMoE: Empowering Sparse Large Language Models on Mobile Devices — Rongjie Yi, Liwei Guo, Shiyun Wei, Ao Zhou, Shangguang Wang, Mengwei Xu, 2023
https://scholar.google.com/scholar?q=EdgeMoE%3A+Empowering+Sparse+Large+Language+Models+on+Mobile+Devices
5. LLM in a Flash: Efficient Large Language Model Inference with Limited Memory — Keivan Alizadeh, Iman Mirzadeh, et al. (Apple), 2023
https://scholar.google.com/scholar?q=LLM+in+a+Flash%3A+Efficient+Large+Language+Model+Inference+with+Limited+Memory
6. HOBBIT: A Mixed Precision Expert Offloading System for Fast MoE Inference — Peng Tang, Jiacheng Liu, Xiaofeng Hou, et al., 2024
https://scholar.google.com/scholar?q=HOBBIT%3A+A+Mixed+Precision+Expert+Offloading+System+for+Fast+MoE+Inference
7. Mixture Compressor for Mixture-of-Experts LLMs Gains More (MC) — Wei Huang, Yue Liao, Jianhui Liu, et al., 2024
https://scholar.google.com/scholar?q=Mixture+Compressor+for+Mixture-of-Experts+LLMs+Gains+More+%28MC%29
8. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers — Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh, 2022
https://scholar.google.com/scholar?q=GPTQ%3A+Accurate+Post-Training+Quantization+for+Generative+Pre-trained+Transformers
9. Microscaling Data Formats for Deep Learning (OCP MX specification) — Bita Darvish Rouhani et al. (Microsoft, AMD, Arm, Intel, Meta, NVIDIA, Qualcomm), 2023
https://scholar.google.com/scholar?q=Microscaling+Data+Formats+for+Deep+Learning+%28OCP+MX+specification%29
10. Any-Precision LLM: Low-Cost Deployment of Multiple, Different-Sized LLMs — Yeonhong Park, Jake Hyun, SangLyul Cho, Bonggeun Sim, Jae W. Lee, 2024
https://scholar.google.com/scholar?q=Any-Precision+LLM%3A+Low-Cost+Deployment+of+Multiple%2C+Different-Sized+LLMs
11. Matryoshka Quantization — Pranav Nair, Puranjay Datta, Jeff Dean, Prateek Jain, Aditya Kusupati, 2025
https://scholar.google.com/scholar?q=Matryoshka+Quantization
12. QTIP: Quantization with Trellises and Incoherence Processing — Albert Tseng, Qingyao Sun, David Hou, Christopher De Sa, 2024
https://scholar.google.com/scholar?q=QTIP%3A+Quantization+with+Trellises+and+Incoherence+Processing
13. Stripes: Bit-Serial Deep Neural Network Computing — Patrick Judd, Jorge Albericio, Tayler Hetherington, Tor Aamodt, Andreas Moshovos, 2016
https://scholar.google.com/scholar?q=Stripes%3A+Bit-Serial+Deep+Neural+Network+Computing
14. SliceMoE: Bit-Sliced Expert Caching under Miss-Rate Constraints for Efficient MoE Inference — Yuseon Choi, Sangjin Kim, Jungjun Oh, Gwangtae Park, Byeongcheol Kim, Hoi-Jun Yoo, 2026
https://scholar.google.com/scholar?q=SliceMoE%3A+Bit-Sliced+Expert+Caching+under+Miss-Rate+Constraints+for+Efficient+MoE+Inference
15. D²MoE: Dual Routing and Dynamic Scheduling for Efficient On-Device MoE-based LLM Serving — Haodong Wang, Qihua Zhou, Zicong Hong, Song Guo, 2025
https://scholar.google.com/scholar?q=D%C2%B2MoE%3A+Dual+Routing+and+Dynamic+Scheduling+for+Efficient+On-Device+MoE-based+LLM+Serving
16. DyMoE: Dynamic Expert Orchestration with Mixed-Precision Quantization for Efficient MoE Inference on Edge — Yuegui Huang, Zhiyuan Fang, Weiqi Luo, Ruoyu Wu, Wuhui Chen, Zibin Zheng, 2026
https://scholar.google.com/scholar?q=DyMoE%3A+Dynamic+Expert+Orchestration+with+Mixed-Precision+Quantization+for+Efficient+MoE+Inference+on+Edge
17. MxMoE: Mixed-precision Quantization for MoE with Accuracy and Performance Co-Design — Haojie Duanmu, Xiuhong Li, Zhihang Yuan, Size Zheng, Jiangfei Duan, Xingcheng Zhang, Dahua Lin, 2025
https://scholar.google.com/scholar?q=MxMoE%3A+Mixed-precision+Quantization+for+MoE+with+Accuracy+and+Performance+Co-Design
18. GEMQ: Global Expert-Level Mixed-Precision Quantization for MoE LLMs — Jianing Deng, Song Wang, Dongwei Wang, Zijie Liu, Tianlong Chen, Huanrui Yang, Jingtong Hu, 2026
https://scholar.google.com/scholar?q=GEMQ%3A+Global+Expert-Level+Mixed-Precision+Quantization+for+MoE+LLMs
19. KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models — Hongtao Chen, Weiyu Xie, Boxin Zhang, et al., 2025
https://scholar.google.com/scholar?q=KTransformers%3A+Unleashing+the+Full+Potential+of+CPU%2FGPU+Hybrid+Inference+for+MoE+Models
20. T-MAC: CPU Renaissance via Table Lookup for Low-Bit LLM Deployment on Edge — Jianyu Wei, Shijie Cao, Ting Cao, Lingxiao Ma, Lei Wang, Yanyong Zhang, Mao Yang, 2025
https://scholar.google.com/scholar?q=T-MAC%3A+CPU+Renaissance+via+Table+Lookup+for+Low-Bit+LLM+Deployment+on+Edge
21. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
22. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
23. Speculative MoE / expert prefetching works (e.g., Pre-gated MoE, ProMoE, AdapMoE) — Various, 2024–2025
https://scholar.google.com/scholar?q=Speculative+MoE+%2F+expert+prefetching+works+%28e.g.%2C+Pre-gated+MoE%2C+ProMoE%2C+AdapMoE%29
Interactive Visualization: PagedMoE: Cross-Precision Expert Caching for SSD-Resident MoE Inference
1. PagedMoE: Cross-Precision Expert Caching for Token-Level Dynamic Precision in SSD-Resident MoE Inference — Yutong Lin, Yingdi Shan, Shaoyuan Chen, Yuanyong Chen, Yongwei Wu, Mingxing Zhang, 2026
http://arxiv.org/abs/2611.03173
2. Fast Inference of Mixture-of-Experts Language Models with Offloading — Artyom Eliseev, Denis Mazur, 2023
https://scholar.google.com/scholar?q=Fast+Inference+of+Mixture-of-Experts+Language+Models+with+Offloading
3. MoE-Infinity: Efficient MoE Inference on Personal Machines with Sparsity-Aware Expert Cache — Leyang Xue, Yao Fu, Zhan Lu, Luo Mai, Mahesh Marina, 2024 (arXiv; later revisions)
https://scholar.google.com/scholar?q=MoE-Infinity%3A+Efficient+MoE+Inference+on+Personal+Machines+with+Sparsity-Aware+Expert+Cache
4. EdgeMoE: Empowering Sparse Large Language Models on Mobile Devices — Rongjie Yi, Liwei Guo, Shiyun Wei, Ao Zhou, Shangguang Wang, Mengwei Xu, 2023
https://scholar.google.com/scholar?q=EdgeMoE%3A+Empowering+Sparse+Large+Language+Models+on+Mobile+Devices
5. LLM in a Flash: Efficient Large Language Model Inference with Limited Memory — Keivan Alizadeh, Iman Mirzadeh, et al. (Apple), 2023
https://scholar.google.com/scholar?q=LLM+in+a+Flash%3A+Efficient+Large+Language+Model+Inference+with+Limited+Memory
6. HOBBIT: A Mixed Precision Expert Offloading System for Fast MoE Inference — Peng Tang, Jiacheng Liu, Xiaofeng Hou, et al., 2024
https://scholar.google.com/scholar?q=HOBBIT%3A+A+Mixed+Precision+Expert+Offloading+System+for+Fast+MoE+Inference
7. Mixture Compressor for Mixture-of-Experts LLMs Gains More (MC) — Wei Huang, Yue Liao, Jianhui Liu, et al., 2024
https://scholar.google.com/scholar?q=Mixture+Compressor+for+Mixture-of-Experts+LLMs+Gains+More+%28MC%29
8. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers — Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh, 2022
https://scholar.google.com/scholar?q=GPTQ%3A+Accurate+Post-Training+Quantization+for+Generative+Pre-trained+Transformers
9. Microscaling Data Formats for Deep Learning (OCP MX specification) — Bita Darvish Rouhani et al. (Microsoft, AMD, Arm, Intel, Meta, NVIDIA, Qualcomm), 2023
https://scholar.google.com/scholar?q=Microscaling+Data+Formats+for+Deep+Learning+%28OCP+MX+specification%29
10. Any-Precision LLM: Low-Cost Deployment of Multiple, Different-Sized LLMs — Yeonhong Park, Jake Hyun, SangLyul Cho, Bonggeun Sim, Jae W. Lee, 2024
https://scholar.google.com/scholar?q=Any-Precision+LLM%3A+Low-Cost+Deployment+of+Multiple%2C+Different-Sized+LLMs
11. Matryoshka Quantization — Pranav Nair, Puranjay Datta, Jeff Dean, Prateek Jain, Aditya Kusupati, 2025
https://scholar.google.com/scholar?q=Matryoshka+Quantization
12. QTIP: Quantization with Trellises and Incoherence Processing — Albert Tseng, Qingyao Sun, David Hou, Christopher De Sa, 2024
https://scholar.google.com/scholar?q=QTIP%3A+Quantization+with+Trellises+and+Incoherence+Processing
13. Stripes: Bit-Serial Deep Neural Network Computing — Patrick Judd, Jorge Albericio, Tayler Hetherington, Tor Aamodt, Andreas Moshovos, 2016
https://scholar.google.com/scholar?q=Stripes%3A+Bit-Serial+Deep+Neural+Network+Computing
14. SliceMoE: Bit-Sliced Expert Caching under Miss-Rate Constraints for Efficient MoE Inference — Yuseon Choi, Sangjin Kim, Jungjun Oh, Gwangtae Park, Byeongcheol Kim, Hoi-Jun Yoo, 2026
https://scholar.google.com/scholar?q=SliceMoE%3A+Bit-Sliced+Expert+Caching+under+Miss-Rate+Constraints+for+Efficient+MoE+Inference
15. D²MoE: Dual Routing and Dynamic Scheduling for Efficient On-Device MoE-based LLM Serving — Haodong Wang, Qihua Zhou, Zicong Hong, Song Guo, 2025
https://scholar.google.com/scholar?q=D%C2%B2MoE%3A+Dual+Routing+and+Dynamic+Scheduling+for+Efficient+On-Device+MoE-based+LLM+Serving
16. DyMoE: Dynamic Expert Orchestration with Mixed-Precision Quantization for Efficient MoE Inference on Edge — Yuegui Huang, Zhiyuan Fang, Weiqi Luo, Ruoyu Wu, Wuhui Chen, Zibin Zheng, 2026
https://scholar.google.com/scholar?q=DyMoE%3A+Dynamic+Expert+Orchestration+with+Mixed-Precision+Quantization+for+Efficient+MoE+Inference+on+Edge
17. MxMoE: Mixed-precision Quantization for MoE with Accuracy and Performance Co-Design — Haojie Duanmu, Xiuhong Li, Zhihang Yuan, Size Zheng, Jiangfei Duan, Xingcheng Zhang, Dahua Lin, 2025
https://scholar.google.com/scholar?q=MxMoE%3A+Mixed-precision+Quantization+for+MoE+with+Accuracy+and+Performance+Co-Design
18. GEMQ: Global Expert-Level Mixed-Precision Quantization for MoE LLMs — Jianing Deng, Song Wang, Dongwei Wang, Zijie Liu, Tianlong Chen, Huanrui Yang, Jingtong Hu, 2026
https://scholar.google.com/scholar?q=GEMQ%3A+Global+Expert-Level+Mixed-Precision+Quantization+for+MoE+LLMs
19. KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models — Hongtao Chen, Weiyu Xie, Boxin Zhang, et al., 2025
https://scholar.google.com/scholar?q=KTransformers%3A+Unleashing+the+Full+Potential+of+CPU%2FGPU+Hybrid+Inference+for+MoE+Models
20. T-MAC: CPU Renaissance via Table Lookup for Low-Bit LLM Deployment on Edge — Jianyu Wei, Shijie Cao, Ting Cao, Lingxiao Ma, Lei Wang, Yanyong Zhang, Mao Yang, 2025
https://scholar.google.com/scholar?q=T-MAC%3A+CPU+Renaissance+via+Table+Lookup+for+Low-Bit+LLM+Deployment+on+Edge
21. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
22. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
23. Speculative MoE / expert prefetching works (e.g., Pre-gated MoE, ProMoE, AdapMoE) — Various, 2024–2025
https://scholar.google.com/scholar?q=Speculative+MoE+%2F+expert+prefetching+works+%28e.g.%2C+Pre-gated+MoE%2C+ProMoE%2C+AdapMoE%29
Interactive Visualization: PagedMoE: Cross-Precision Expert Caching for SSD-Resident MoE Inference