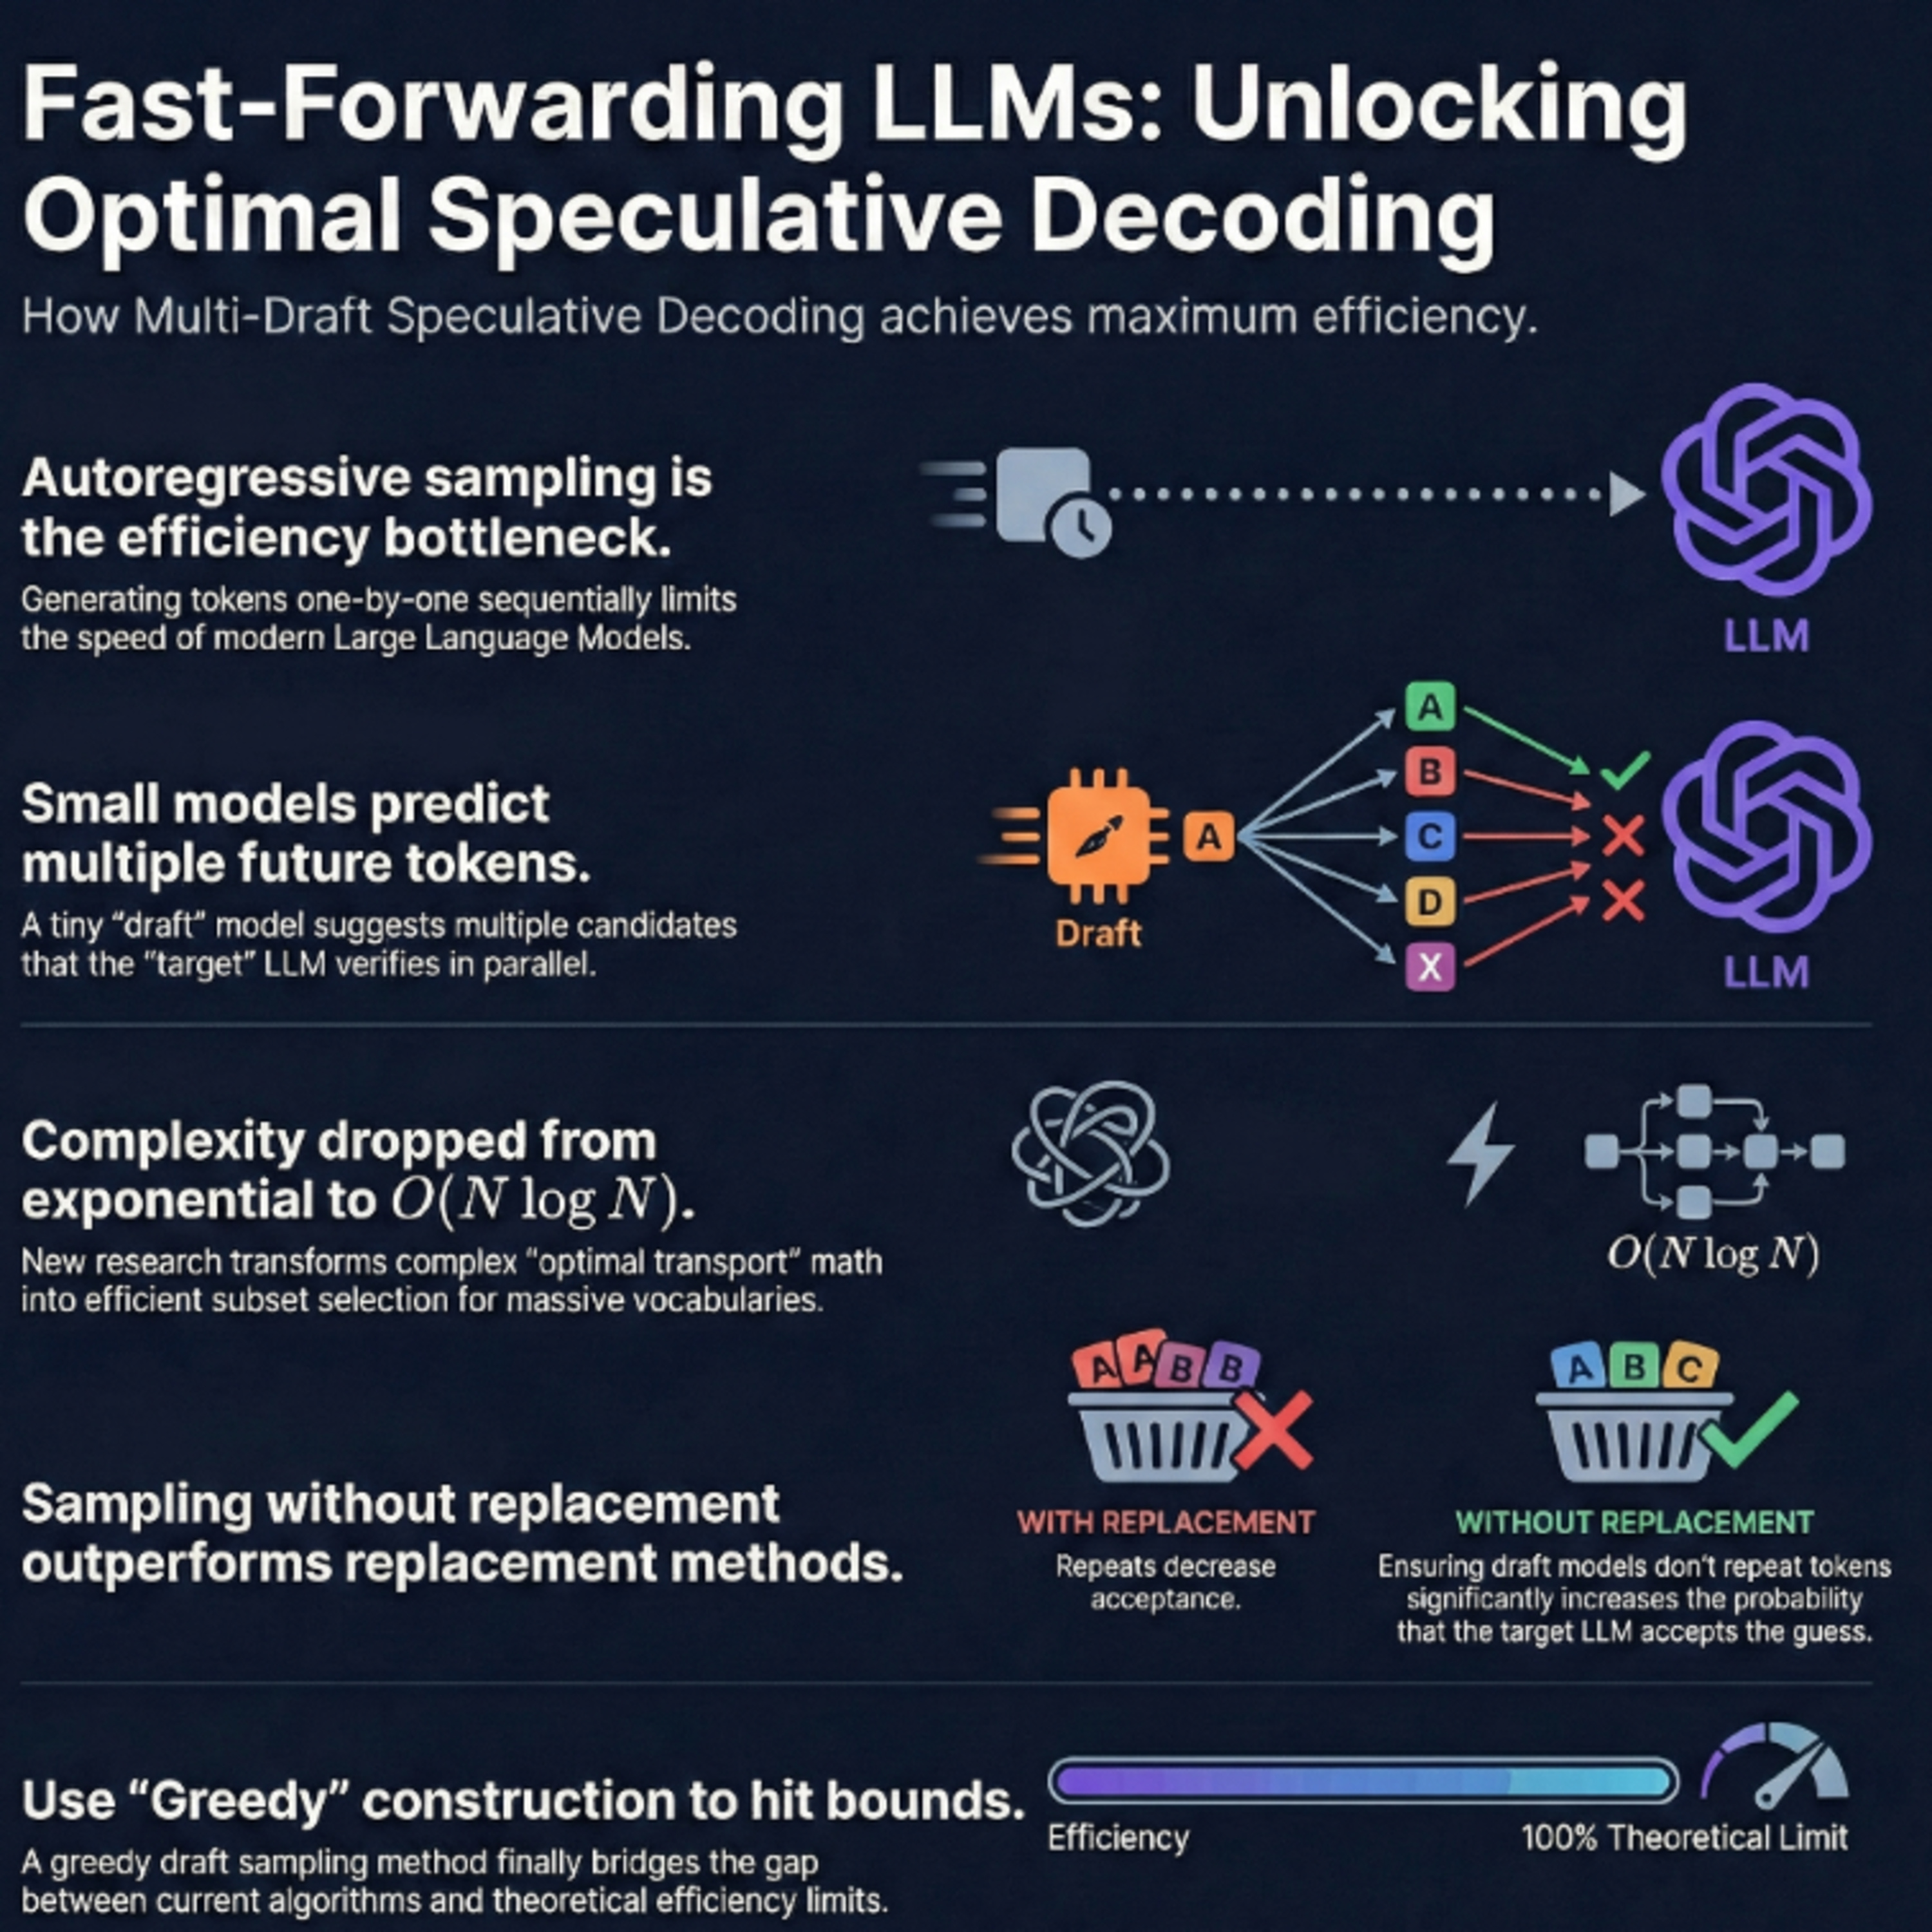
Optimizing Verification and Efficiency in Multi-Draft Speculative Decoding
Feb 26, 2026
These sources explore advanced techniques for accelerating Large Language Model (LLM) inference through speculative decoding, a process where smaller "draft" models predict tokens for a larger "target" model to verify in parallel. A primary focus is Multi-Draft Speculative Decoding (MDSD), which uses multiple draft sequences to increase the probability of acceptance and reduce latency. Researchers have introduced SpecHub to simplify complex optimization problems into manageable linear programming, while others utilize optimal transport theory and q-convexity to reach theoretical efficiency upper bounds. Additionally, the Hierarchical Speculative Decoding (HSD) framework stacks multiple models into a tiered structure, allowing each level to verify the one below it. Collectively, these papers provide mathematical proofs, sampling algorithms, and hierarchical strategies designed to maximize token acceptance rates and minimize computational overhead.
Sources:
1)January 22 2025Towards Optimal Multi-draft Speculative DecodingZhengmian Hu, Tong Zheng, Vignesh Viswanathan, Ziyi Chen, Ryan A. Rossi, Yihan Wu, Dinesh Manocha, Heng Huang.2)2024SpecHub: Provable Acceleration to Multi-Draft Speculative DecodingLehigh University, Samsung Research America, University of MarylandRyan Sun, Tianyi Zhou, Xun Chen, Lichao Sun
https://aclanthology.org/2024.emnlp-main.1148.pdf.3
https://arxiv.org/pdf/2410.18234.4
https://arxiv.org/pdf/2510.01336.5
https://arxiv.org/pdf/2510.19705.