On-Policy Self-Distillation for Advanced LLM Reasoning
Feb 6, 2026
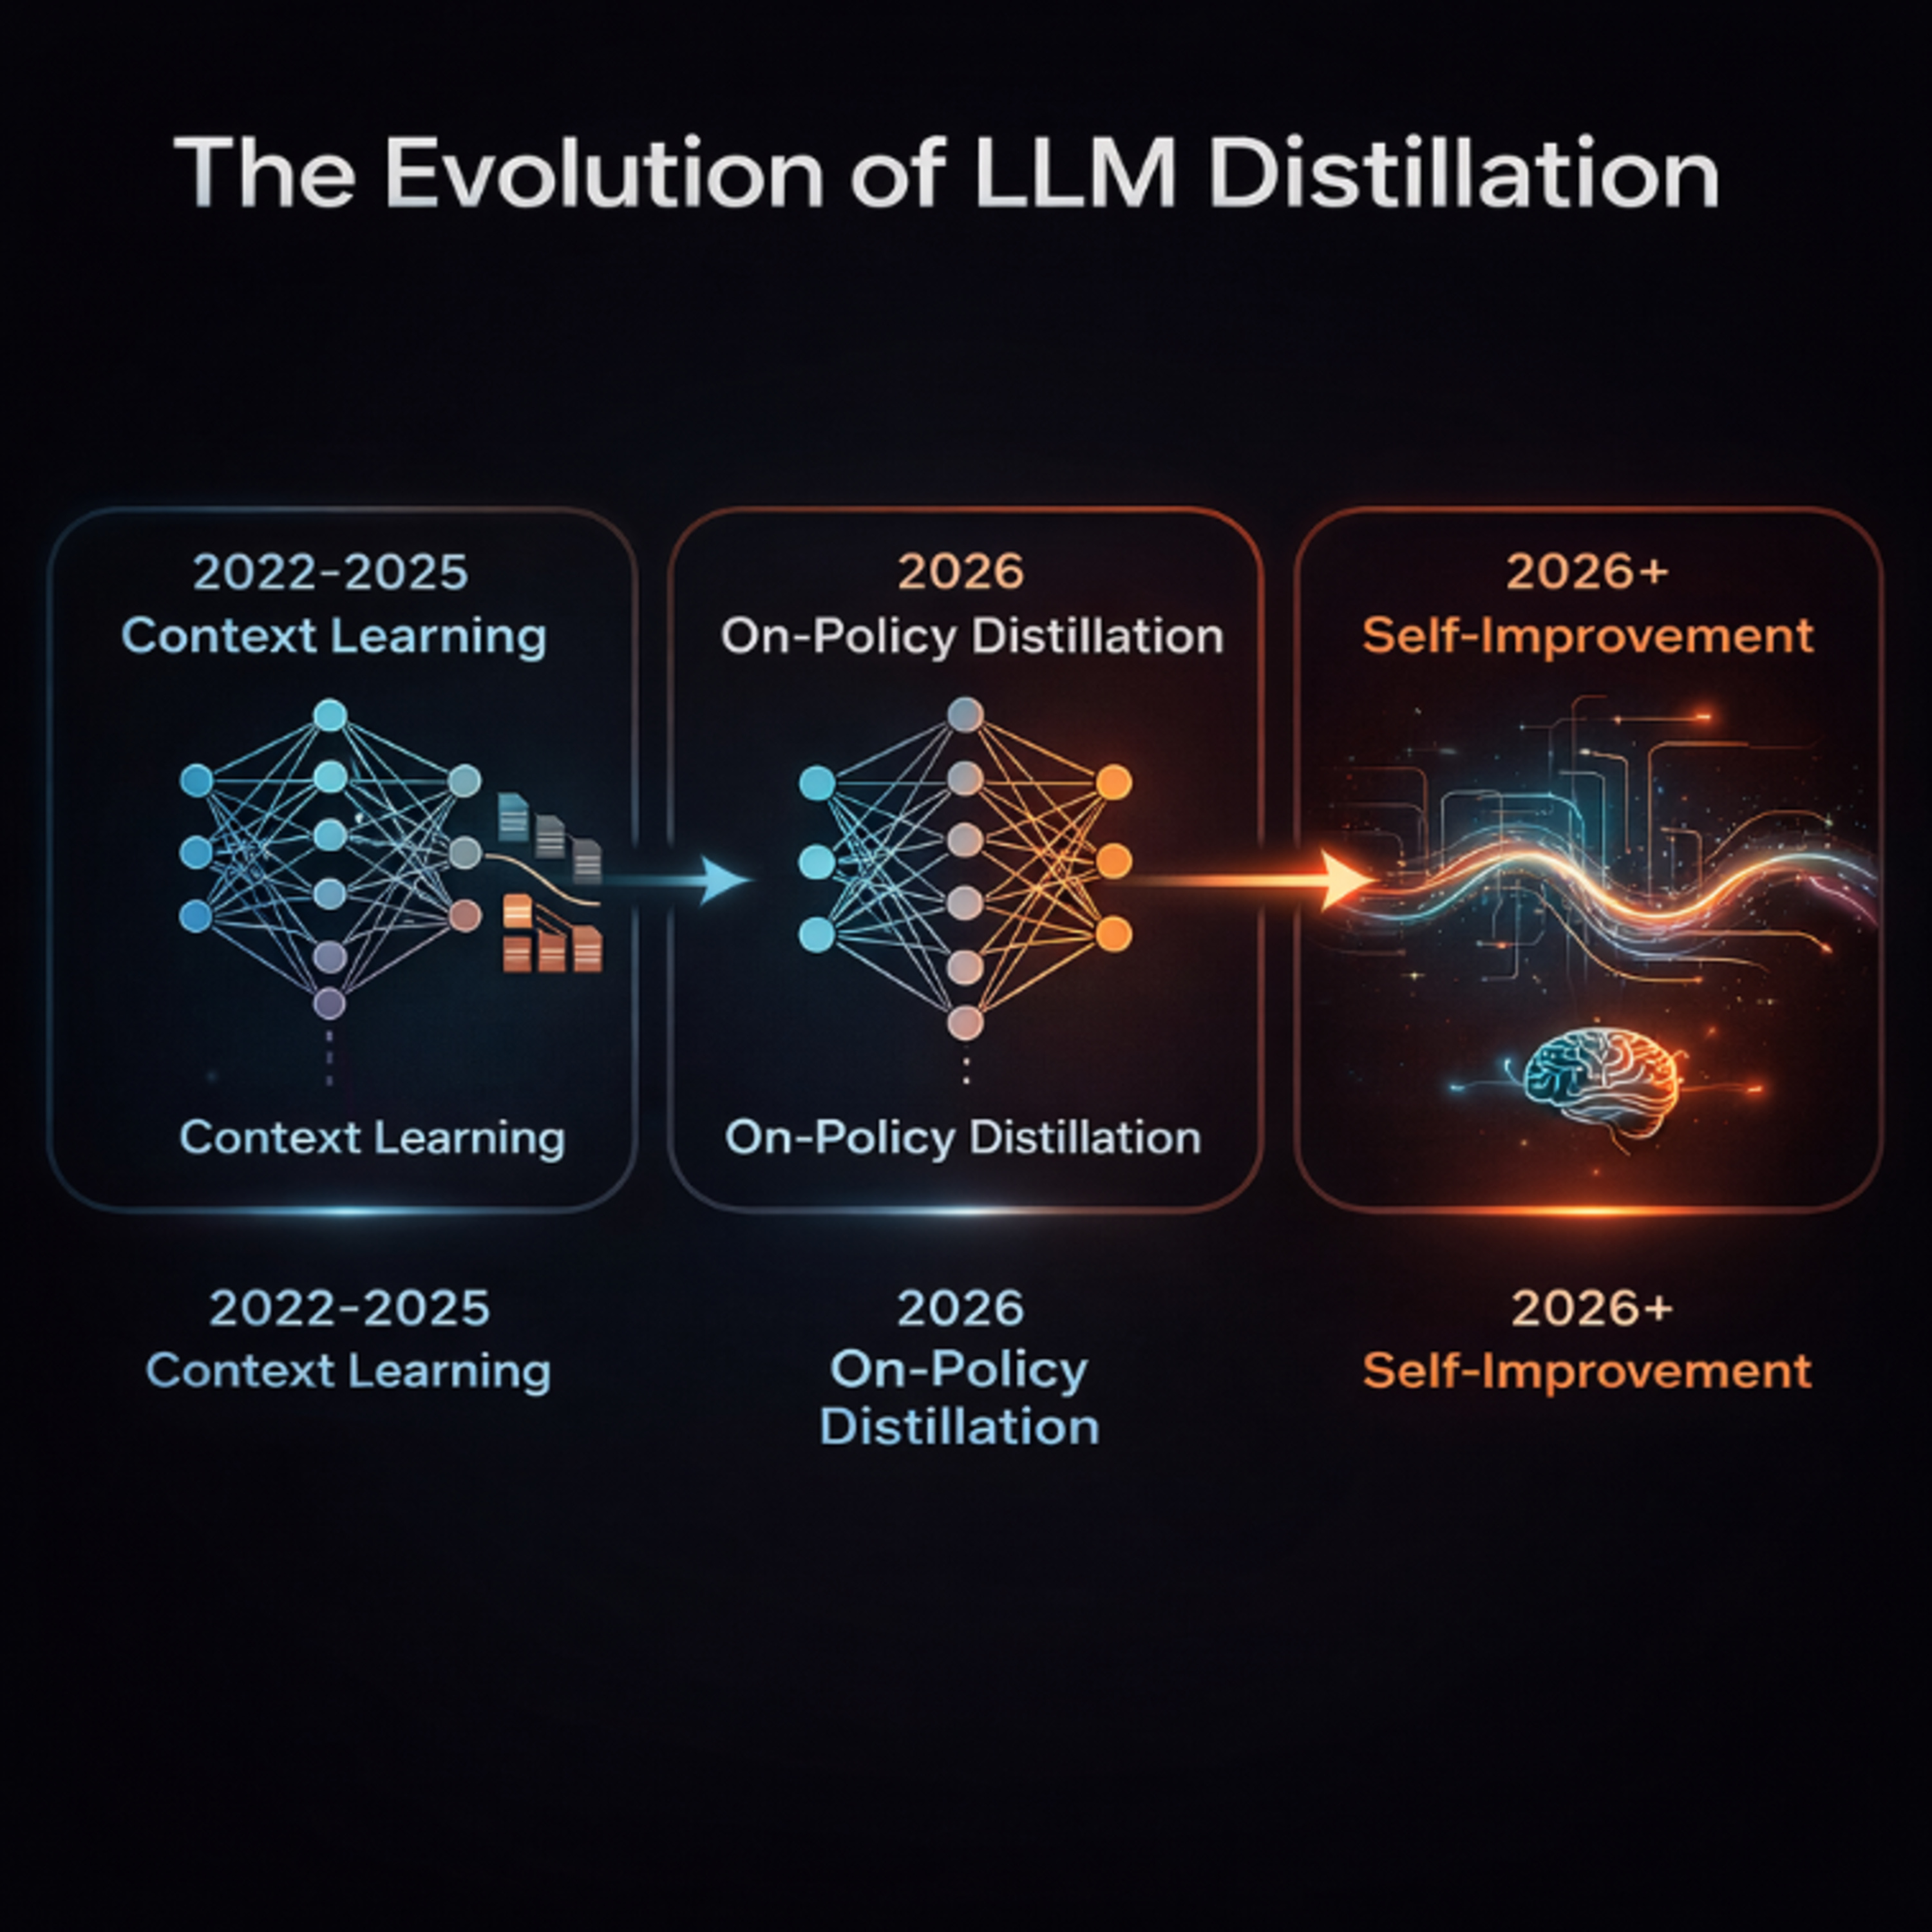
On-policy distillation improves LLM reasoning by using a teacher model to provide dense, token-level feedback on the student's own samples. Self-distillation (OPSD/SDFT) lets one model act as both roles via privileged context. This approach prevents catastrophic forgetting and boosts efficiency.
Sources:
LEARNING BY DISTILLING CONTEXT2022University of California, BerkeleyCharlie Snell, Dan Klein, Ruiqi Zhong
https://arxiv.org/pdf/2209.15189ON-POLICY
https://arxiv.org/pdf/2306.13649On-Policy
https://thinkingmachines.ai/blog/on-policy-distillationSelf-Distilled
https://arxiv.org/pdf/2601.18734SELF-DISTILLATION
https://arxiv.org/pdf/2601.19897