Next-Latent Prediction Lets Transformers Learn Compact World Models
Sep 27, 2026
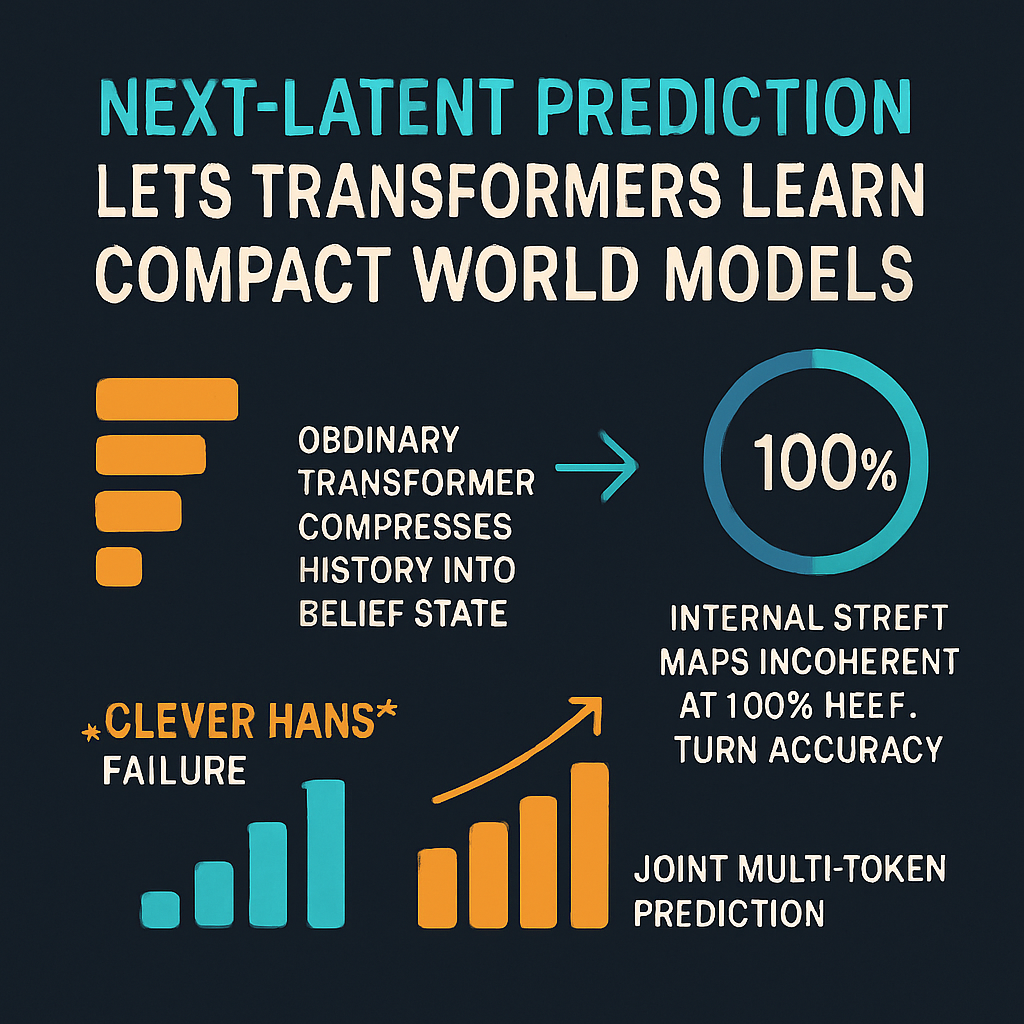
This episode explores "Next-Latent Prediction Transformers Learn Compact World Models," a Microsoft Research paper proposing a small auxiliary loss that pushes an ordinary transformer to compress its history into a compact belief state, with no architecture changes. It covers why transformers lack the built-in compression that recurrent networks get from a fixed-size state, using the Manhattan taxi study where models reached 100 percent next-turn accuracy while their internal street maps were incoherent. It also covers the Clever Hans failure of myopic next-token training and the earlier fixes from the same group. The Belief State Transformer offers a guarantee at more than double the parameters, and joint multi-token prediction is cheaper but depends on an unknown k-observability horizon. NextLat borrows from reinforcement learning by training a small dynamics network to predict the next hidden state from the current state and token, which also allows self-speculative decoding with flexible draft lengths. The discussion then turns to the theorem behind the method and the conditions needed for the latents to converge to belief states.
Interactive Visualization: Next-Latent Prediction Lets Transformers Learn Compact World Models
Sources:
1. Next-Latent Prediction Transformers Learn Compact World Models — Jayden Teoh, Manan Tomar, Kwangjun Ahn, Edward S. Hu, Tim Pearce, Pratyusha Sharma, Akshay Krishnamurthy, Riashat Islam, Alex Lamb, John Langford, 2025
http://arxiv.org/abs/2511.05963
2. Bootstrap Your Own Latent: A New Approach to Self-Supervised Learning — Jean-Bastien Grill, Florian Strub, Florent Altché, Corentin Tallec, Pierre H. Richemond, et al., 2020
https://scholar.google.com/scholar?q=Bootstrap+Your+Own+Latent%3A+A+New+Approach+to+Self-Supervised+Learning
3. Data-Efficient Reinforcement Learning with Self-Predictive Representations — Max Schwarzer, Ankesh Anand, Rishab Goel, R. Devon Hjelm, Aaron Courville, Philip Bachman, 2021
https://scholar.google.com/scholar?q=Data-Efficient+Reinforcement+Learning+with+Self-Predictive+Representations
4. Better & Faster Large Language Models via Multi-token Prediction — Fabian Gloeckle, Badr Youbi Idrissi, Baptiste Rozière, David Lopez-Paz, Gabriel Synnaeve, 2024
https://scholar.google.com/scholar?q=Better+%26+Faster+Large+Language+Models+via+Multi-token+Prediction
5. A Path Towards Autonomous Machine Intelligence (JEPA position paper) — Yann LeCun, 2022
https://scholar.google.com/scholar?q=A+Path+Towards+Autonomous+Machine+Intelligence+%28JEPA+position+paper%29
6. Planning and Acting in Partially Observable Stochastic Domains — Leslie Pack Kaelbling, Michael L. Littman, Anthony R. Cassandra, 1998
https://scholar.google.com/scholar?q=Planning+and+Acting+in+Partially+Observable+Stochastic+Domains
7. Predictive Representations of State — Michael L. Littman, Richard S. Sutton, Satinder Singh, 2001
https://scholar.google.com/scholar?q=Predictive+Representations+of+State
8. The Belief State Transformer — Edward S. Hu, Kwangjun Ahn, Qinghua Liu, Haoran Xu, Manan Tomar, Ada Langford, Dinesh Jayaraman, Alex Lamb, John Langford, 2024
https://scholar.google.com/scholar?q=The+Belief+State+Transformer
9. Transformers Represent Belief State Geometry in their Residual Stream — Adam S. Shai, Sarah E. Marzen, Lucas Teixeira, Alexander Gietelink Oldenziel, Paul M. Riechers, 2024
https://scholar.google.com/scholar?q=Transformers+Represent+Belief+State+Geometry+in+their+Residual+Stream
10. Fast Inference from Transformers via Speculative Decoding — Yaniv Leviathan, Matan Kalman, Yossi Matias, 2023
https://scholar.google.com/scholar?q=Fast+Inference+from+Transformers+via+Speculative+Decoding
11. Accelerating Large Language Model Decoding with Speculative Sampling — Charlie Chen, Sebastian Borgeaud, Geoffrey Irving, Jean-Baptiste Lespiau, Laurent Sifre, John Jumper, 2023
https://scholar.google.com/scholar?q=Accelerating+Large+Language+Model+Decoding+with+Speculative+Sampling
12. Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads — Tianle Cai, Yuhong Li, Zhengyang Geng, Hongwu Peng, Jason D. Lee, Deming Chen, Tri Dao, 2024
https://scholar.google.com/scholar?q=Medusa%3A+Simple+LLM+Inference+Acceleration+Framework+with+Multiple+Decoding+Heads
13. EAGLE: Speculative Sampling Requires Rethinking Feature Uncertainty — Yuhui Li, Fangyun Wei, Chao Zhang, Hongyang Zhang, 2024
https://scholar.google.com/scholar?q=EAGLE%3A+Speculative+Sampling+Requires+Rethinking+Feature+Uncertainty
14. Efficient Joint Prediction of Multiple Future Tokens (JTP) — Kwangjun Ahn, Alex Lamb, John Langford, 2025
https://scholar.google.com/scholar?q=Efficient+Joint+Prediction+of+Multiple+Future+Tokens+%28JTP%29
15. Bridging State and History Representations: Understanding Self-Predictive RL — Tianwei Ni, Benjamin Eysenbach, Erfan SeyedSalehi, Michel Ma, Clement Gehring, Aditya Mahajan, Pierre-Luc Bacon, 2024
https://scholar.google.com/scholar?q=Bridging+State+and+History+Representations%3A+Understanding+Self-Predictive+RL
16. The Pitfalls of Next-Token Prediction — Gregor Bachmann, Vaishnavh Nagarajan, 2024
https://scholar.google.com/scholar?q=The+Pitfalls+of+Next-Token+Prediction
17. Evaluating the World Model Implicit in a Generative Model — Keyon Vafa, Justin Y. Chen, Ashesh Rambachan, Jon Kleinberg, Sendhil Mullainathan, 2024
https://scholar.google.com/scholar?q=Evaluating+the+World+Model+Implicit+in+a+Generative+Model
18. EAGLE: Speculative Sampling Requires Rethinking Feature Uncertainty / EAGLE-2 — Yuhui Li, Fangyun Wei, Chao Zhang, Hongyang Zhang, 2024
https://scholar.google.com/scholar?q=EAGLE%3A+Speculative+Sampling+Requires+Rethinking+Feature+Uncertainty+%2F+EAGLE-2
19. Data-Efficient Reinforcement Learning with Self-Predictive Representations (SPR) — Max Schwarzer, Ankesh Anand, Rishab Goel, R Devon Hjelm, Aaron Courville, Philip Bachman, 2021
https://scholar.google.com/scholar?q=Data-Efficient+Reinforcement+Learning+with+Self-Predictive+Representations+%28SPR%29
20. The Parallelism Tradeoff: Limitations of Log-Precision Transformers — William Merrill, Ashish Sabharwal, 2023
https://scholar.google.com/scholar?q=The+Parallelism+Tradeoff%3A+Limitations+of+Log-Precision+Transformers
21. The Illusion of State in State-Space Models — William Merrill, Jackson Petty, Ashish Sabharwal, 2025
https://scholar.google.com/scholar?q=The+Illusion+of+State+in+State-Space+Models
22. LLM-JEPA: Large Language Models Meet Joint Embedding Predictive Architectures — Hai Huang, Yann LeCun, Randall Balestriero, 2025
https://scholar.google.com/scholar?q=LLM-JEPA%3A+Large+Language+Models+Meet+Joint+Embedding+Predictive+Architectures
23. Emergent Representations of Program Semantics / Transformers Represent Belief State Geometry in their Residual Stream — Adam S. Shai, Sarah E. Marzen, Lucas Teixeira, Alexander Gietelmark Oldenziel, Paul M. Riechers, 2024
https://scholar.google.com/scholar?q=Emergent+Representations+of+Program+Semantics+%2F+Transformers+Represent+Belief+State+Geometry+in+their+Residual+Stream
24. Multi-token prediction in DeepSeek-V3 (Technical Report) — DeepSeek-AI (Aixin Liu et al.), 2024
https://scholar.google.com/scholar?q=Multi-token+prediction+in+DeepSeek-V3+%28Technical+Report%29
Interactive Visualization: Next-Latent Prediction Lets Transformers Learn Compact World Models