More Agents Is All You Need: Sampling Beats Scaling
Sep 30, 2026
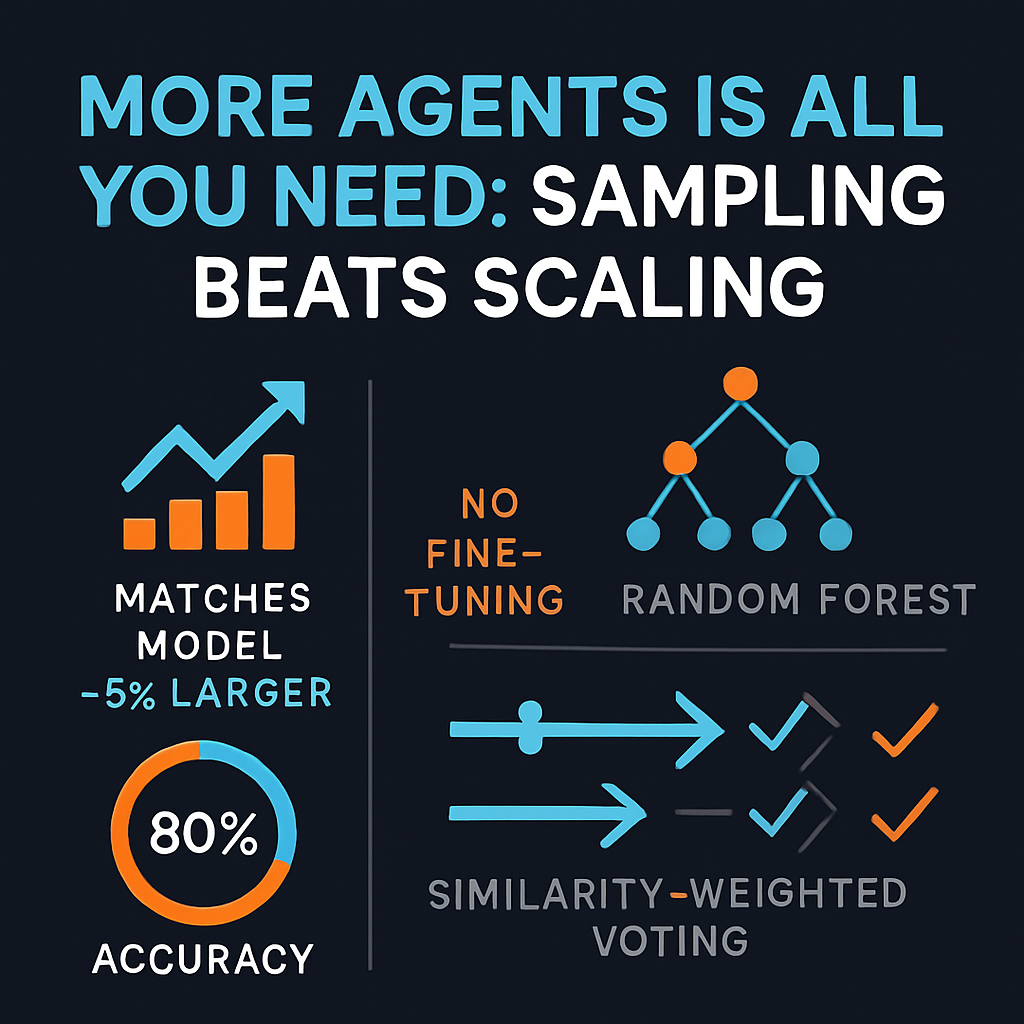
This episode examines "More Agents Is All You Need," a Tencent paper showing that sampling a single LLM multiple times and voting on the outputs can match the performance of a model roughly five times larger — no fine-tuning, no multi-agent debate, no specialized prompting required. The discussion traces this "Agent Forest" method back to classical ensemble techniques like Random Forests and connects it to inference-time compute scaling, contrasting it with precursors like self-consistency decoding (CoT-SC) and LLM-Debate. A key mechanism explored is similarity-weighted majority voting, which lets the same simple sampling-and-voting recipe generalize across very different tasks like math, multiple choice, and code generation. Listeners interested in cheap alternatives to scaling up model size, or in how far simple statistical tricks can push LLM performance, will find the systematic breakdown of when and why this scaling trend holds — and where it starts to fail — particularly compelling.
Interactive Visualization: More Agents Is All You Need: Sampling Beats Scaling
Sources:
1. More Agents Is All You Need — Junyou Li, Qin Zhang, Yangbin Yu, Qiang Fu, Deheng Ye, 2024
http://arxiv.org/abs/2402.05120
2. Self-Consistency Improves Chain of Thought Reasoning in Language Models — Xuezhi Wang, Jason Wei, Dale Schuurmans, Quoc Le, Ed Chi, Sharan Narang, Aakanksha Chowdhery, Denny Zhou, 2022 (ICLR 2023)
https://scholar.google.com/scholar?q=Self-Consistency+Improves+Chain+of+Thought+Reasoning+in+Language+Models
3. Chain-of-Thought Prompting Elicits Reasoning in Large Language Models — Jason Wei, Xuezhi Wang, Dale Schuurmans, Maarten Bosma, Brian Ichter, Fei Xia, Ed Chi, Quoc Le, Denny Zhou, 2022
https://scholar.google.com/scholar?q=Chain-of-Thought+Prompting+Elicits+Reasoning+in+Large+Language+Models
4. Rationale-Augmented Ensembles in Language Models — Xuezhi Wang, Jason Wei, Dale Schuurmans, Quoc Le, Ed Chi, Denny Zhou, 2022
https://scholar.google.com/scholar?q=Rationale-Augmented+Ensembles+in+Language+Models
5. LLM-Debate: Improving Factuality and Reasoning in Language Models through Multiagent Debate — Yilun Du, Shuang Li, Antonio Torralba, Joshua B. Tenenbaum, Igor Mordatch, 2023
https://scholar.google.com/scholar?q=LLM-Debate%3A+Improving+Factuality+and+Reasoning+in+Language+Models+through+Multiagent+Debate
6. AI Agents That Matter — Sayash Kapoor, Benedikt Stroebl, Zachary S. Siegel, Nitya Nadgir, Arvind Narayanan, 2024
https://scholar.google.com/scholar?q=AI+Agents+That+Matter
7. Improving Factuality and Reasoning in Language Models through Multiagent Debate — Yilun Du, Shuang Li, Antonio Torralba, Joshua B. Tenenbaum, Igor Mordatch, 2023
https://scholar.google.com/scholar?q=Improving+Factuality+and+Reasoning+in+Language+Models+through+Multiagent+Debate
8. Blending Is All You Need: Cheaper, Better Alternative to Trillion-Parameters LLM — Xiaoding Lu, Adian Liusie, Vyas Raina, Yuwen Zhang, William Beauchamp, 2024
https://scholar.google.com/scholar?q=Blending+Is+All+You+Need%3A+Cheaper%2C+Better+Alternative+to+Trillion-Parameters+LLM
9. Knowledge Fusion of Large Language Models — Fanqi Wan, Xinting Huang, Deng Cai, Xiaojun Quan, Wei Bi, Shuming Shi, 2024
https://scholar.google.com/scholar?q=Knowledge+Fusion+of+Large+Language+Models
Interactive Visualization: More Agents Is All You Need: Sampling Beats Scaling