Model-Aware Tokenizer Transfer: Fitting New Vocabularies to Frozen LLMs
Oct 12, 2026
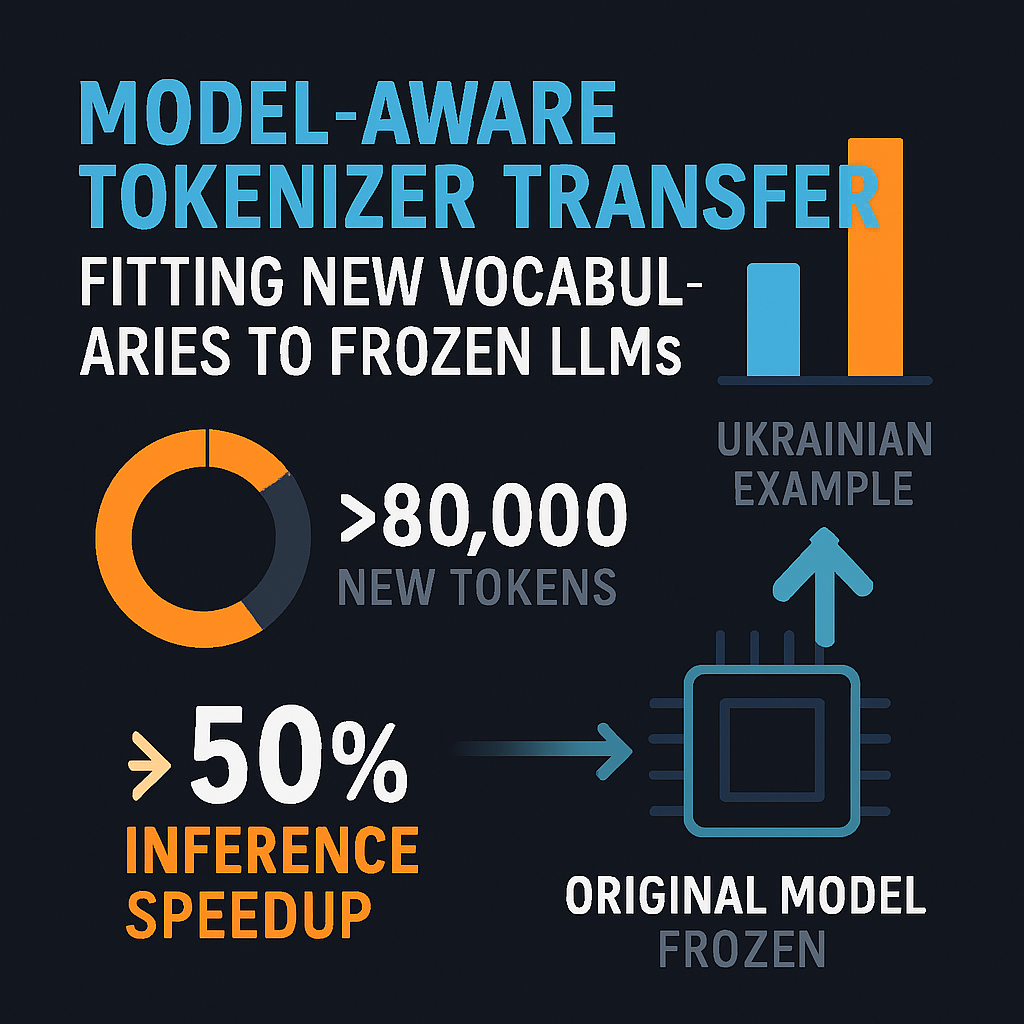
This episode explores Model-Aware Tokenizer Transfer, a method for swapping a language model's tokenizer without breaking it. The motivating example is Gemma 3 on Ukrainian, where a Ukrainian-focused vocabulary raises compression from about 2.98 to 4.44 characters per token, a near 50% inference speedup. The cost is more than 80,000 new tokens with no trained embeddings. The discussion explains why the transformer body is tied to its original vocabulary. It then contrasts earlier approaches with the new one. WECHSEL, FOCUS, Transtokenizers and TokAlign build new vectors by averaging similar old ones. Zero-Shot Tokenizer Transfer and Token Distillation use the model's own behavior. The paper's approach, Attention Influence Modeling, treats the original model as a frozen teacher and trains only the new-token embeddings so the student's attention outputs match the teacher's. The two tokenizers segment text differently, so the comparison is made over the smallest character spans that neither tokenizer splits. The episode also flags an unverified assumption that the feed-forward layers will handle correctly placed inputs, and it sets up a test of whether attention is really what drives the gains.
Interactive Visualization: Model-Aware Tokenizer Transfer: Fitting New Vocabularies to Frozen LLMs
Sources:
1. Model-Aware Tokenizer Transfer — Mykola Haltiuk, Aleksander Smywinski-Pohl, 2025
http://arxiv.org/abs/2510.21954
2. As Good as New. How to Successfully Recycle English GPT-2 to Make Models for Other Languages — Wietse de Vries, Malvina Nissim, 2020 (arXiv; Findings of ACL 2021)
https://scholar.google.com/scholar?q=As+Good+as+New.+How+to+Successfully+Recycle+English+GPT-2+to+Make+Models+for+Other+Languages
3. WECHSEL: Effective initialization of subword embeddings for cross-lingual transfer of monolingual language models — Benjamin Minixhofer, Fabian Paischer, Navid Rekabsaz, 2022 (NAACL)
https://scholar.google.com/scholar?q=WECHSEL%3A+Effective+initialization+of+subword+embeddings+for+cross-lingual+transfer+of+monolingual+language+models
4. FOCUS: Effective Embedding Initialization for Monolingual Specialization of Multilingual Models — Konstantin Dobler, Gerard de Melo, 2023 (EMNLP)
https://scholar.google.com/scholar?q=FOCUS%3A+Effective+Embedding+Initialization+for+Monolingual+Specialization+of+Multilingual+Models
5. Zero-Shot Tokenizer Transfer — Benjamin Minixhofer, Edoardo M. Ponti, Ivan Vulić, 2024 (NeurIPS)
https://scholar.google.com/scholar?q=Zero-Shot+Tokenizer+Transfer
6. Paying More Attention to Attention: Improving the Performance of Convolutional Neural Networks via Attention Transfer — Sergey Zagoruyko, Nikos Komodakis, 2017 (ICLR)
https://scholar.google.com/scholar?q=Paying+More+Attention+to+Attention%3A+Improving+the+Performance+of+Convolutional+Neural+Networks+via+Attention+Transfer
7. MiniLM: Deep Self-Attention Distillation for Task-Agnostic Compression of Pre-Trained Transformers — Wenhui Wang, Furu Wei, Li Dong, Hangbo Bao, Nan Yang, Ming Zhou, 2020 (NeurIPS)
https://scholar.google.com/scholar?q=MiniLM%3A+Deep+Self-Attention+Distillation+for+Task-Agnostic+Compression+of+Pre-Trained+Transformers
8. LoLCATs: On Low-Rank Linearizing of Large Language Models — Michael Zhang, Simran Arora, Rahul Chalamala, Alan Wu, Benjamin Spector, Aaryan Singhal, Krithik Ramesh, Christopher Ré, 2024
https://scholar.google.com/scholar?q=LoLCATs%3A+On+Low-Rank+Linearizing+of+Large+Language+Models
9. Token Distillation: Attention-aware input embeddings for new tokens — Konstantin Dobler, Desmond Elliott, Gerard de Melo, 2026
https://scholar.google.com/scholar?q=Token+Distillation%3A+Attention-aware+input+embeddings+for+new+tokens
10. Trans-tokenization and cross-lingual vocabulary transfers: Language adaptation of LLMs for low-resource NLP — François Remy et al., 2024
https://scholar.google.com/scholar?q=Trans-tokenization+and+cross-lingual+vocabulary+transfers%3A+Language+adaptation+of+LLMs+for+low-resource+NLP
11. TokAlign: Efficient vocabulary adaptation via token alignment — Chong Li, Jiajun Zhang, Chengqing Zong, 2025
https://scholar.google.com/scholar?q=TokAlign%3A+Efficient+vocabulary+adaptation+via+token+alignment
12. Transformer Feed-Forward Layers Are Key-Value Memories — Mor Geva, Roei Schuster, Jonathan Berant, Omer Levy, 2021
https://scholar.google.com/scholar?q=Transformer+Feed-Forward+Layers+Are+Key-Value+Memories
13. From Tokens to Words: On the Inner Lexicon of LLMs — Guy Kaplan, Matanel Oren, Yuval Reif, Roy Schwartz, 2024
https://scholar.google.com/scholar?q=From+Tokens+to+Words%3A+On+the+Inner+Lexicon+of+LLMs
14. Byte Latent Transformer: Patches Scale Better Than Tokens — Artidoro Pagnoni et al., 2025
https://scholar.google.com/scholar?q=Byte+Latent+Transformer%3A+Patches+Scale+Better+Than+Tokens
15. Tokenizer Choice for LLM Training: Negligible or Crucial? — Mehdi Ali et al., 2024
https://scholar.google.com/scholar?q=Tokenizer+Choice+for+LLM+Training%3A+Negligible+or+Crucial%3F
16. Large Vocabulary Size Improves Large Language Models — Sho Takase et al., 2025
https://scholar.google.com/scholar?q=Large+Vocabulary+Size+Improves+Large+Language+Models
Interactive Visualization: Model-Aware Tokenizer Transfer: Fitting New Vocabularies to Frozen LLMs