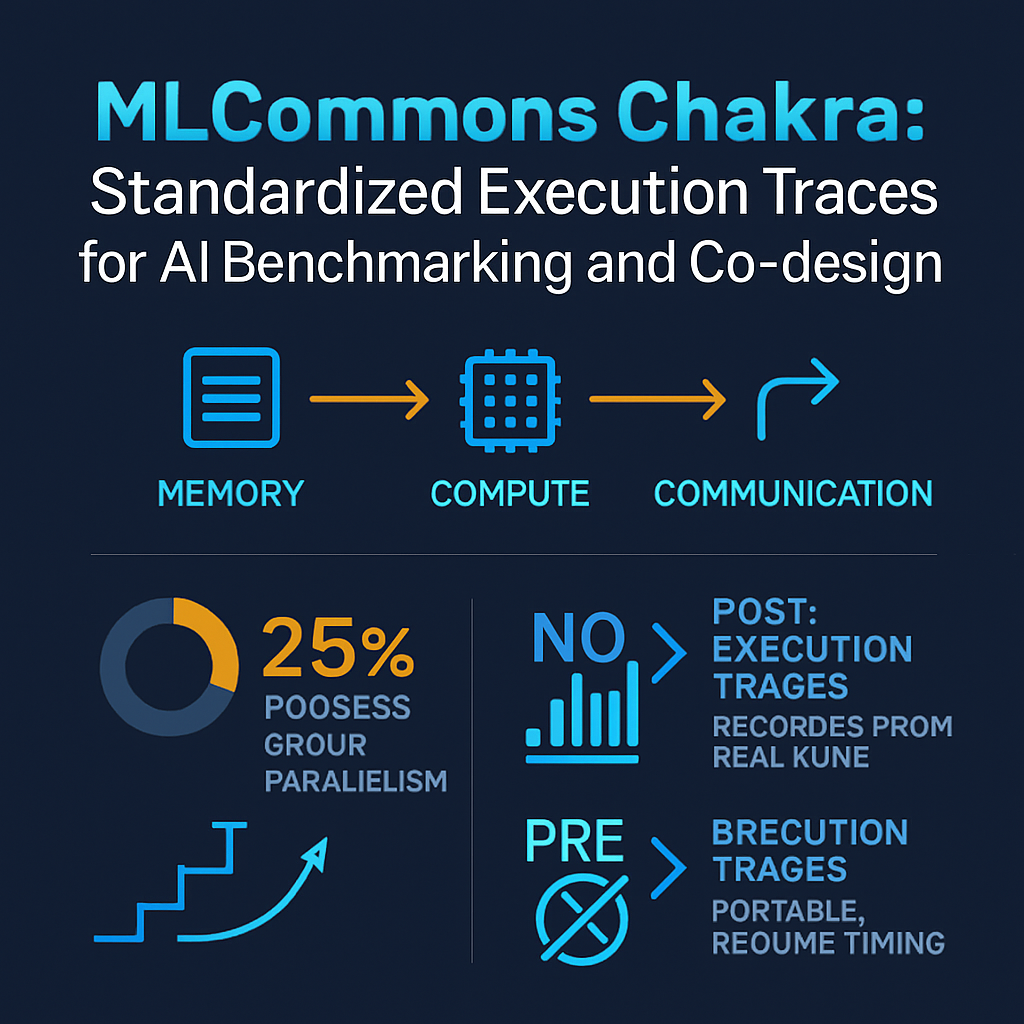
MLCommons Chakra: Standardized Execution Traces for AI Benchmarking and Co-design
Oct 13, 2026
This episode examines Chakra, an MLCommons effort to define one open, graph-based execution-trace format. The format is meant to carry a distributed AI workload from production observation through benchmark replay to hardware simulation, without exposing a proprietary model. It explains how a trace is a per-device directed acyclic graph of compute, memory, and communication nodes linked by control, data, and synchronization dependencies. Process groups encode tensor, pipeline, data, and expert parallelism, and the traces carry no weights or data. The discussion separates post-execution traces, which are recorded from real runs and carry that machine's timings, from pre-execution traces, which are portable but need timing from elsewhere. It also covers how PyTorch's execution graph observer and Kineto profiler are merged to capture traces, and how replay, simulation (ASTRA-sim), and emulation consume them. The hosts treat the ecosystem story as strong but press on whether the evidence supports the paper's boldest claims, which makes this useful for anyone interested in benchmarking and co-designing AI infrastructure.
Interactive Visualization: MLCommons Chakra: Standardized Execution Traces for AI Benchmarking and Co-design
Sources:
1. MLCommons Chakra: Advancing Performance Benchmarking and Co-design using Standardized Execution Traces — Srinivas Sridharan, Theodor-Adrian Badea, Andy Balogh, Bradford M. Beckmann, Brian Coutinho, Louis Feng, Sheng Fu, Sanshan Gao, Mehryar Garakani, Taekyung Heo, David Kanter, Josh Ladd, Ziwei Li, Winston Liu, Changhai Man, Dan Mihailescu, Spandan More, Joongun Park, Ashwin Ramachandran, Vinay Ramakrishnaiah, Saeed Rashidi, Vijay Janapa Reddi, Puneet Sharma, Phio Tian, William Won, Hanjiang Wu, Huan Xu, Jinsun Yoo, Tushar Krishna, 2026
http://arxiv.org/abs/2605.11333
2. ASTRA-sim: Enabling SW/HW Co-Design Exploration for Distributed DL Training Platforms — Saeed Rashidi, Srinivas Sridharan, Sudarshan Srinivasan, Tushar Krishna, 2020
https://scholar.google.com/scholar?q=ASTRA-sim%3A+Enabling+SW%2FHW+Co-Design+Exploration+for+Distributed+DL+Training+Platforms
3. ASTRA-sim2.0: Modeling Hierarchical Networks and Disaggregated Systems for Large-model Training at Scale — William Won, Taekyung Heo, Saeed Rashidi, Srinivas Sridharan, Sudarshan Srinivasan, Tushar Krishna, 2023
https://scholar.google.com/scholar?q=ASTRA-sim2.0%3A+Modeling+Hierarchical+Networks+and+Disaggregated+Systems+for+Large-model+Training+at+Scale
4. Chakra: Advancing Performance Benchmarking and Co-design using Standardized Execution Traces — Srinivas Sridharan, Taekyung Heo, Louis Feng, Zhaodong Wang, Melanie Bhatt, Wei Wen, Tushar Krishna, and collaborators, 2023
https://scholar.google.com/scholar?q=Chakra%3A+Advancing+Performance+Benchmarking+and+Co-design+using+Standardized+Execution+Traces
5. PyTorch Profiler / Kineto and the PyTorch Execution Trace Observer (project documentation) — Meta PyTorch team, 2021-2023
https://scholar.google.com/scholar?q=PyTorch+Profiler+%2F+Kineto+and+the+PyTorch+Execution+Trace+Observer+%28project+documentation%29
6. MLPerf Training Benchmark — Peter Mattson, Christine Cheng, Gregory Diamos, Cody Coleman, Paulius Micikevicius, David Patterson, and many co-authors, 2020
https://scholar.google.com/scholar?q=MLPerf+Training+Benchmark
7. MLPerf Inference Benchmark — Vijay Janapa Reddi, Christine Cheng, David Kanter, Peter Mattson, and many co-authors, 2020
https://scholar.google.com/scholar?q=MLPerf+Inference+Benchmark
8. MLPerf Power: Benchmarking the Energy Efficiency of Machine Learning Systems from Microwatts to Megawatts for Sustainable AI — Arya Tschand, Arun Tejusve Raghunath Rajan, Sachin Idgunji, Anirban Ghosh, Jeremy Holleman, Csaba Kiraly, Pawan Ambalkar, Ritika Borkar, Ramesh Chukka, Trevor Cockrell, Oliver Curtis, Grigori Fursin, Miro Hodak, Hiwot Kassa, Anton Lokhmotov, Dejan Miskovic, Yuechao Pan, Manu Prasad Manmathan, Liz Raymond, Tom St. John, Arjun Suresh, Rowan Taubitz, Sean Zhan, Scott Wasson, David Kanter, Vijay Janapa Reddi, 2024
https://scholar.google.com/scholar?q=MLPerf+Power%3A+Benchmarking+the+Energy+Efficiency+of+Machine+Learning+Systems+from+Microwatts+to+Megawatts+for+Sustainable+AI
9. SPEC CPU benchmark suite documentation and rationale (Standard Performance Evaluation Corporation) — SPEC, with historical analysis by John L. Henning and others, 1989-2017
https://scholar.google.com/scholar?q=SPEC+CPU+benchmark+suite+documentation+and+rationale+%28Standard+Performance+Evaluation+Corporation%29
10. In-Datacenter Performance Analysis of a Tensor Processing Unit — Norman P. Jouppi, Cliff Young, Nishant Patil, David Patterson, and many co-authors, 2017
https://scholar.google.com/scholar?q=In-Datacenter+Performance+Analysis+of+a+Tensor+Processing+Unit
11. A Domain-Specific Architecture for Deep Neural Networks / A New Golden Age for Computer Architecture — John L. Hennessy and David A. Patterson, 2019
https://scholar.google.com/scholar?q=A+Domain-Specific+Architecture+for+Deep+Neural+Networks+%2F+A+New+Golden+Age+for+Computer+Architecture
12. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
13. Software-Hardware Co-design for Fast and Scalable Training of Deep Learning Recommendation Models — Dheevatsa Mudigere, Yuchen Hao, Jianyu Huang, and many co-authors at Meta, 2022
https://scholar.google.com/scholar?q=Software-Hardware+Co-design+for+Fast+and+Scalable+Training+of+Deep+Learning+Recommendation+Models
14. Mystique: Enabling Accurate and Scalable Generation of Production AI Benchmarks — Mengyuan (Mingyu) Liang, Wenyin Fu, Louis Feng, Zhongyi Lin, Pavani Panakanti, Shengbao Zheng, Srinivas Sridharan, Christina Delimitrou, 2023
https://scholar.google.com/scholar?q=Mystique%3A+Enabling+Accurate+and+Scalable+Generation+of+Production+AI+Benchmarks
15. Scaling Deep Learning Training with MPI/Collective Communication: NCCL and related collective library documentation (NVIDIA NCCL, AMD RCCL) — NVIDIA and AMD library teams, 2016-2025
https://scholar.google.com/scholar?q=Scaling+Deep+Learning+Training+with+MPI%2FCollective+Communication%3A+NCCL+and+related+collective+library+documentation+%28NVIDIA+NCCL%2C+AMD+RCCL%29
16. Characterizing and Understanding Distributed Training Workloads / Analysis of Large-Scale Multi-Tenant GPU Clusters for DNN Training Workloads — Myeongjae Jeon, Shivaram Venkataraman, Amar Phanishayee, Junjie Qian, Wencong Xiao, Fan Yang, 2019
https://scholar.google.com/scholar?q=Characterizing+and+Understanding+Distributed+Training+Workloads+%2F+Analysis+of+Large-Scale+Multi-Tenant+GPU+Clusters+for+DNN+Training+Workloads
17. MLaaS in the Wild: Workload Analysis and Scheduling in Large-Scale Heterogeneous GPU Clusters — Qizhen Weng, Wencong Xiao, Yinghao Yu, Wei Wang, Cheng Wang, Jian He, Yong Li, Liping Zhang, Wei Lin, Yu Ding, 2022
https://scholar.google.com/scholar?q=MLaaS+in+the+Wild%3A+Workload+Analysis+and+Scheduling+in+Large-Scale+Heterogeneous+GPU+Clusters
18. Lumos: Efficient Performance Modeling and Estimation for Large-scale LLM Training — Liang et al., 2025
https://scholar.google.com/scholar?q=Lumos%3A+Efficient+Performance+Modeling+and+Estimation+for+Large-scale+LLM+Training
19. Holistic Trace Analysis (HTA) — Meta / FacebookResearch, 2023
https://scholar.google.com/scholar?q=Holistic+Trace+Analysis+%28HTA%29
20. SimAI: Unifying Architecture Design and Performance Tuning for Large-Scale LLM Training with Scalability and Precision — Wang et al. (Alibaba), 2025
https://scholar.google.com/scholar?q=SimAI%3A+Unifying+Architecture+Design+and+Performance+Tuning+for+Large-Scale+LLM+Training+with+Scalability+and+Precision
21. Echo / Proteus / vTrain / Calculon style performance models (vTrain: A Simulation Framework for Evaluating Cost-effective and Compute-optimal LLM Training) — Bang et al., 2024
https://scholar.google.com/scholar?q=Echo+%2F+Proteus+%2F+vTrain+%2F+Calculon+style+performance+models+%28vTrain%3A+A+Simulation+Framework+for+Evaluating+Cost-effective+and+Compute-optimal+LLM+Training%29
22. Unity: Accelerating DNN Training Through Joint Optimization of Algebraic Transformations and Parallelization — Unger et al., 2022
https://scholar.google.com/scholar?q=Unity%3A+Accelerating+DNN+Training+Through+Joint+Optimization+of+Algebraic+Transformations+and+Parallelization
23. GOAL: A Generalized Goal-oriented Application Language for Network/HPC Trace Simulation (LogGOPSim lineage) — Hoefler et al. / Shen et al., 2010 / 2025
https://scholar.google.com/scholar?q=GOAL%3A+A+Generalized+Goal-oriented+Application+Language+for+Network%2FHPC+Trace+Simulation+%28LogGOPSim+lineage%29
24. Llumnix / Splitwise / DistServe / Mooncake — Patel et al.; Zhong et al.; Qin et al., 2024
https://scholar.google.com/scholar?q=Llumnix+%2F+Splitwise+%2F+DistServe+%2F+Mooncake
25. Characterization of Large Language Model Development in the Datacenter (Acme) — Hu et al., 2024
https://scholar.google.com/scholar?q=Characterization+of+Large+Language+Model+Development+in+the+Datacenter+%28Acme%29
26. MegaScale: Scaling Large Language Model Training to More Than 10,000 GPUs — Jiang et al. (ByteDance), 2024
https://scholar.google.com/scholar?q=MegaScale%3A+Scaling+Large+Language+Model+Training+to+More+Than+10%2C000+GPUs
27. STAGE: Symbolic Tensor Graph Engine for LLM Workload Synthesis — Man et al., 2026
https://scholar.google.com/scholar?q=STAGE%3A+Symbolic+Tensor+Graph+Engine+for+LLM+Workload+Synthesis
28. MLPerf Training / Inference benchmark papers — Mattson et al.; Reddi et al., 2020
https://scholar.google.com/scholar?q=MLPerf+Training+%2F+Inference+benchmark+papers
Interactive Visualization: MLCommons Chakra: Standardized Execution Traces for AI Benchmarking and Co-design