MiniCPM: Small Language Models and Scalable Training Strategies
Nov 14, 2026
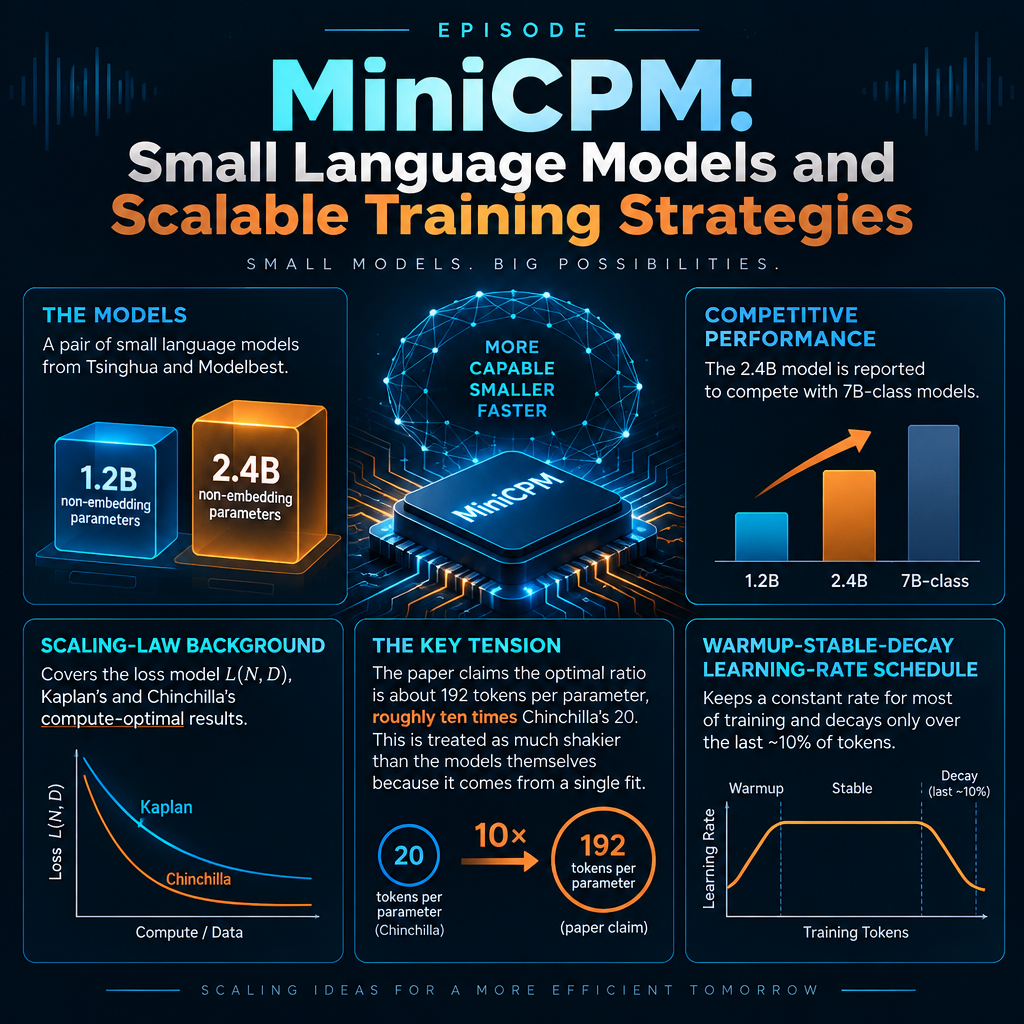
This episode examines MiniCPM, a pair of small language models (1.2B and 2.4B non-embedding parameters) from Tsinghua and Modelbest. The 2.4B model is reported to compete with 7B-class models. It starts with scaling-law background: the loss model L(N, D), Kaplan's and Chinchilla's compute-optimal results, and why over-training a small model can lower inference cost. The central tension is the paper's claim that the optimal ratio is about 192 tokens per parameter, roughly ten times Chinchilla's 20, which the discussion treats as much shakier than the models themselves because it comes from a single fit. The conversation then covers the Warmup-Stable-Decay learning-rate schedule, which keeps a constant rate for most of training and decays only over the last ~10% of tokens. Unlike cosine decay, this lets any stable checkpoint branch into a finished model or resume for continual pre-training. It also covers "model wind tunnel" experiments on tiny models and the muP parameterization that lets hyperparameters tuned at small width transfer to larger models.
Interactive Visualization: MiniCPM: Small Language Models and Scalable Training Strategies
Sources:
1. MiniCPM: Unveiling the Potential of Small Language Models with Scalable Training Strategies — Shengding Hu, Yuge Tu, Xu Han, Chaoqun He, Ganqu Cui, Xiang Long, Zhi Zheng, Yewei Fang, Yuxiang Huang, Weilin Zhao, Xinrong Zhang, Zheng Leng Thai, Kaihuo Zhang, Chongyi Wang, Yuan Yao, Chenyang Zhao, Jie Zhou, Jie Cai, Zhongwu Zhai, Ning Ding, Chao Jia, Guoyang Zeng, Dahai Li, Zhiyuan Liu, Maosong Sun, 2024
http://arxiv.org/abs/2404.06395
2. Textbooks Are All You Need (Phi-1) — Suriya Gunasekar, Yi Zhang, Jyoti Aneja, Sébastien Bubeck, Yuanzhi Li, et al. (Microsoft Research), 2023
https://scholar.google.com/scholar?q=Textbooks+Are+All+You+Need+%28Phi-1%29
3. TinyLlama: An Open-Source Small Language Model — Peiyuan Zhang, Guangtao Zeng, Tianduo Wang, Wei Lu, 2024
https://scholar.google.com/scholar?q=TinyLlama%3A+An+Open-Source+Small+Language+Model
4. MobileLLM: Optimizing Sub-billion Parameter Language Models for On-Device Use Cases — Zechun Liu, Changsheng Zhao, Forrest Iandola, et al. (Meta), 2024
https://scholar.google.com/scholar?q=MobileLLM%3A+Optimizing+Sub-billion+Parameter+Language+Models+for+On-Device+Use+Cases
5. Small Language Models: Survey, Measurements, and Insights — Zhenyan Lu, Xiang Li, Dongqi Cai, Rongjie Yi, Fangming Liu, et al., 2024
https://scholar.google.com/scholar?q=Small+Language+Models%3A+Survey%2C+Measurements%2C+and+Insights
6. Understanding Warmup-Stable-Decay Learning Rates: A River Valley Loss Landscape Perspective — Kaiyue Wen, Zhiyuan Li, Jason Wang, David Hall, Percy Liang, Tengyu Ma, 2024
https://scholar.google.com/scholar?q=Understanding+Warmup-Stable-Decay+Learning+Rates%3A+A+River+Valley+Loss+Landscape+Perspective
7. Scaling Laws and Compute-Optimal Training Beyond Fixed Training Durations — Alexander Hägele, Elie Bakouch, Atli Kosson, Loubna Ben Allal, Leandro von Werra, Martin Jaggi, 2024
https://scholar.google.com/scholar?q=Scaling+Laws+and+Compute-Optimal+Training+Beyond+Fixed+Training+Durations
8. The Road Less Scheduled — Aaron Defazio, Xingyu Yang, Harsh Mehta, Konstantin Mishchenko, Ahmed Khaled, Ashok Cutkosky, 2024
https://scholar.google.com/scholar?q=The+Road+Less+Scheduled
9. Scaling Vision Transformers — Xiaohua Zhai, Alexander Kolesnikov, Neil Houlsby, Lucas Beyer, 2022
https://scholar.google.com/scholar?q=Scaling+Vision+Transformers
10. Tensor Programs V: Tuning Large Neural Networks via Zero-Shot Hyperparameter Transfer — Greg Yang, Edward J. Hu, Igor Babuschkin, Szymon Sidor, Xiaodong Liu, David Farhi, Nick Ryder, Jakub Pachocki, Weizhu Chen, Jianfeng Gao, 2022
https://scholar.google.com/scholar?q=Tensor+Programs+V%3A+Tuning+Large+Neural+Networks+via+Zero-Shot+Hyperparameter+Transfer
11. Tensor Programs VI: Feature Learning in Infinite-Depth Neural Networks — Greg Yang, Dingli Yu, Chen Zhu, Soufiane Hayou, 2023
https://scholar.google.com/scholar?q=Tensor+Programs+VI%3A+Feature+Learning+in+Infinite-Depth+Neural+Networks
12. Cerebras-GPT: Open Compute-Optimal Language Models Trained on the Cerebras Wafer-Scale Cluster — Nolan Dey, Gurpreet Gosal, Zhiming Chen, Hemant Khachane, William Marshall, Ribhu Pathria, Marvin Tom, Joel Hestness, 2023
https://scholar.google.com/scholar?q=Cerebras-GPT%3A+Open+Compute-Optimal+Language+Models+Trained+on+the+Cerebras+Wafer-Scale+Cluster
13. Scaling Exponents Across Parameterizations and Optimizers — Katie Everett, Lechao Xiao, Mitchell Wortsman, Alexander A. Alemi, Roman Novak, Peter J. Liu, Izzeddin Gur, Jascha Sohl-Dickstein, Leslie Pack Kaelbling, Jaehoon Lee, Jeffrey Pennington, 2024
https://scholar.google.com/scholar?q=Scaling+Exponents+Across+Parameterizations+and+Optimizers
14. Training Compute-Optimal Large Language Models (Chinchilla) — Jordan Hoffmann et al., 2022
https://scholar.google.com/scholar?q=Training+Compute-Optimal+Large+Language+Models+%28Chinchilla%29
15. Chinchilla Scaling: A Replication Attempt — Tamay Besiroglu, Ege Erdil, Matthew Barnett, Josh You, 2024
https://scholar.google.com/scholar?q=Chinchilla+Scaling%3A+A+Replication+Attempt
16. Beyond Chinchilla-Optimal: Accounting for Inference in Language Model Scaling Laws — Nikhil Sardana, Jonathan Frankle, 2023
https://scholar.google.com/scholar?q=Beyond+Chinchilla-Optimal%3A+Accounting+for+Inference+in+Language+Model+Scaling+Laws
17. Small-scale proxies for large-scale Transformer training instabilities — Mitchell Wortsman et al., 2023
https://scholar.google.com/scholar?q=Small-scale+proxies+for+large-scale+Transformer+training+instabilities
18. Scaling Laws for Neural Language Models — Jared Kaplan et al., 2020
https://scholar.google.com/scholar?q=Scaling+Laws+for+Neural+Language+Models
19. An Empirical Model of Large-Batch Training — Sam McCandlish et al., 2018
https://scholar.google.com/scholar?q=An+Empirical+Model+of+Large-Batch+Training
20. The Road Less Scheduled (Schedule-Free Optimization) — Aaron Defazio et al., 2024
https://scholar.google.com/scholar?q=The+Road+Less+Scheduled+%28Schedule-Free+Optimization%29
21. DeepSeek LLM: Scaling Open-Source Language Models with Longtermism — DeepSeek-AI (Bi et al.), 2024
https://scholar.google.com/scholar?q=DeepSeek+LLM%3A+Scaling+Open-Source+Language+Models+with+Longtermism
22. Textbooks Are All You Need (Phi-1) and Phi-2 reports — Suriya Gunasekar et al.; Javaheripi & Bubeck, 2023
https://scholar.google.com/scholar?q=Textbooks+Are+All+You+Need+%28Phi-1%29+and+Phi-2+reports
Interactive Visualization: MiniCPM: Small Language Models and Scalable Training Strategies
1. MiniCPM: Unveiling the Potential of Small Language Models with Scalable Training Strategies — Shengding Hu, Yuge Tu, Xu Han, Chaoqun He, Ganqu Cui, Xiang Long, Zhi Zheng, Yewei Fang, Yuxiang Huang, Weilin Zhao, Xinrong Zhang, Zheng Leng Thai, Kaihuo Zhang, Chongyi Wang, Yuan Yao, Chenyang Zhao, Jie Zhou, Jie Cai, Zhongwu Zhai, Ning Ding, Chao Jia, Guoyang Zeng, Dahai Li, Zhiyuan Liu, Maosong Sun, 2024
http://arxiv.org/abs/2404.06395
2. Textbooks Are All You Need (Phi-1) — Suriya Gunasekar, Yi Zhang, Jyoti Aneja, Sébastien Bubeck, Yuanzhi Li, et al. (Microsoft Research), 2023
https://scholar.google.com/scholar?q=Textbooks+Are+All+You+Need+%28Phi-1%29
3. TinyLlama: An Open-Source Small Language Model — Peiyuan Zhang, Guangtao Zeng, Tianduo Wang, Wei Lu, 2024
https://scholar.google.com/scholar?q=TinyLlama%3A+An+Open-Source+Small+Language+Model
4. MobileLLM: Optimizing Sub-billion Parameter Language Models for On-Device Use Cases — Zechun Liu, Changsheng Zhao, Forrest Iandola, et al. (Meta), 2024
https://scholar.google.com/scholar?q=MobileLLM%3A+Optimizing+Sub-billion+Parameter+Language+Models+for+On-Device+Use+Cases
5. Small Language Models: Survey, Measurements, and Insights — Zhenyan Lu, Xiang Li, Dongqi Cai, Rongjie Yi, Fangming Liu, et al., 2024
https://scholar.google.com/scholar?q=Small+Language+Models%3A+Survey%2C+Measurements%2C+and+Insights
6. Understanding Warmup-Stable-Decay Learning Rates: A River Valley Loss Landscape Perspective — Kaiyue Wen, Zhiyuan Li, Jason Wang, David Hall, Percy Liang, Tengyu Ma, 2024
https://scholar.google.com/scholar?q=Understanding+Warmup-Stable-Decay+Learning+Rates%3A+A+River+Valley+Loss+Landscape+Perspective
7. Scaling Laws and Compute-Optimal Training Beyond Fixed Training Durations — Alexander Hägele, Elie Bakouch, Atli Kosson, Loubna Ben Allal, Leandro von Werra, Martin Jaggi, 2024
https://scholar.google.com/scholar?q=Scaling+Laws+and+Compute-Optimal+Training+Beyond+Fixed+Training+Durations
8. The Road Less Scheduled — Aaron Defazio, Xingyu Yang, Harsh Mehta, Konstantin Mishchenko, Ahmed Khaled, Ashok Cutkosky, 2024
https://scholar.google.com/scholar?q=The+Road+Less+Scheduled
9. Scaling Vision Transformers — Xiaohua Zhai, Alexander Kolesnikov, Neil Houlsby, Lucas Beyer, 2022
https://scholar.google.com/scholar?q=Scaling+Vision+Transformers
10. Tensor Programs V: Tuning Large Neural Networks via Zero-Shot Hyperparameter Transfer — Greg Yang, Edward J. Hu, Igor Babuschkin, Szymon Sidor, Xiaodong Liu, David Farhi, Nick Ryder, Jakub Pachocki, Weizhu Chen, Jianfeng Gao, 2022
https://scholar.google.com/scholar?q=Tensor+Programs+V%3A+Tuning+Large+Neural+Networks+via+Zero-Shot+Hyperparameter+Transfer
11. Tensor Programs VI: Feature Learning in Infinite-Depth Neural Networks — Greg Yang, Dingli Yu, Chen Zhu, Soufiane Hayou, 2023
https://scholar.google.com/scholar?q=Tensor+Programs+VI%3A+Feature+Learning+in+Infinite-Depth+Neural+Networks
12. Cerebras-GPT: Open Compute-Optimal Language Models Trained on the Cerebras Wafer-Scale Cluster — Nolan Dey, Gurpreet Gosal, Zhiming Chen, Hemant Khachane, William Marshall, Ribhu Pathria, Marvin Tom, Joel Hestness, 2023
https://scholar.google.com/scholar?q=Cerebras-GPT%3A+Open+Compute-Optimal+Language+Models+Trained+on+the+Cerebras+Wafer-Scale+Cluster
13. Scaling Exponents Across Parameterizations and Optimizers — Katie Everett, Lechao Xiao, Mitchell Wortsman, Alexander A. Alemi, Roman Novak, Peter J. Liu, Izzeddin Gur, Jascha Sohl-Dickstein, Leslie Pack Kaelbling, Jaehoon Lee, Jeffrey Pennington, 2024
https://scholar.google.com/scholar?q=Scaling+Exponents+Across+Parameterizations+and+Optimizers
14. Training Compute-Optimal Large Language Models (Chinchilla) — Jordan Hoffmann et al., 2022
https://scholar.google.com/scholar?q=Training+Compute-Optimal+Large+Language+Models+%28Chinchilla%29
15. Chinchilla Scaling: A Replication Attempt — Tamay Besiroglu, Ege Erdil, Matthew Barnett, Josh You, 2024
https://scholar.google.com/scholar?q=Chinchilla+Scaling%3A+A+Replication+Attempt
16. Beyond Chinchilla-Optimal: Accounting for Inference in Language Model Scaling Laws — Nikhil Sardana, Jonathan Frankle, 2023
https://scholar.google.com/scholar?q=Beyond+Chinchilla-Optimal%3A+Accounting+for+Inference+in+Language+Model+Scaling+Laws
17. Small-scale proxies for large-scale Transformer training instabilities — Mitchell Wortsman et al., 2023
https://scholar.google.com/scholar?q=Small-scale+proxies+for+large-scale+Transformer+training+instabilities
18. Scaling Laws for Neural Language Models — Jared Kaplan et al., 2020
https://scholar.google.com/scholar?q=Scaling+Laws+for+Neural+Language+Models
19. An Empirical Model of Large-Batch Training — Sam McCandlish et al., 2018
https://scholar.google.com/scholar?q=An+Empirical+Model+of+Large-Batch+Training
20. The Road Less Scheduled (Schedule-Free Optimization) — Aaron Defazio et al., 2024
https://scholar.google.com/scholar?q=The+Road+Less+Scheduled+%28Schedule-Free+Optimization%29
21. DeepSeek LLM: Scaling Open-Source Language Models with Longtermism — DeepSeek-AI (Bi et al.), 2024
https://scholar.google.com/scholar?q=DeepSeek+LLM%3A+Scaling+Open-Source+Language+Models+with+Longtermism
22. Textbooks Are All You Need (Phi-1) and Phi-2 reports — Suriya Gunasekar et al.; Javaheripi & Bubeck, 2023
https://scholar.google.com/scholar?q=Textbooks+Are+All+You+Need+%28Phi-1%29+and+Phi-2+reports
Interactive Visualization: MiniCPM: Small Language Models and Scalable Training Strategies