mHC: Manifold-Constrained Hyper-Connections Stabilize Wider Residual Streams
Sep 29, 2026
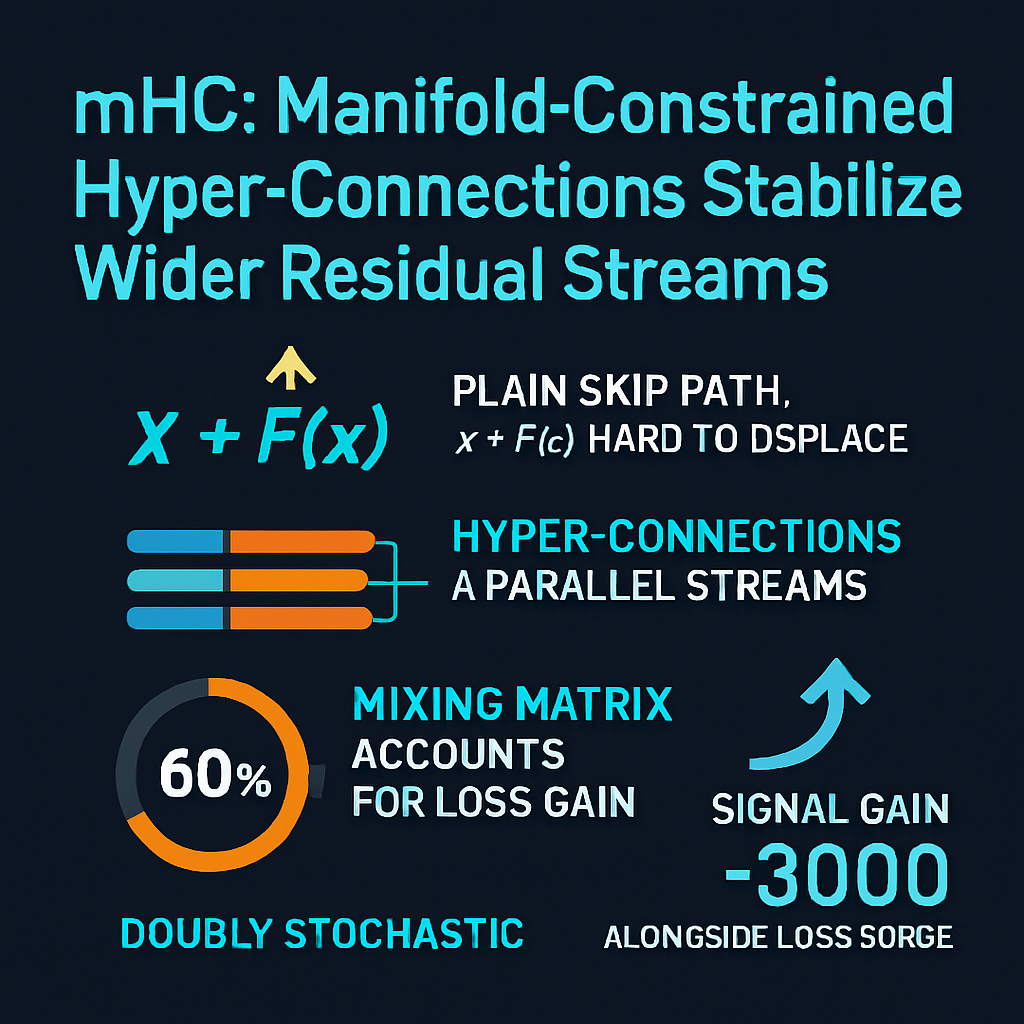
This episode examines DeepSeek-AI's mHC: Manifold-Constrained Hyper-Connections, which tries to improve the transformer's residual connection, a piece of the architecture that has barely changed in a decade. It first explains why the plain skip path x + F(x) has been so hard to displace. It then covers ByteDance's Hyper-Connections, which widen the residual stream into four parallel streams with learnable read, write and mixing maps. The mixing matrix alone accounts for most of the reported loss gain. The discussion turns to the failure mode: the product of unconstrained mixing matrices across layers lets signal gain climb to roughly 3000 in a 27B model, alongside a loss surge and a memory-bandwidth bill. The fix constrains the mixing matrix to be doubly stochastic using the 1967 Sinkhorn-Knopp algorithm, which keeps the composite mapping bounded. The hosts also weigh whether a doubly stochastic matrix, which is not identity, can preserve the gradient-flow argument for identity skip paths. They cover the added kernel and pipeline engineering, which reportedly costs about 6.7% extra training time.
Interactive Visualization: mHC: Manifold-Constrained Hyper-Connections Stabilize Wider Residual Streams
Sources:
1. mHC: Manifold-Constrained Hyper-Connections — Zhenda Xie, Yixuan Wei, Huanqi Cao, Chenggang Zhao, Chengqi Deng, Jiashi Li, Damai Dai, Huazuo Gao, Jiang Chang, Kuai Yu, Liang Zhao, Shangyan Zhou, Zhean Xu, Zhengyan Zhang, Wangding Zeng, Shengding Hu, Yuqing Wang, Jingyang Yuan, Lean Wang, Wenfeng Liang, 2025
http://arxiv.org/abs/2512.24880
2. Hyper-Connections — Defa Zhu, Hongzhi Huang, Zihao Huang, Yutao Zeng, Yunyao Mao, Banggu Wu, Qiyang Min, Xun Zhou, 2024
https://scholar.google.com/scholar?q=Hyper-Connections
3. Identity Mappings in Deep Residual Networks — Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun, 2016
https://scholar.google.com/scholar?q=Identity+Mappings+in+Deep+Residual+Networks
4. Concerning nonnegative matrices and doubly stochastic matrices — Richard Sinkhorn, Paul Knopp, 1967
https://scholar.google.com/scholar?q=Concerning+nonnegative+matrices+and+doubly+stochastic+matrices
5. Sinkformers: Transformers with Doubly Stochastic Attention — Michael E. Sander, Pierre Ablin, Mathieu Blondel, Gabriel Peyré, 2022
https://scholar.google.com/scholar?q=Sinkformers%3A+Transformers+with+Doubly+Stochastic+Attention
6. Attention is Not All You Need: Pure Attention Loses Rank Doubly Exponentially with Depth — Yihe Dong, Jean-Baptiste Cordonnier, Andreas Loukas, 2021
https://scholar.google.com/scholar?q=Attention+is+Not+All+You+Need%3A+Pure+Attention+Loses+Rank+Doubly+Exponentially+with+Depth
7. Deeper Insights into Graph Convolutional Networks for Semi-Supervised Learning / Graph Neural Networks Exponentially Lose Expressive Power for Node Classification — Qimai Li, Zhichao Han, Xiao-Ming Wu; Kenta Oono, Taiji Suzuki, 2018 / 2020
https://scholar.google.com/scholar?q=Deeper+Insights+into+Graph+Convolutional+Networks+for+Semi-Supervised+Learning+%2F+Graph+Neural+Networks+Exponentially+Lose+Expressive+Power+for+Node+Classification
8. DenseFormer: Enhancing Information Flow in Transformers via Depth Weighted Averaging — Matteo Pagliardini, Amirkeivan Mohtashami, François Fleuret, Martin Jaggi, 2024
https://scholar.google.com/scholar?q=DenseFormer%3A+Enhancing+Information+Flow+in+Transformers+via+Depth+Weighted+Averaging
9. MUDDFormer: Breaking Residual Bottlenecks in Transformers via Multiway Dynamic Dense Connections — Da Xiao, Qingye Meng, Shengping Li, Xingyuan Yuan, 2025
https://scholar.google.com/scholar?q=MUDDFormer%3A+Breaking+Residual+Bottlenecks+in+Transformers+via+Multiway+Dynamic+Dense+Connections
10. Residual Matrix Transformers: Scaling the Size of the Residual Stream — Brian Mak, Jeffrey Flanigan, 2025
https://scholar.google.com/scholar?q=Residual+Matrix+Transformers%3A+Scaling+the+Size+of+the+Residual+Stream
11. DeepNet: Scaling Transformers to 1,000 Layers — Hongyu Wang, Shuming Ma, Li Dong, et al., 2022
https://scholar.google.com/scholar?q=DeepNet%3A+Scaling+Transformers+to+1%2C000+Layers
12. ReZero is All You Need: Fast Convergence at Large Depth — Thomas Bachlechner, Bodhisattwa Prasad Majumder, Huanru Henry Mao, Garrison W. Cottrell, Julian McAuley, 2020
https://scholar.google.com/scholar?q=ReZero+is+All+You+Need%3A+Fast+Convergence+at+Large+Depth
13. The Curse of Depth in Large Language Models — Wenfang Sun et al., 2025
https://scholar.google.com/scholar?q=The+Curse+of+Depth+in+Large+Language+Models
14. Value Residual Learning — Zhanchao Zhou et al., 2024
https://scholar.google.com/scholar?q=Value+Residual+Learning
15. Resurrecting the Sigmoid in Deep Learning through Dynamical Isometry / Deep Information Propagation — Jeffrey Pennington, Samuel Schoenholz, Surya Ganguli; Samuel Schoenholz et al., 2017
https://scholar.google.com/scholar?q=Resurrecting+the+Sigmoid+in+Deep+Learning+through+Dynamical+Isometry+%2F+Deep+Information+Propagation
16. DeepSeek-V3 Technical Report — DeepSeek-AI, 2024
https://scholar.google.com/scholar?q=DeepSeek-V3+Technical+Report
Interactive Visualization: mHC: Manifold-Constrained Hyper-Connections Stabilize Wider Residual Streams