MegaTrain: Training 120B-Parameter Models on a Single GPU
Sep 5, 2026
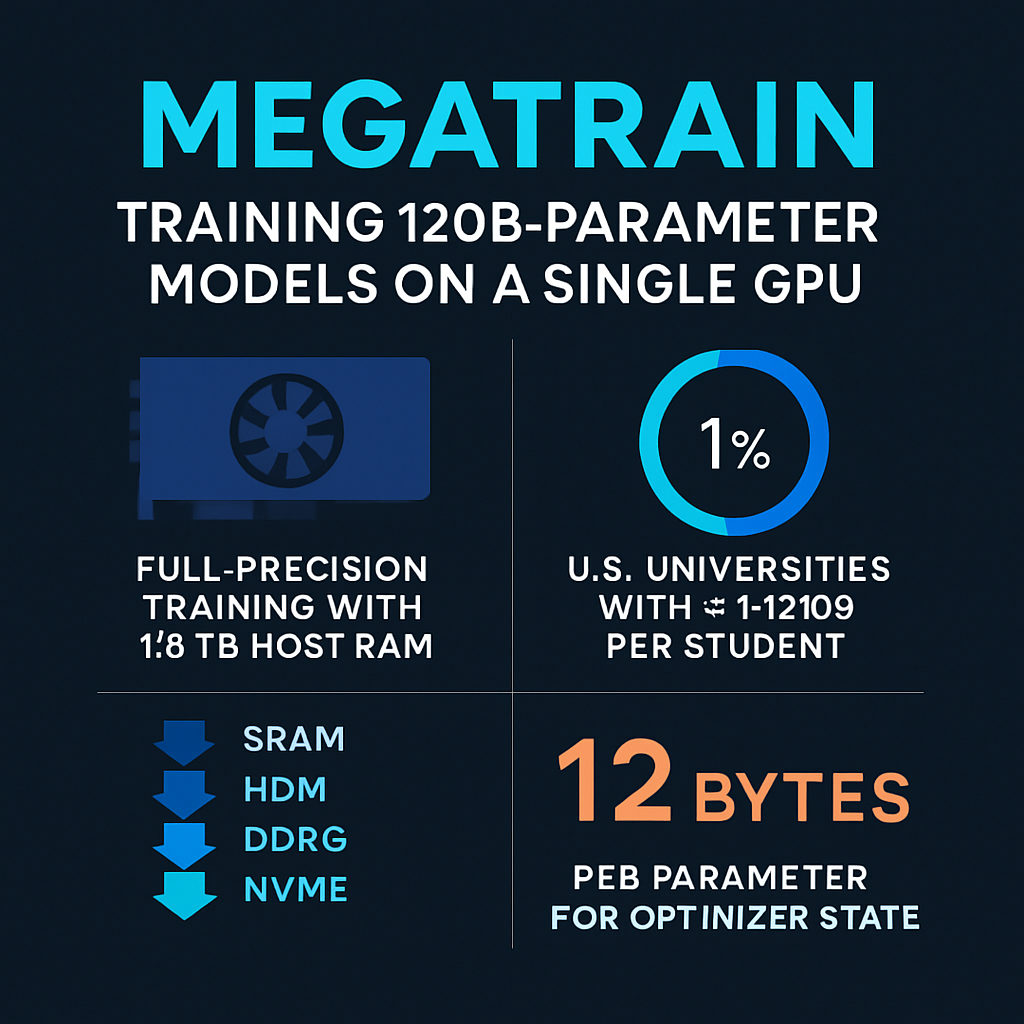
This episode examines MegaTrain, a method for full-precision training of 100-billion-parameter-plus language models on a single H200 GPU paired with 1.5 terabytes of host RAM, from a Notre Dame and Lehigh University team. The discussion centers on why memory, not compute, is the real bottleneck for most researchers, citing a survey showing only two of 167 surveyed U.S. universities average more than one H100 per student, while post-training work like instruction tuning and alignment increasingly demands full parameter and optimizer states without full pretraining-scale hardware. The hosts walk through the GPU memory hierarchy — from on-chip SRAM through HBM, host DDR5, and NVMe — and the 12-bytes-per-parameter cost of Adam optimizer state that makes a 70B model require 840 gigabytes of persistent storage. They contrast MegaTrain's approach with prior offloading systems like ZeRO-Offload and ZeRO-Infinity, highlighting the key architectural inversion: host memory becomes the authoritative store for all parameters and optimizer state, while GPU HBM is reduced to a transient scratchpad streaming one layer at a time across PCIe. Listeners interested in democratizing large-model training on constrained hardware will find the systems-level tradeoffs and pointed debate over whether this is genuinely novel or a repackaging of known offloading techniques particularly engaging.
Interactive Visualization: MegaTrain: Training 120B-Parameter Models on a Single GPU
Sources:
1. MegaTrain: Full Precision Training of 100B+ Parameter Large Language Models on a Single GPU — Zhengqing Yuan, Hanchi Sun, Lichao Sun, Yanfang Ye, 2026
http://arxiv.org/abs/2604.05091
2. vDNN: Virtualized Deep Neural Networks for Scalable, Memory-Efficient Neural Network Design — Minsoo Rhu, Natalia Gimelshein, Jason Clemons, Arslan Zulfiqar, Stephen W. Keckler, 2016
https://scholar.google.com/scholar?q=vDNN%3A+Virtualized+Deep+Neural+Networks+for+Scalable%2C+Memory-Efficient+Neural+Network+Design
3. ZeRO-Offload: Democratizing Billion-Scale Model Training — Jie Ren, Samyam Rajbhandari, Reza Yazdani Aminabadi, Olatunji Ruwase, Shuangyan Yang, Minjia Zhang, Dong Li, Yuxiong He, 2021
https://scholar.google.com/scholar?q=ZeRO-Offload%3A+Democratizing+Billion-Scale+Model+Training
4. ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning — Samyam Rajbhandari, Olatunji Ruwase, Jeff Rasley, Shaden Smith, Yuxiong He, 2021
https://scholar.google.com/scholar?q=ZeRO-Infinity%3A+Breaking+the+GPU+Memory+Wall+for+Extreme+Scale+Deep+Learning
5. JAX: composable transformations of Python+NumPy programs — James Bradbury, Roy Frostig, Peter Hawkins, Matthew James Johnson, Chris Leary, Dougal Maclaurin, Skye Wanderman-Milne, 2018
https://scholar.google.com/scholar?q=JAX%3A+composable+transformations+of+Python%2BNumPy+programs
6. Chainer: A Next-Generation Open Source Framework for Deep Learning — Seiya Tokui, Kenta Oono, Shohei Hido, Justin Clayton, 2015
https://scholar.google.com/scholar?q=Chainer%3A+A+Next-Generation+Open+Source+Framework+for+Deep+Learning
7. Automatic Differentiation in PyTorch — Adam Paszke, Sam Gross, Soumith Chintala, Gregory Chanan, et al., 2017
https://scholar.google.com/scholar?q=Automatic+Differentiation+in+PyTorch
8. Training Deep Nets with Sublinear Memory Cost — Tianqi Chen, Bing Xu, Chiyuan Zhang, Carlos Guestrin, 2016
https://scholar.google.com/scholar?q=Training+Deep+Nets+with+Sublinear+Memory+Cost
9. Reducing Activation Recomputation in Large Transformer Models — Vijay Korthikanti, Jared Casper, Sangkug Lym, Lawrence McAfee, Michael Andersch, Mohammad Shoeybi, Bryan Catanzaro, 2022
https://scholar.google.com/scholar?q=Reducing+Activation+Recomputation+in+Large+Transformer+Models
10. Efficient Rematerialization for Deep Networks — Ravi Kumar, Manish Purohit, Zoya Svitkina, Erik Vee, Joshua Wang, 2019
https://scholar.google.com/scholar?q=Efficient+Rematerialization+for+Deep+Networks
11. Ratel: Optimizing Holistic Data Movement to Fine-Tune 100B Model on a Consumer GPU — Changyue Liao, Mo Sun, Zihan Yang, Jun Xie, Kaiqi Chen, Binhang Yuan, Fei Wu, Zeke Wang, 2025
https://scholar.google.com/scholar?q=Ratel%3A+Optimizing+Holistic+Data+Movement+to+Fine-Tune+100B+Model+on+a+Consumer+GPU
12. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
13. PatrickStar: Parallel Training of Pre-trained Models via a Chunk-based Memory Management — Jiarui Fang, Zilin Zhu, Shenggui Li, Hui Su, Yang Yu, Jie Zhou, Yang You, 2022
https://scholar.google.com/scholar?q=PatrickStar%3A+Parallel+Training+of+Pre-trained+Models+via+a+Chunk-based+Memory+Management
14. GaLore / other optimizer-state-aware memory-efficient training methods — Jiawei Zhao, Zhenyu Zhang, Beidi Chen, Zhangyang Wang, Anima Anandkumar, Yuandong Tian, 2024
https://scholar.google.com/scholar?q=GaLore+%2F+other+optimizer-state-aware+memory-efficient+training+methods
Interactive Visualization: MegaTrain: Training 120B-Parameter Models on a Single GPU