LeanSparse: Shrinking GPU Memory for Sparse-Attention LLM Serving
Nov 4, 2026
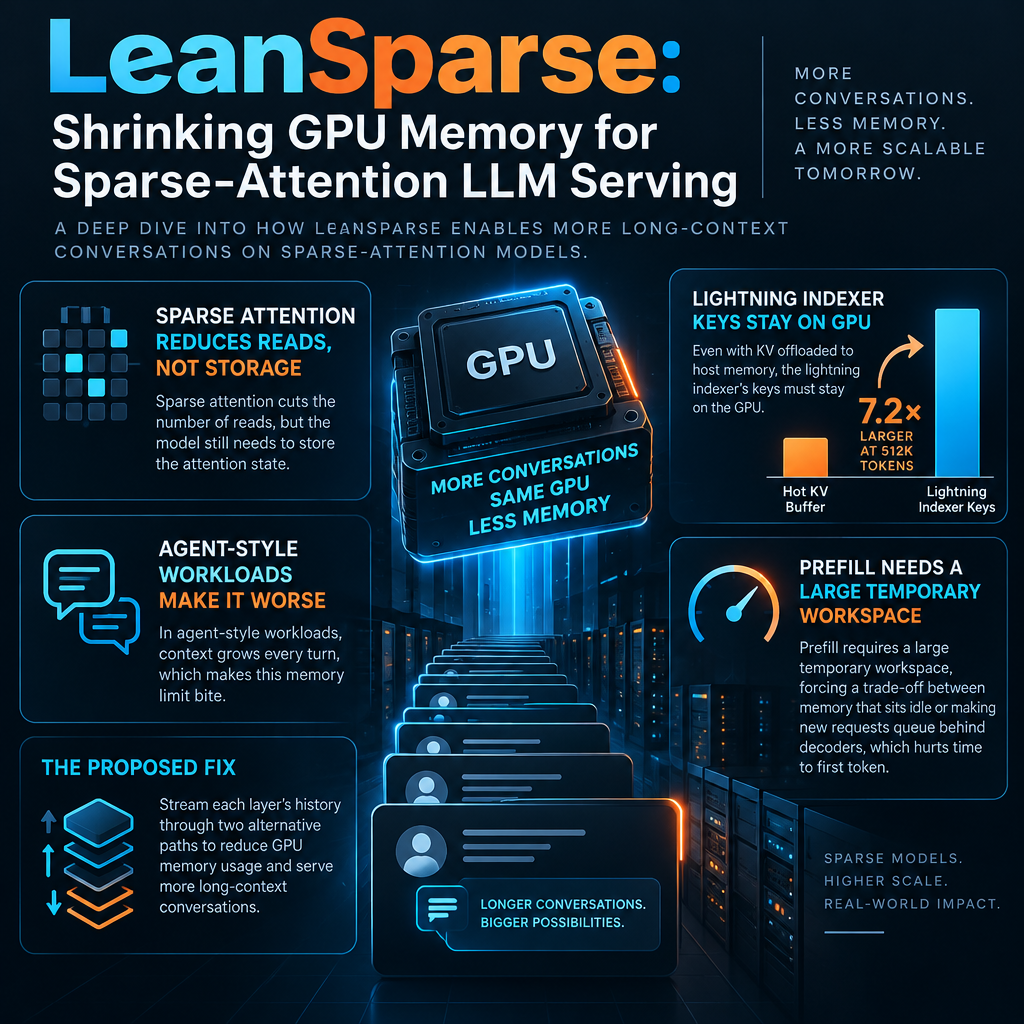
This episode examines LeanSparse, a serving system that cuts the GPU memory needed to hold many long-context conversations on models with native sparse attention, such as DeepSeek-V4-Flash. It explains why sparse attention reduces reads but not storage. Even with KV offloaded to host memory, the lightning indexer's keys must stay on the GPU, and at 512K tokens they take about 7.2 times the space of the hot KV buffer. It also covers why agent-style workloads, where context grows every turn, make this memory limit bite, and why prefill needs a large temporary workspace. That workspace forces a bad choice between reserving memory that sits idle and making new requests queue behind decoders, which hurts time to first token. The proposed fixes are to stream each layer's history through two alternating GPU buffers during prefill, and to search compact indexer keys during decode, fetching only a short list of originals to rank exactly. All of this runs on a shared instance, avoiding the duplicated weights of prefill-decode disaggregation. Listeners get a clear walkthrough of where memory goes in modern sparse-attention serving, plus the reasoning behind why the obvious fix of offloading the indexer keys fails.
Interactive Visualization: LeanSparse: Shrinking GPU Memory for Sparse-Attention LLM Serving
Sources:
1. LeanSparse: Memory-Efficient Serving for Native Sparse-Attention LLMs — Zaifeng Pan, Chris Wu, Xinwei Qiang, Zhengding Hu, Zhongkai Yu, Yufei Ding, 2026
http://arxiv.org/abs/2611.04671
2. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention — Jingyang Yuan, Huazuo Gao, Damai Dai, et al. (DeepSeek-AI, Peking University), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention
3. DeepSeek-V3.2-Exp technical report (DeepSeek Sparse Attention, DSA) — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2-Exp+technical+report+%28DeepSeek+Sparse+Attention%2C+DSA%29
4. MoBA: Mixture of Block Attention for Long-Context LLMs — Enzhe Lu, Zhejun Jiang, Jingyuan Liu, et al. (Moonshot AI), 2025
https://scholar.google.com/scholar?q=MoBA%3A+Mixture+of+Block+Attention+for+Long-Context+LLMs
5. Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference — Jiaming Tang, Yilong Zhao, Kan Zhu, Guangxuan Xiao, Baris Kasikci, Song Han, 2024
https://scholar.google.com/scholar?q=Quest%3A+Query-Aware+Sparsity+for+Efficient+Long-Context+LLM+Inference
6. InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management — Wonbeom Lee, Jungi Lee, Junghwan Seo, Jaewoong Sim, 2024
https://scholar.google.com/scholar?q=InfiniGen%3A+Efficient+Generative+Inference+of+Large+Language+Models+with+Dynamic+KV+Cache+Management
7. ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM Inference — Hanshi Sun, Li-Wen Chang, Wenlei Bao, et al., 2024
https://scholar.google.com/scholar?q=ShadowKV%3A+KV+Cache+in+Shadows+for+High-Throughput+Long-Context+LLM+Inference
8. RetrievalAttention: Accelerating Long-Context LLM Inference via Vector Retrieval — Di Liu, Meng Chen, Baotong Lu, et al., 2024
https://scholar.google.com/scholar?q=RetrievalAttention%3A+Accelerating+Long-Context+LLM+Inference+via+Vector+Retrieval
9. Billion-scale similarity search with GPUs (FAISS) — Jeff Johnson, Matthijs Douze, Hervé Jégou, 2017
https://scholar.google.com/scholar?q=Billion-scale+similarity+search+with+GPUs+%28FAISS%29
10. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin, Zheming Li, Weiran He, et al. (Moonshot AI, Tsinghua), 2024
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
11. DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving — Yinmin Zhong, Shengyu Liu, Junda Chen, et al., 2024
https://scholar.google.com/scholar?q=DistServe%3A+Disaggregating+Prefill+and+Decoding+for+Goodput-optimized+Large+Language+Model+Serving
12. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve — Amey Agrawal, Nitin Kedia, Ashish Panwar, et al., 2024
https://scholar.google.com/scholar?q=Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Sarathi-Serve
13. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
14. PQCache: Product Quantization-based KVCache for Long Context LLM Inference — Hailin Zhang et al., 2025
https://scholar.google.com/scholar?q=PQCache%3A+Product+Quantization-based+KVCache+for+Long+Context+LLM+Inference
15. DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models (DeepSeek Sparse Attention) — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2%3A+Pushing+the+Frontier+of+Open+Large+Language+Models+%28DeepSeek+Sparse+Attention%29
16. CachedAttention (AttentionStore): Cost-Efficient LLM Serving for Multi-Turn Conversations — Bin Gao et al., 2024
https://scholar.google.com/scholar?q=CachedAttention+%28AttentionStore%29%3A+Cost-Efficient+LLM+Serving+for+Multi-Turn+Conversations
17. SparseServe: Unlocking Parallelism for Dynamic Sparse Attention in Long-Context LLM Serving — Zhou et al., 2025
https://scholar.google.com/scholar?q=SparseServe%3A+Unlocking+Parallelism+for+Dynamic+Sparse+Attention+in+Long-Context+LLM+Serving
18. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference — Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference
19. Product Quantization for Nearest Neighbor Search — Hervé Jégou, Matthijs Douze, Cordelia Schmid, 2011
https://scholar.google.com/scholar?q=Product+Quantization+for+Nearest+Neighbor+Search
Interactive Visualization: LeanSparse: Shrinking GPU Memory for Sparse-Attention LLM Serving
1. LeanSparse: Memory-Efficient Serving for Native Sparse-Attention LLMs — Zaifeng Pan, Chris Wu, Xinwei Qiang, Zhengding Hu, Zhongkai Yu, Yufei Ding, 2026
http://arxiv.org/abs/2611.04671
2. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention — Jingyang Yuan, Huazuo Gao, Damai Dai, et al. (DeepSeek-AI, Peking University), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention
3. DeepSeek-V3.2-Exp technical report (DeepSeek Sparse Attention, DSA) — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2-Exp+technical+report+%28DeepSeek+Sparse+Attention%2C+DSA%29
4. MoBA: Mixture of Block Attention for Long-Context LLMs — Enzhe Lu, Zhejun Jiang, Jingyuan Liu, et al. (Moonshot AI), 2025
https://scholar.google.com/scholar?q=MoBA%3A+Mixture+of+Block+Attention+for+Long-Context+LLMs
5. Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference — Jiaming Tang, Yilong Zhao, Kan Zhu, Guangxuan Xiao, Baris Kasikci, Song Han, 2024
https://scholar.google.com/scholar?q=Quest%3A+Query-Aware+Sparsity+for+Efficient+Long-Context+LLM+Inference
6. InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management — Wonbeom Lee, Jungi Lee, Junghwan Seo, Jaewoong Sim, 2024
https://scholar.google.com/scholar?q=InfiniGen%3A+Efficient+Generative+Inference+of+Large+Language+Models+with+Dynamic+KV+Cache+Management
7. ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM Inference — Hanshi Sun, Li-Wen Chang, Wenlei Bao, et al., 2024
https://scholar.google.com/scholar?q=ShadowKV%3A+KV+Cache+in+Shadows+for+High-Throughput+Long-Context+LLM+Inference
8. RetrievalAttention: Accelerating Long-Context LLM Inference via Vector Retrieval — Di Liu, Meng Chen, Baotong Lu, et al., 2024
https://scholar.google.com/scholar?q=RetrievalAttention%3A+Accelerating+Long-Context+LLM+Inference+via+Vector+Retrieval
9. Billion-scale similarity search with GPUs (FAISS) — Jeff Johnson, Matthijs Douze, Hervé Jégou, 2017
https://scholar.google.com/scholar?q=Billion-scale+similarity+search+with+GPUs+%28FAISS%29
10. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin, Zheming Li, Weiran He, et al. (Moonshot AI, Tsinghua), 2024
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
11. DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving — Yinmin Zhong, Shengyu Liu, Junda Chen, et al., 2024
https://scholar.google.com/scholar?q=DistServe%3A+Disaggregating+Prefill+and+Decoding+for+Goodput-optimized+Large+Language+Model+Serving
12. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve — Amey Agrawal, Nitin Kedia, Ashish Panwar, et al., 2024
https://scholar.google.com/scholar?q=Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Sarathi-Serve
13. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
14. PQCache: Product Quantization-based KVCache for Long Context LLM Inference — Hailin Zhang et al., 2025
https://scholar.google.com/scholar?q=PQCache%3A+Product+Quantization-based+KVCache+for+Long+Context+LLM+Inference
15. DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models (DeepSeek Sparse Attention) — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2%3A+Pushing+the+Frontier+of+Open+Large+Language+Models+%28DeepSeek+Sparse+Attention%29
16. CachedAttention (AttentionStore): Cost-Efficient LLM Serving for Multi-Turn Conversations — Bin Gao et al., 2024
https://scholar.google.com/scholar?q=CachedAttention+%28AttentionStore%29%3A+Cost-Efficient+LLM+Serving+for+Multi-Turn+Conversations
17. SparseServe: Unlocking Parallelism for Dynamic Sparse Attention in Long-Context LLM Serving — Zhou et al., 2025
https://scholar.google.com/scholar?q=SparseServe%3A+Unlocking+Parallelism+for+Dynamic+Sparse+Attention+in+Long-Context+LLM+Serving
18. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference — Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference
19. Product Quantization for Nearest Neighbor Search — Hervé Jégou, Matthijs Douze, Cordelia Schmid, 2011
https://scholar.google.com/scholar?q=Product+Quantization+for+Nearest+Neighbor+Search
Interactive Visualization: LeanSparse: Shrinking GPU Memory for Sparse-Attention LLM Serving