Knowledge distillation to context distillation
Feb 6, 2026
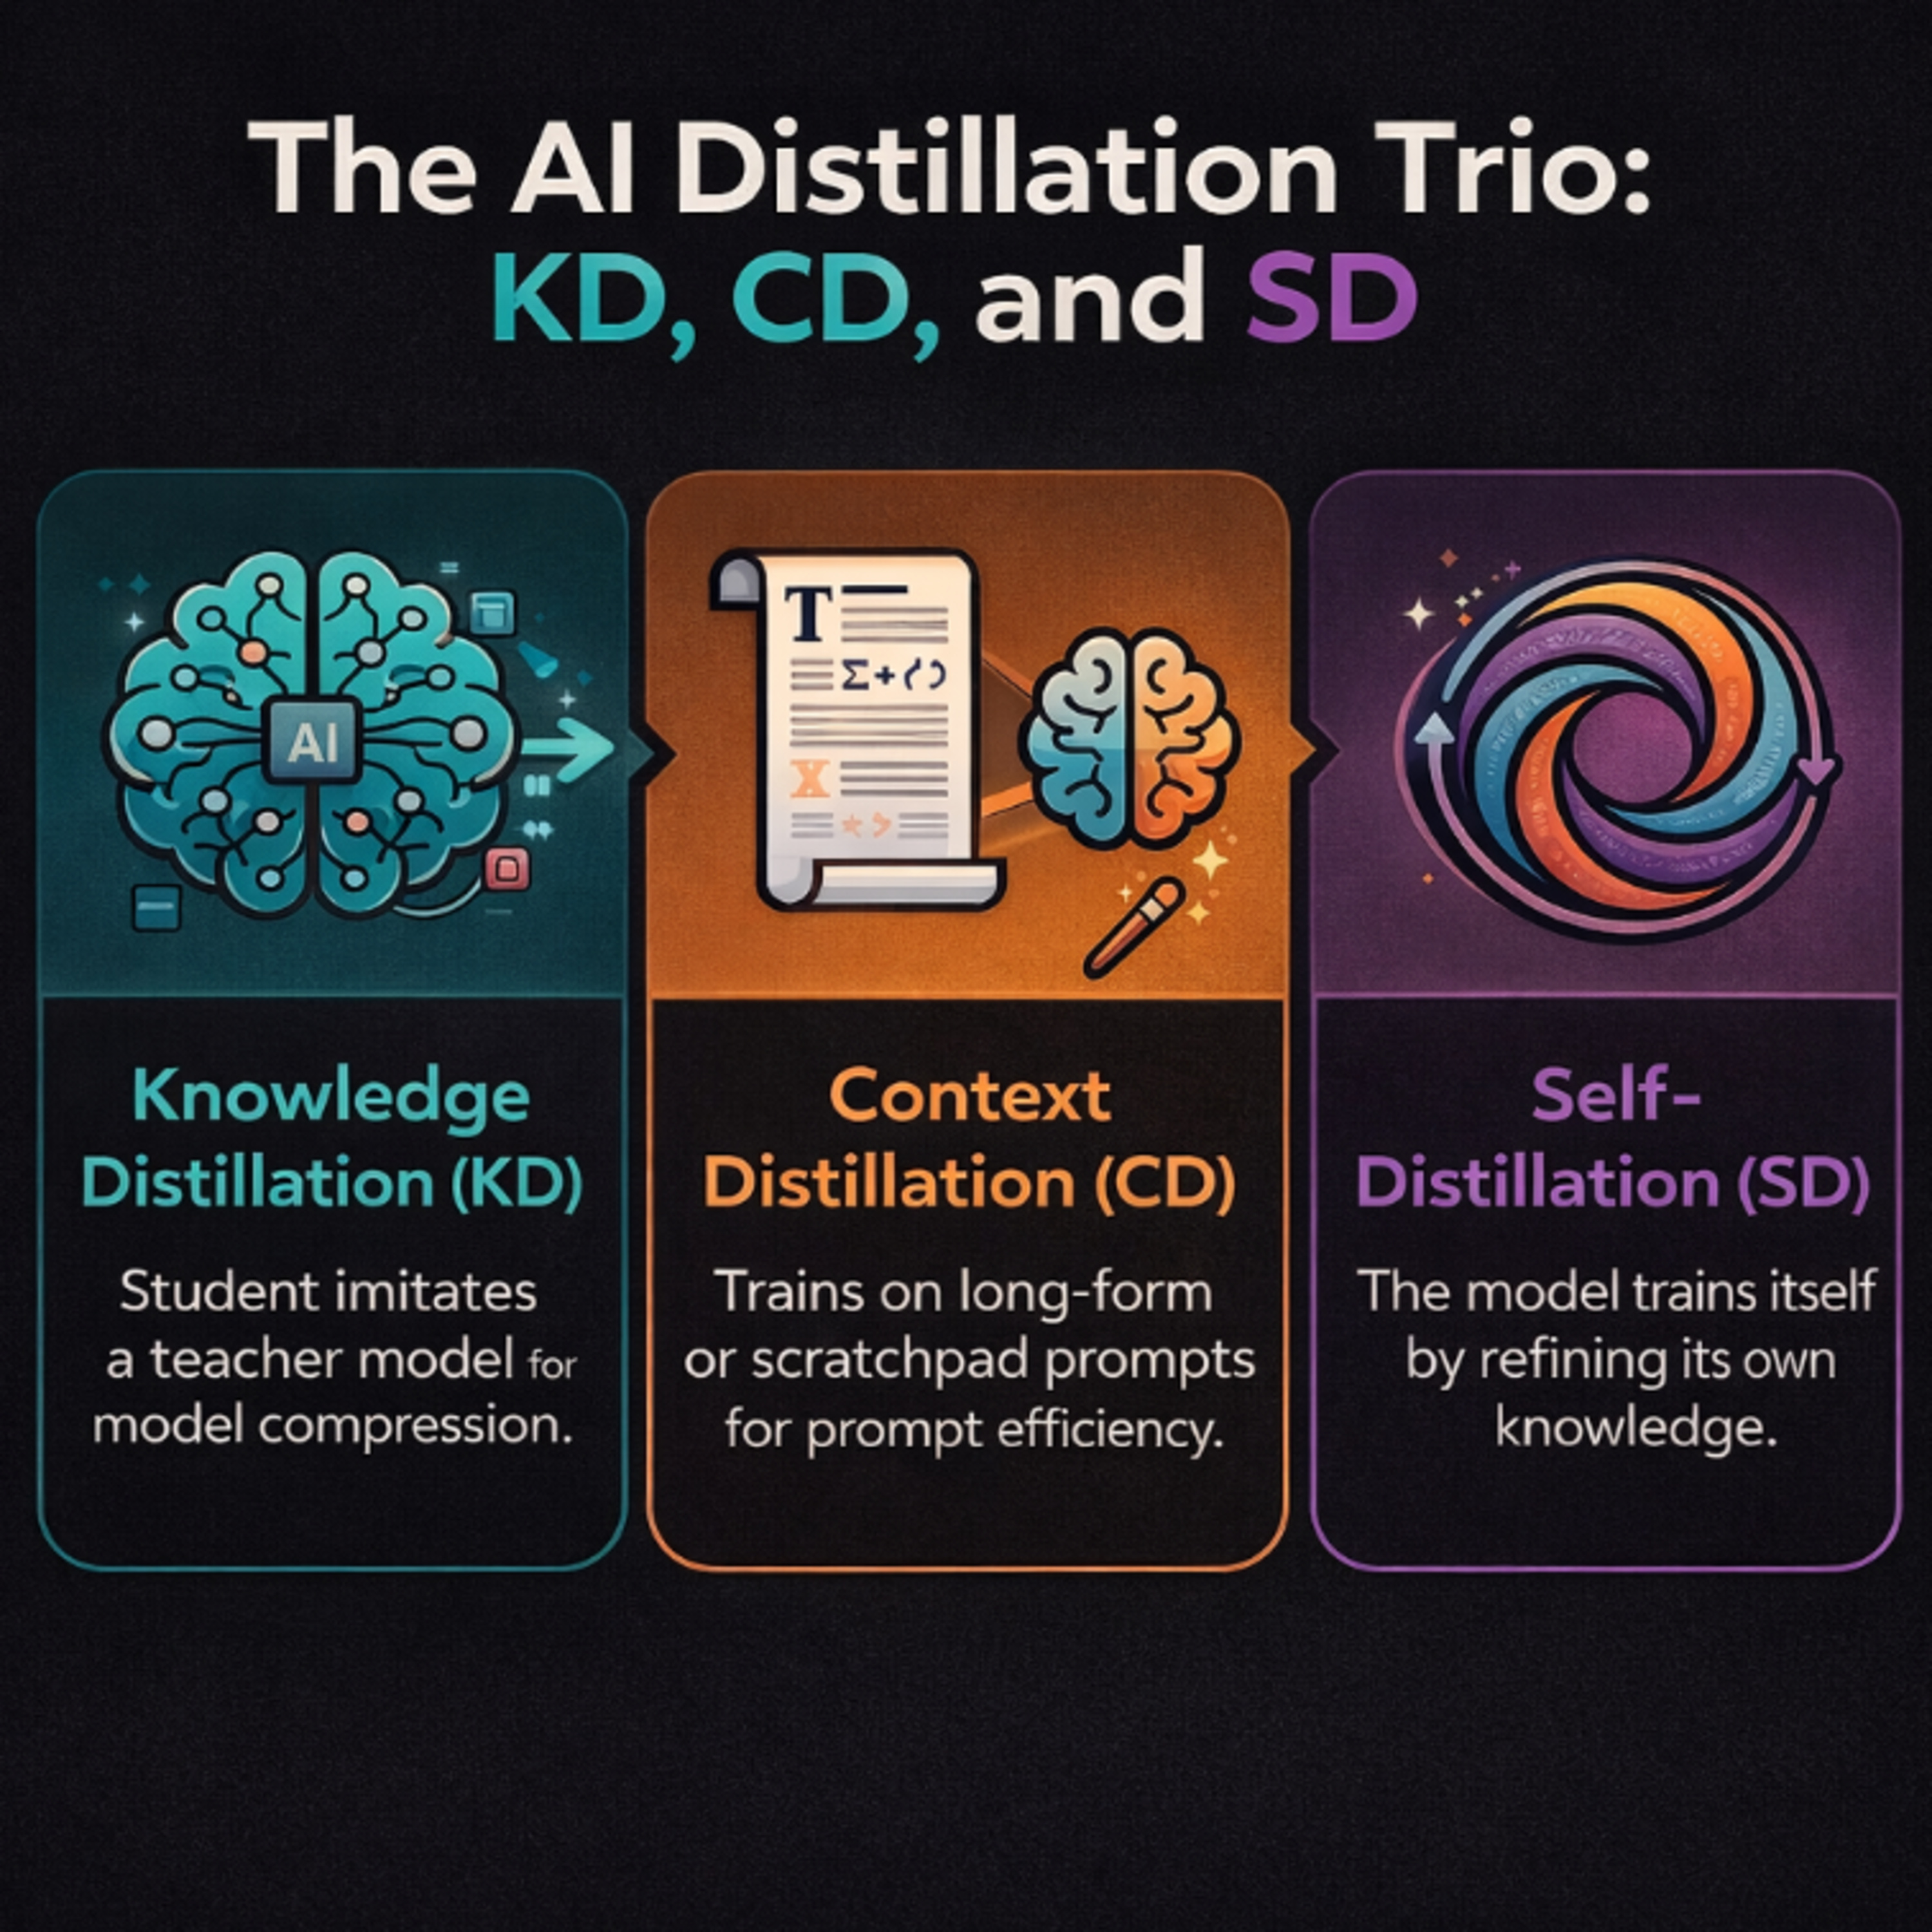
We review the slow evolution of knowledge distillation, it's quick adoption on LLMs and the new wave of R&D on on policy distillation and context distillation. Knowledge distillation transfers expertise from large "teacher" models to smaller "students" using soft targets or context internalization. Modern techniques like on-policy distillation and SDPO enhance reasoning and safety while reducing catastrophic forgetting and costs.
Sources:
1. Title: A Comprehensive Survey on Knowledge DistillationInstitution: Sharif University of TechnologyURL:
https://github.com/IPL-Sharif/KD_Survey
2. Distilling Many-Shot In-Context Learning into a Cheat SheetInstitution: CyberAgentURL:
https://github.com/CyberAgentAILab/cheat-sheet-icl
3. Cartridges: Lightweight and general-purpose long context representations via self-studyInstitution: HazyResearchURL:
https://github.com/HazyResearch/cartridges
4. Dynamic Data-Free Knowledge Distillation by Easy-to-Hard Learning StrategyInstitution: Zhejiang UniversityURL:
https://github.com/ljrprocc/DataFree
5. Distilling the Knowledge in a Neural NetworkInstitution: Google Inc.URL:
https://arxiv.org/pdf/1503.
025316. Knowledge distillationInstitution: WikipediaURL:
https://en.wikipedia.org/w/index.php?title=Knowledge_distillation&oldid=
13320398177. On-Policy DistillationInstitution: Thinking Machines LabURL:
https://thinkingmachines.ai/blog/on-policy-distillation
8. Prompt Compression with Context-Aware Sentence Encoding for Fast and Improved LLM InferenceInstitution: Alterra AI, Queen's University, Workday Inc.URL:
https://github.com/Workday/cpc
9. Reinforcement Learning via Self-DistillationInstitution: ETH Zurich, Max Planck Institute for Intelligent Systems, MIT, StanfordURL:
https://github.com/lasgroup/SDPO
10. Sky-T1: Train your own O1 preview model within $450Institution: NovaSky Team at UC BerkeleyURL:
https://novasky-ai.github.io/posts/sky-t
111. Learning by Distilling ContextInstitution: Not listed in source textURL:
https://arxiv.org/abs/2209.
1518912. A Comprehensive Review of Knowledge Distillation in Computer VisionInstitution: Not listed in source textURL:
https://arxiv.org/abs/2404.
0093613. On-Policy Distillation of Language Models: Learning from Self-Generated MistakesInstitution: Google DeepMind, Mila, University of TorontoURL:
https://arxiv.org/pdf/2306.
1364914. Self-Distilled Reasoner: On-Policy Self-Distillation for Large Language ModelsInstitution: UCLA, HKU, Meta Superintelligence LabsURL:
https://arxiv.org/pdf/2601.
1873415. Self-Distillation Enables Continual LearningInstitution: MIT, Improbable AI Lab, ETH ZurichURL:
http://idanshenfeld.com/SDFT