JustAskJev: One Question Detects Ten AI Failure Modes
Sep 30, 2026
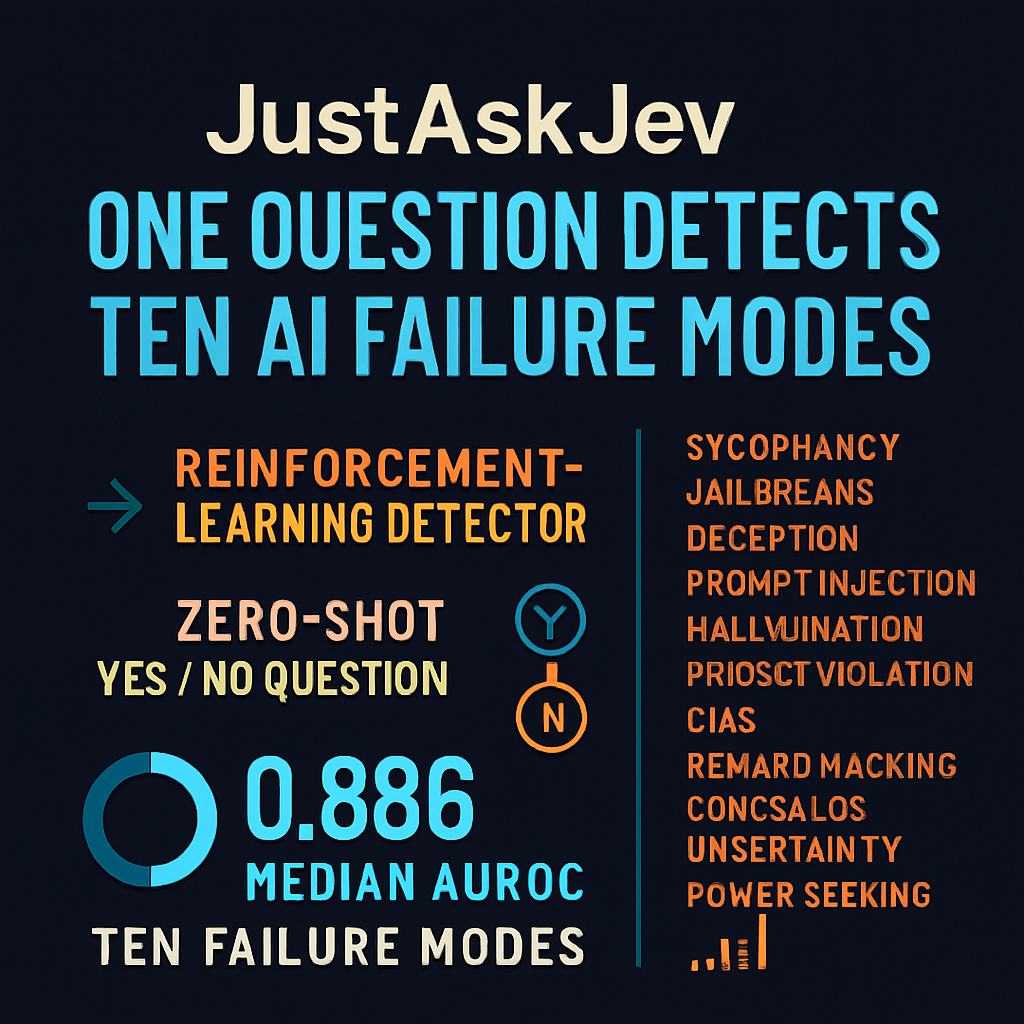
This episode examines JustAskJev, a reinforcement-learning-trained detector that flags AI alignment failures using a single generic yes-or-no question asked in a zero-shot setting. It contrasts this approach with conventional generative LLM-as-judge and classifier-based detectors like Llama Guard, explaining how RLCD (reinforcement learning for calibrated decisions) lets one model process typed questions—yes/no, categorical, ordinal—against a shared "state" in a single call rather than requiring separate passes per failure type. The discussion covers the paper's headline result: a 0.886 median AUROC across ten distinct failure modes (sycophancy, jailbreaks, deception, prompt injection, hallucination, privacy violation, bias, reward hacking, concealed uncertainty, and power seeking) spanning forty-four benchmarks and five target models. It also unpacks calibration as a property distinct from accuracy, using sycophancy as a case study for why a model's stated confidence needs to track real-world correctness. Listeners interested in AI safety evaluation, model auditing costs, or the mechanics of confidence calibration will find the paper's claims about cheaper, unified failure detection a compelling departure from today's fragmented screening tools.
Interactive Visualization: JustAskJev: One Question Detects Ten AI Failure Modes
Sources:
1. Just Ask Jev: Reinforcement Learning for Calibrated Decisions as a Zero-Shot Detector of AI Alignment Failures — Ruoqi Guo, Yi Liu, Gelei Deng, Yuekang Li, Lida Zhao, Yutao Wu, Simin Chen, Ying Zhang, Leo Yu Zhang, 2026
http://arxiv.org/abs/2609.29429
2. On Calibration of Modern Neural Networks — Chuan Guo, Geoff Pleiss, Yu Sun, Kilian Q. Weinberger, 2017
https://scholar.google.com/scholar?q=On+Calibration+of+Modern+Neural+Networks
3. Language Models (Mostly) Know What They Know — Saurav Kadavath, Tom Conerly, Amanda Askell, and others (Anthropic), 2022
https://scholar.google.com/scholar?q=Language+Models+%28Mostly%29+Know+What+They+Know
4. Just Ask for Calibration: Strategies for Eliciting Calibrated Confidence Scores from Language Models Fine-Tuned with Human Feedback — Katherine Tian, Eric Mitchell, Allan Zhou, Archit Sharma, Rafael Rafailov, Huaxiu Yao, Chelsea Finn, Christopher D. Manning, 2023
https://scholar.google.com/scholar?q=Just+Ask+for+Calibration%3A+Strategies+for+Eliciting+Calibrated+Confidence+Scores+from+Language+Models+Fine-Tuned+with+Human+Feedback
5. Llama Guard: LLM-based Input-Output Safeguard for Human-AI Conversations — Hakan Inan, Kartikeya Upasani, and others (Meta), 2023
https://scholar.google.com/scholar?q=Llama+Guard%3A+LLM-based+Input-Output+Safeguard+for+Human-AI+Conversations
6. Sycophancy to Subterfuge: Investigating Reward-Tampering in Large Language Models — Carson Denison, Monte MacDiarmid, Fazl Barez, et al., 2024
https://scholar.google.com/scholar?q=Sycophancy+to+Subterfuge%3A+Investigating+Reward-Tampering+in+Large+Language+Models
7. The MASK Benchmark: Disentangling Honesty from Accuracy in AI Systems — Richard Ren, Arunim Agarwal, Mantas Mazeika, et al., 2025
https://scholar.google.com/scholar?q=The+MASK+Benchmark%3A+Disentangling+Honesty+from+Accuracy+in+AI+Systems
8. Confident Learning: Estimating Uncertainty in Dataset Labels — Curtis G. Northcutt, Lu Jiang, Isaac L. Chuang, 2021
https://scholar.google.com/scholar?q=Confident+Learning%3A+Estimating+Uncertainty+in+Dataset+Labels
Interactive Visualization: JustAskJev: One Question Detects Ten AI Failure Modes