Jenga: Two-Level Memory Allocation for Heterogeneous LLM Serving
Oct 13, 2026
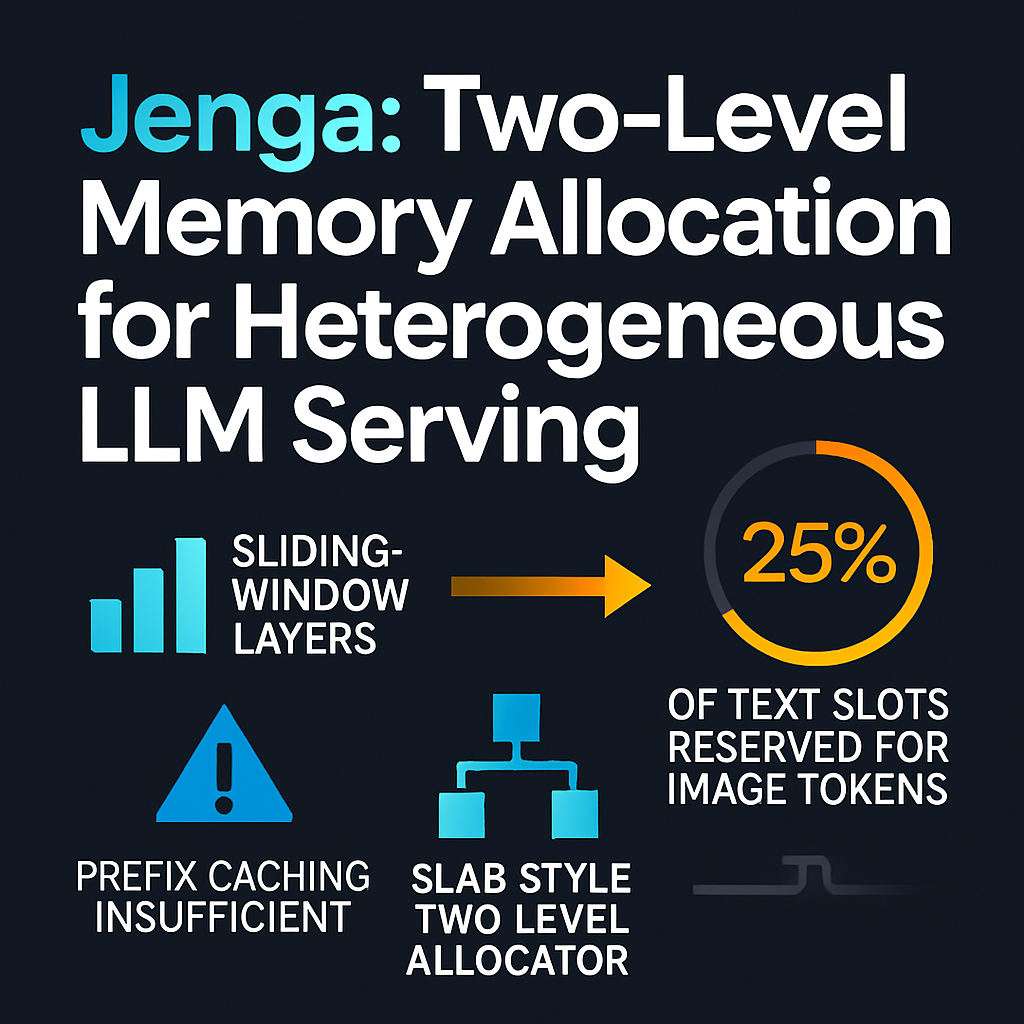
This episode examines "Jenga," a paper from the team behind vLLM's PagedAttention, which asks what that memory manager costs on modern models that break its two core assumptions: that every layer stores identically sized per-token state, and that every layer needs the full prefix. It covers sliding-window layers, Mamba-style recurrent states, and cross-attention vision models. In a Llama 3.2 Vision example, text layers end up reserving slots for image tokens they never read. The discussion also covers why prefix caching and a single global LRU eviction policy no longer work when each layer type needs a different part of the prefix. It then walks through the proposed fix, a slab-style two-level allocator that sizes large pages at the least common multiple of the layer types' entry sizes (a worked toy of 256 and 384 bytes gives 768-byte pages) and lets each layer type split them into its own small pages. Listeners get a clear explanation of how this recovers memory and throughput while working with existing attention kernels.
Interactive Visualization: Jenga: Two-Level Memory Allocation for Heterogeneous LLM Serving
Sources:
1. Jenga: Effective Memory Management for Serving LLM with Heterogeneity — Chen Zhang, Kuntai Du, Shu Liu, Woosuk Kwon, Xiangxi Mo, Yufeng Wang, Xiaoxuan Liu, Kaichao You, Zhuohan Li, Mingsheng Long, Jidong Zhai, Joseph Gonzalez, Ion Stoica, 2025
http://arxiv.org/abs/2503.18292
2. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph Gonzalez, Hao Zhang, Ion Stoica, 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
3. Jenga: Effective Memory Management for Serving LLM with Heterogeneity — Chen Zhang, Kuntai Du, Shu Liu, Woosuk Kwon, Xiangxi Mo, Yufeng Wang, Xiaoxuan Liu, Kaichao You, Zhuohan Li, Mingsheng Long, Jidong Zhai, Joseph Gonzalez, Ion Stoica, 2025
https://scholar.google.com/scholar?q=Jenga%3A+Effective+Memory+Management+for+Serving+LLM+with+Heterogeneity
4. Jamba: A Hybrid Transformer-Mamba Language Model — Opher Lieber et al. (AI21 Labs), 2024
https://scholar.google.com/scholar?q=Jamba%3A+A+Hybrid+Transformer-Mamba+Language+Model
5. Hymba: A Hybrid-head Architecture for Small Language Models — Xin Dong et al. (NVIDIA), 2024
https://scholar.google.com/scholar?q=Hymba%3A+A+Hybrid-head+Architecture+for+Small+Language+Models
6. SGLang: Efficient Execution of Structured Language Model Programs (RadixAttention) — Lianmin Zheng, Liangsheng Yin, Zhiqiang Xie, et al., 2023/2024
https://scholar.google.com/scholar?q=SGLang%3A+Efficient+Execution+of+Structured+Language+Model+Programs+%28RadixAttention%29
7. Marconi: Prefix Caching for the Era of Hybrid LLMs — Rui Pan, Zhuang Wang, Zhen Jia, Can Karakus, Luca Zancato, Tri Dao, Yida Wang, Ravi Netravali, 2024
https://scholar.google.com/scholar?q=Marconi%3A+Prefix+Caching+for+the+Era+of+Hybrid+LLMs
8. Gemma 2: Improving Open Language Models at a Practical Size — Gemma Team, Google DeepMind, 2024
https://scholar.google.com/scholar?q=Gemma+2%3A+Improving+Open+Language+Models+at+a+Practical+Size
9. The Slab Allocator: An Object-Caching Kernel Memory Allocator — Jeff Bonwick, 1994
https://scholar.google.com/scholar?q=The+Slab+Allocator%3A+An+Object-Caching+Kernel+Memory+Allocator
10. vAttention: Dynamic Memory Management for Serving LLMs without PagedAttention — Ramya Prabhu, Ajay Nayak, Jayashree Mohan, Ramachandran Ramjee, Ashish Panwar, 2024
https://scholar.google.com/scholar?q=vAttention%3A+Dynamic+Memory+Management+for+Serving+LLMs+without+PagedAttention
11. SmartSpec: Optimizing Speculative Decoding in a Serving System — Xiaoxuan Liu et al., 2024
https://scholar.google.com/scholar?q=SmartSpec%3A+Optimizing+Speculative+Decoding+in+a+Serving+System
12. MuxServe: Flexible Multiplexing for Efficient Multiple LLM Serving — Jiangfei Duan et al., 2024
https://scholar.google.com/scholar?q=MuxServe%3A+Flexible+Multiplexing+for+Efficient+Multiple+LLM+Serving
13. Mooncake / CachedAttention (KV cache offloading to CPU and disk) — Qin et al.; Gao et al., 2024
https://scholar.google.com/scholar?q=Mooncake+%2F+CachedAttention+%28KV+cache+offloading+to+CPU+and+disk%29
Interactive Visualization: Jenga: Two-Level Memory Allocation for Heterogeneous LLM Serving