Investor's Last Exam: Benchmarking AI Equity Research Without Future Leakage
Nov 1, 2026
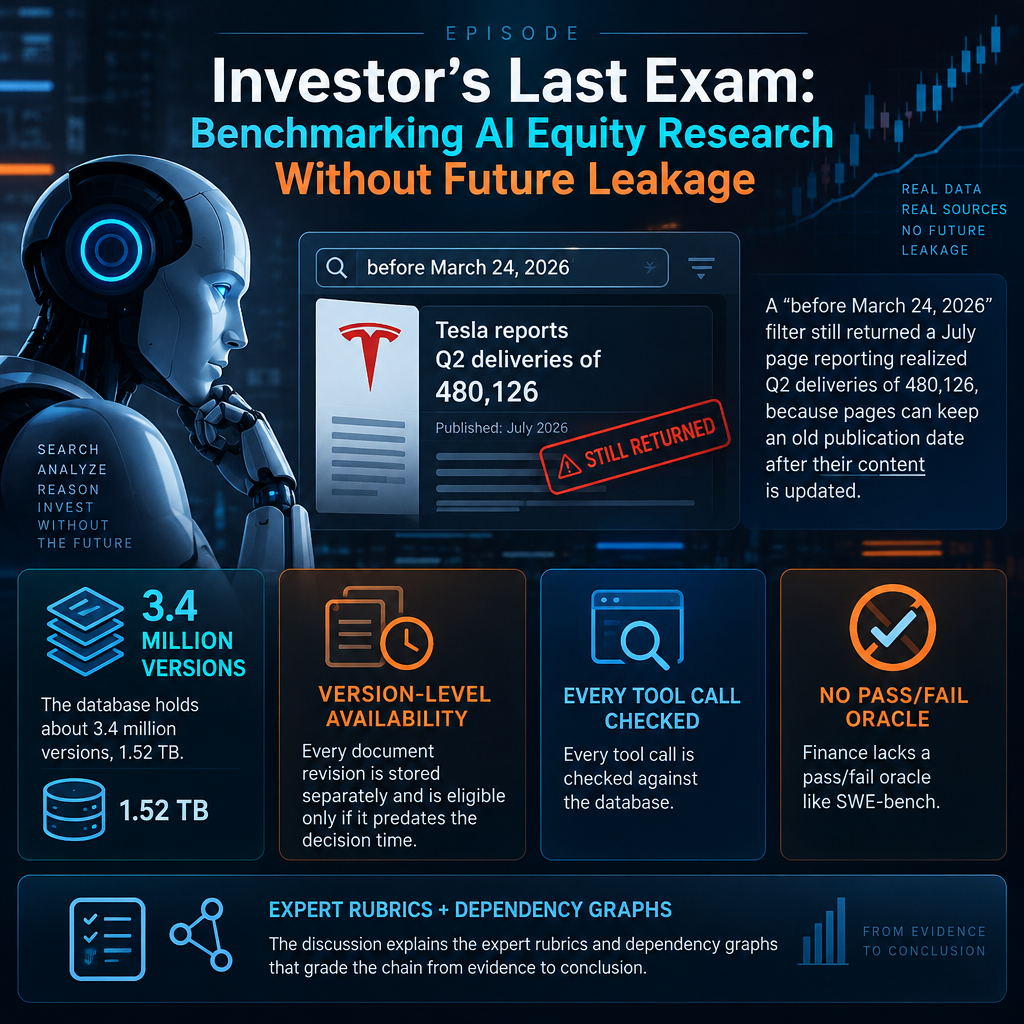
This episode examines a paper that builds a benchmark for testing whether AI agents can do equity investment research without seeing the future. It centers on a Tesla task whose search used a "before March 24, 2026" date filter. The filter still returned a July page reporting realized Q2 deliveries of 480,126, because pages can keep an old publication date after their content is updated. The benchmark's fix is version-level availability: every document revision is stored separately and is eligible only if it predates the decision time. The database holds about 3.4 million versions, 1.52 TB, and every tool call is checked against it. The discussion explains why finance lacks a pass/fail oracle like SWE-bench. It describes the expert rubrics and dependency graphs that grade the chain from evidence to assumptions to judgment. It also covers the three yardsticks of answer quality, forecast outcome and simulated return, which the paper says rank models differently. The hosts separate retrieval leakage from "parametric leakage," meaning outcomes already in a model's pretraining weights, and tie that to prior work on lookahead bias in finance. The episode closes by introducing the 86 buy-side-style tasks, the 11 agent systems and the shared six-tool setup.
Interactive Visualization: Investor's Last Exam: Benchmarking AI Equity Research Without Future Leakage
Sources:
1. Investor's Last Exam: Can AI Agents Do Equity Investment Without Seeing the Future? — Huangfei Jiang, Anning Hu, Kai Sheng, Yuchen Cai, Rui Ge, Xiangyu Kong, Jianghao Lin, Shuzi Chen, Jiyi Weng, Junchi Yan, 2026
http://arxiv.org/abs/2610.38342
2. FinanceBench: A New Benchmark for Financial Question Answering — Pranab Islam, Anand Kannappan, Douwe Kiela, Rebecca Qian, Nino Scherrer, Bertie Vidgen, 2023
https://scholar.google.com/scholar?q=FinanceBench%3A+A+New+Benchmark+for+Financial+Question+Answering
3. BloombergGPT: A Large Language Model for Finance — Shijie Wu, Ozan Irsoy, Steven Lu, Vadim Dabravolski, Mark Dredze, Sebastian Gehrmann, Prabhanjan Kambadur, David Rosenberg, Gideon Mann, 2023
https://scholar.google.com/scholar?q=BloombergGPT%3A+A+Large+Language+Model+for+Finance
4. TradingAgents: Multi-Agents LLM Financial Trading Framework — Yijia Xiao, Edward Sun, Di Luo, Wei Wang, 2024
https://scholar.google.com/scholar?q=TradingAgents%3A+Multi-Agents+LLM+Financial+Trading+Framework
5. Financial Statement Analysis with Large Language Models — Alex G. Kim, Maximilian Muhn, Valeri V. Nikolaev, 2024
https://scholar.google.com/scholar?q=Financial+Statement+Analysis+with+Large+Language+Models
6. Assessing Look-Ahead Bias in Stock Return Predictions Generated By GPT Sentiment Analysis — Paul Glasserman, Caden Lin, 2023
https://scholar.google.com/scholar?q=Assessing+Look-Ahead+Bias+in+Stock+Return+Predictions+Generated+By+GPT+Sentiment+Analysis
7. Lookahead Bias in Pretrained Language Models — Suproteem Sarkar, Keyon Vafa, 2024
https://scholar.google.com/scholar?q=Lookahead+Bias+in+Pretrained+Language+Models
8. Pseudo-Mathematics and Financial Charlatanism: The Effects of Backtest Overfitting on Out-of-Sample Performance — David H. Bailey, Jonathan M. Borwein, Marcos López de Prado, Qiji Jim Zhu, 2014
https://scholar.google.com/scholar?q=Pseudo-Mathematics+and+Financial+Charlatanism%3A+The+Effects+of+Backtest+Overfitting+on+Out-of-Sample+Performance
9. Advances in Financial Machine Learning — Marcos López de Prado, 2018
https://scholar.google.com/scholar?q=Advances+in+Financial+Machine+Learning
10. HealthBench: Evaluating Large Language Models Towards Improved Human Health — Rahul K. Arora et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=HealthBench%3A+Evaluating+Large+Language+Models+Towards+Improved+Human+Health
11. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena — Lianmin Zheng, Wei-Lin Chiang, Ying Sheng, et al., 2023
https://scholar.google.com/scholar?q=Judging+LLM-as-a-Judge+with+MT-Bench+and+Chatbot+Arena
12. Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains — Anisha Gunjal et al., 2025
https://scholar.google.com/scholar?q=Rubrics+as+Rewards%3A+Reinforcement+Learning+Beyond+Verifiable+Domains
13. Humanity's Last Exam — Long Phan et al. (Center for AI Safety and Scale AI), 2025
https://scholar.google.com/scholar?q=Humanity%27s+Last+Exam
14. Approaching Human-Level Forecasting with Language Models — Danny Halawi, Fred Zhang, Chen Yueh-Han, Jacob Steinhardt, 2024
https://scholar.google.com/scholar?q=Approaching+Human-Level+Forecasting+with+Language+Models
15. ForecastBench: A Dynamic Benchmark of AI Forecasting Capabilities — Ezra Karger, Houtan Bastani, Chen Yueh-Han, Zachary Jacobs, Danny Halawi, Fred Zhang, Philip E. Tetlock, 2024
https://scholar.google.com/scholar?q=ForecastBench%3A+A+Dynamic+Benchmark+of+AI+Forecasting+Capabilities
16. Can ChatGPT Forecast Stock Price Movements? Return Predictability and Large Language Models — Alejandro Lopez-Lira, Yuehua Tang, 2023
https://scholar.google.com/scholar?q=Can+ChatGPT+Forecast+Stock+Price+Movements%3F+Return+Predictability+and+Large+Language+Models
17. Chronologically Consistent Large Language Models — Songrun He, Linying Lv, Asaf Manela, Jimmy Wu, 2025
https://scholar.google.com/scholar?q=Chronologically+Consistent+Large+Language+Models
18. Look-Ahead-Bench: A standardized benchmark of look-ahead bias in point-in-time LLMs for finance — Mostapha Benhenda, 2026
https://scholar.google.com/scholar?q=Look-Ahead-Bench%3A+A+standardized+benchmark+of+look-ahead+bias+in+point-in-time+LLMs+for+finance
19. Pitfalls in Evaluating Language Model Forecasters — Daniel Paleka, Shashwat Goel, Jonas Geiping, Florian Tramèr, 2025
https://scholar.google.com/scholar?q=Pitfalls+in+Evaluating+Language+Model+Forecasters
20. Temporal leakage in search-engine date-filtered web retrieval: A retrospective forecasting case study — Ali El Lahib, Ying-Jieh Xia, Zehan Li, Yuxuan Wang, Xinyu Pi, 2026
https://scholar.google.com/scholar?q=Temporal+leakage+in+search-engine+date-filtered+web+retrieval%3A+A+retrospective+forecasting+case+study
21. Bench to the Future: A Pastcasting Benchmark for Forecasting Agents — FutureSearch et al., 2025
https://scholar.google.com/scholar?q=Bench+to+the+Future%3A+A+Pastcasting+Benchmark+for+Forecasting+Agents
22. LLM Evaluators Recognize and Favor Their Own Generations — Arjun Panickssery, Samuel R. Bowman, Shi Feng, 2024
https://scholar.google.com/scholar?q=LLM+Evaluators+Recognize+and+Favor+Their+Own+Generations
23. GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks — Tejal Patwardhan et al., 2025
https://scholar.google.com/scholar?q=GDPval%3A+Evaluating+AI+Model+Performance+on+Real-World+Economically+Valuable+Tasks
24. Advances in Financial Machine Learning (purged and embargoed cross-validation) — Marcos López de Prado, 2018
https://scholar.google.com/scholar?q=Advances+in+Financial+Machine+Learning+%28purged+and+embargoed+cross-validation%29
25. The Deflated Sharpe Ratio: Correcting for Selection Bias, Backtest Overfitting and Non-Normality — David H. Bailey, Marcos López de Prado, 2014
https://scholar.google.com/scholar?q=The+Deflated+Sharpe+Ratio%3A+Correcting+for+Selection+Bias%2C+Backtest+Overfitting+and+Non-Normality
26. StockBench: Can LLM Agents Trade Stocks Profitably in Real-World Markets? — Yanxu Chen et al., 2025
https://scholar.google.com/scholar?q=StockBench%3A+Can+LLM+Agents+Trade+Stocks+Profitably+in+Real-World+Markets%3F
Interactive Visualization: Investor's Last Exam: Benchmarking AI Equity Research Without Future Leakage
1. Investor's Last Exam: Can AI Agents Do Equity Investment Without Seeing the Future? — Huangfei Jiang, Anning Hu, Kai Sheng, Yuchen Cai, Rui Ge, Xiangyu Kong, Jianghao Lin, Shuzi Chen, Jiyi Weng, Junchi Yan, 2026
http://arxiv.org/abs/2610.38342
2. FinanceBench: A New Benchmark for Financial Question Answering — Pranab Islam, Anand Kannappan, Douwe Kiela, Rebecca Qian, Nino Scherrer, Bertie Vidgen, 2023
https://scholar.google.com/scholar?q=FinanceBench%3A+A+New+Benchmark+for+Financial+Question+Answering
3. BloombergGPT: A Large Language Model for Finance — Shijie Wu, Ozan Irsoy, Steven Lu, Vadim Dabravolski, Mark Dredze, Sebastian Gehrmann, Prabhanjan Kambadur, David Rosenberg, Gideon Mann, 2023
https://scholar.google.com/scholar?q=BloombergGPT%3A+A+Large+Language+Model+for+Finance
4. TradingAgents: Multi-Agents LLM Financial Trading Framework — Yijia Xiao, Edward Sun, Di Luo, Wei Wang, 2024
https://scholar.google.com/scholar?q=TradingAgents%3A+Multi-Agents+LLM+Financial+Trading+Framework
5. Financial Statement Analysis with Large Language Models — Alex G. Kim, Maximilian Muhn, Valeri V. Nikolaev, 2024
https://scholar.google.com/scholar?q=Financial+Statement+Analysis+with+Large+Language+Models
6. Assessing Look-Ahead Bias in Stock Return Predictions Generated By GPT Sentiment Analysis — Paul Glasserman, Caden Lin, 2023
https://scholar.google.com/scholar?q=Assessing+Look-Ahead+Bias+in+Stock+Return+Predictions+Generated+By+GPT+Sentiment+Analysis
7. Lookahead Bias in Pretrained Language Models — Suproteem Sarkar, Keyon Vafa, 2024
https://scholar.google.com/scholar?q=Lookahead+Bias+in+Pretrained+Language+Models
8. Pseudo-Mathematics and Financial Charlatanism: The Effects of Backtest Overfitting on Out-of-Sample Performance — David H. Bailey, Jonathan M. Borwein, Marcos López de Prado, Qiji Jim Zhu, 2014
https://scholar.google.com/scholar?q=Pseudo-Mathematics+and+Financial+Charlatanism%3A+The+Effects+of+Backtest+Overfitting+on+Out-of-Sample+Performance
9. Advances in Financial Machine Learning — Marcos López de Prado, 2018
https://scholar.google.com/scholar?q=Advances+in+Financial+Machine+Learning
10. HealthBench: Evaluating Large Language Models Towards Improved Human Health — Rahul K. Arora et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=HealthBench%3A+Evaluating+Large+Language+Models+Towards+Improved+Human+Health
11. Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena — Lianmin Zheng, Wei-Lin Chiang, Ying Sheng, et al., 2023
https://scholar.google.com/scholar?q=Judging+LLM-as-a-Judge+with+MT-Bench+and+Chatbot+Arena
12. Rubrics as Rewards: Reinforcement Learning Beyond Verifiable Domains — Anisha Gunjal et al., 2025
https://scholar.google.com/scholar?q=Rubrics+as+Rewards%3A+Reinforcement+Learning+Beyond+Verifiable+Domains
13. Humanity's Last Exam — Long Phan et al. (Center for AI Safety and Scale AI), 2025
https://scholar.google.com/scholar?q=Humanity%27s+Last+Exam
14. Approaching Human-Level Forecasting with Language Models — Danny Halawi, Fred Zhang, Chen Yueh-Han, Jacob Steinhardt, 2024
https://scholar.google.com/scholar?q=Approaching+Human-Level+Forecasting+with+Language+Models
15. ForecastBench: A Dynamic Benchmark of AI Forecasting Capabilities — Ezra Karger, Houtan Bastani, Chen Yueh-Han, Zachary Jacobs, Danny Halawi, Fred Zhang, Philip E. Tetlock, 2024
https://scholar.google.com/scholar?q=ForecastBench%3A+A+Dynamic+Benchmark+of+AI+Forecasting+Capabilities
16. Can ChatGPT Forecast Stock Price Movements? Return Predictability and Large Language Models — Alejandro Lopez-Lira, Yuehua Tang, 2023
https://scholar.google.com/scholar?q=Can+ChatGPT+Forecast+Stock+Price+Movements%3F+Return+Predictability+and+Large+Language+Models
17. Chronologically Consistent Large Language Models — Songrun He, Linying Lv, Asaf Manela, Jimmy Wu, 2025
https://scholar.google.com/scholar?q=Chronologically+Consistent+Large+Language+Models
18. Look-Ahead-Bench: A standardized benchmark of look-ahead bias in point-in-time LLMs for finance — Mostapha Benhenda, 2026
https://scholar.google.com/scholar?q=Look-Ahead-Bench%3A+A+standardized+benchmark+of+look-ahead+bias+in+point-in-time+LLMs+for+finance
19. Pitfalls in Evaluating Language Model Forecasters — Daniel Paleka, Shashwat Goel, Jonas Geiping, Florian Tramèr, 2025
https://scholar.google.com/scholar?q=Pitfalls+in+Evaluating+Language+Model+Forecasters
20. Temporal leakage in search-engine date-filtered web retrieval: A retrospective forecasting case study — Ali El Lahib, Ying-Jieh Xia, Zehan Li, Yuxuan Wang, Xinyu Pi, 2026
https://scholar.google.com/scholar?q=Temporal+leakage+in+search-engine+date-filtered+web+retrieval%3A+A+retrospective+forecasting+case+study
21. Bench to the Future: A Pastcasting Benchmark for Forecasting Agents — FutureSearch et al., 2025
https://scholar.google.com/scholar?q=Bench+to+the+Future%3A+A+Pastcasting+Benchmark+for+Forecasting+Agents
22. LLM Evaluators Recognize and Favor Their Own Generations — Arjun Panickssery, Samuel R. Bowman, Shi Feng, 2024
https://scholar.google.com/scholar?q=LLM+Evaluators+Recognize+and+Favor+Their+Own+Generations
23. GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks — Tejal Patwardhan et al., 2025
https://scholar.google.com/scholar?q=GDPval%3A+Evaluating+AI+Model+Performance+on+Real-World+Economically+Valuable+Tasks
24. Advances in Financial Machine Learning (purged and embargoed cross-validation) — Marcos López de Prado, 2018
https://scholar.google.com/scholar?q=Advances+in+Financial+Machine+Learning+%28purged+and+embargoed+cross-validation%29
25. The Deflated Sharpe Ratio: Correcting for Selection Bias, Backtest Overfitting and Non-Normality — David H. Bailey, Marcos López de Prado, 2014
https://scholar.google.com/scholar?q=The+Deflated+Sharpe+Ratio%3A+Correcting+for+Selection+Bias%2C+Backtest+Overfitting+and+Non-Normality
26. StockBench: Can LLM Agents Trade Stocks Profitably in Real-World Markets? — Yanxu Chen et al., 2025
https://scholar.google.com/scholar?q=StockBench%3A+Can+LLM+Agents+Trade+Stocks+Profitably+in+Real-World+Markets%3F
Interactive Visualization: Investor's Last Exam: Benchmarking AI Equity Research Without Future Leakage