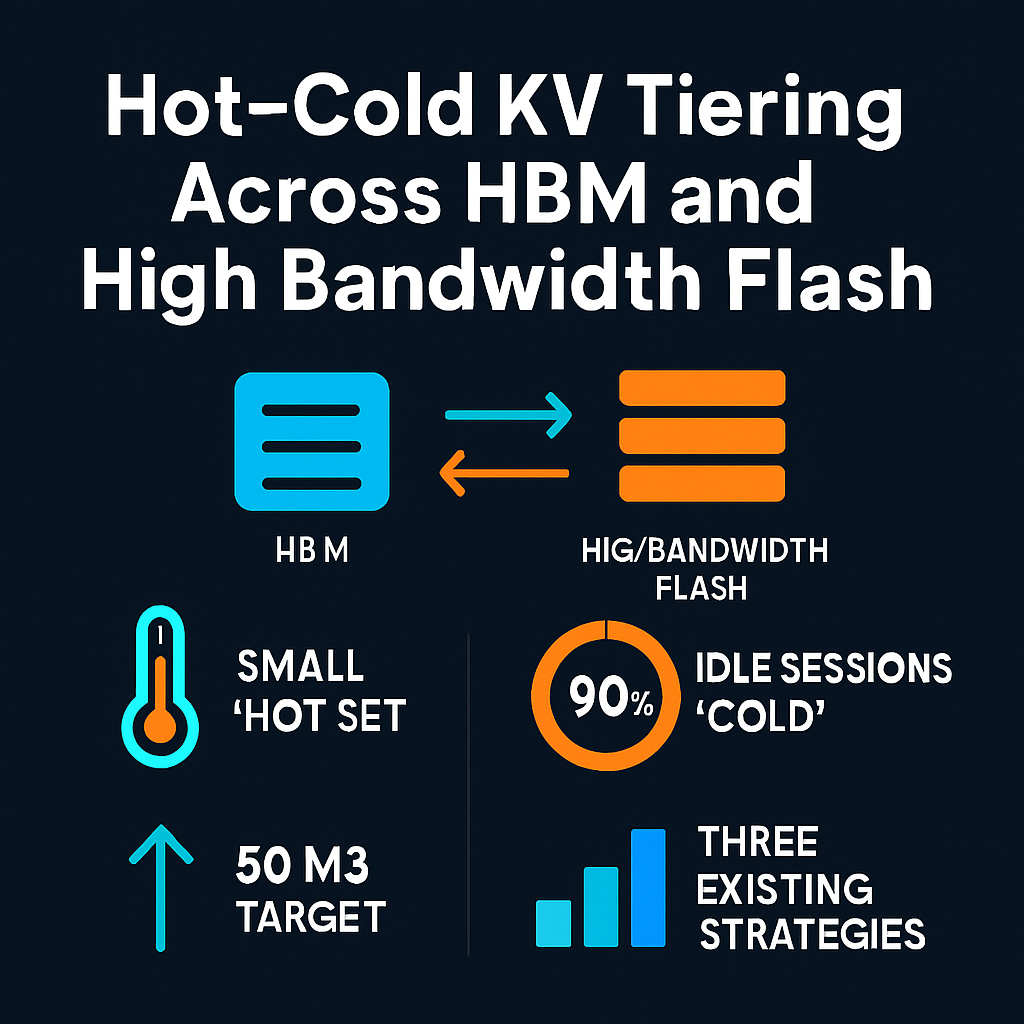
Hot–Cold KV Tiering Across HBM and High Bandwidth Flash
Oct 5, 2026
This episode examines a four-page IEEE Computer Architecture Letter proposing that agentic LLM serving split KV cache by temperature: HBM keeps the small "hot" set for sessions actively decoding, while high bandwidth flash (3D NAND stacked behind an HBM-style interface) holds the large "cold" pool of paused sessions. It explains why agent loops of decode, tool call, idle wait and resume leave gigabytes of KV cache parked in expensive memory. It also covers the heavy-tailed idle-gap model, the 50 ms time-between-tokens target, and the three existing options of keeping, offloading or recomputing. The discussion compares the design with software approaches such as InferCept, AttentionStore and Mooncake, and with earlier flash proposals that put all KV in flash. It weighs flash's endurance, page-granularity and read-energy limits against the paper's design, which keeps the GPU from reading flash during decode. The hosts set out the headline claims (14 ms TBT, roughly 0.1 ms resume overhead, 24x sessions per GPU, 7.6 kW saved per 8-GPU node) and plan to test them. Listeners get a clear look at how memory hierarchy design might change for long-running, mostly idle agent sessions.
Sources:
1. Hot-Cold Tiering of HBM and High Bandwidth Flash for Agentic LLM Serving — Jongjin Baek, Won Ji, Seungjae Yoo, Joo-Young Kim, 2026
http://arxiv.org/abs/2609.25782
2. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph E. Gonzalez, Hao Zhang, Ion Stoica, 2023 (SOSP)
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
3. Cost-Efficient Large Language Model Serving for Multi-turn Conversations with CachedAttention (AttentionStore) — Bin Gao, Zhuomin He, Puru Sharma, Qingxuan Kang, Djordje Jevdjic, Junbo Deng, Xingkun Yang, Zhou Yu, Pengfei Zuo, 2024 (USENIX ATC)
https://scholar.google.com/scholar?q=Cost-Efficient+Large+Language+Model+Serving+for+Multi-turn+Conversations+with+CachedAttention+%28AttentionStore%29
4. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin, Zheming Li, Weiran He, Mingxing Zhang, Yongwei Wu, Weimin Zheng, Xinran Xu, 2024 (arXiv; FAST 2025)
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
5. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, Beidi Chen, Percy Liang, Christopher Ré, Ion Stoica, Ce Zhang, 2023 (ICML)
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
6. ReAct: Synergizing Reasoning and Acting in Language Models — Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik Narasimhan, Yuan Cao, 2022 (ICLR 2023)
https://scholar.google.com/scholar?q=ReAct%3A+Synergizing+Reasoning+and+Acting+in+Language+Models
7. InferCept: Efficient Intercept Support for Augmented Large Language Model Inference — Reyna Abhyankar, Zijian He, Vikranth Srivatsa, Hao Zhang, Yiying Zhang, 2024 (ICML)
https://scholar.google.com/scholar?q=InferCept%3A+Efficient+Intercept+Support+for+Augmented+Large+Language+Model+Inference
8. Continuum: Efficient and Robust Multi-Turn LLM Agent Scheduling with KV Cache Time-to-Live — Hanchen Li and collaborators, 2025 (arXiv)
https://scholar.google.com/scholar?q=Continuum%3A+Efficient+and+Robust+Multi-Turn+LLM+Agent+Scheduling+with+KV+Cache+Time-to-Live
9. Challenges and Research Directions for Large Language Model Inference Hardware — Xiaoyu Ma, David Patterson, 2026 (arXiv)
https://scholar.google.com/scholar?q=Challenges+and+Research+Directions+for+Large+Language+Model+Inference+Hardware
10. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Yihua Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
11. Tokencake: A KV-Cache-Centric Serving Framework for LLM-Based Multi-Agent Applications — Z. Bian et al., 2026
https://scholar.google.com/scholar?q=Tokencake%3A+A+KV-Cache-Centric+Serving+Framework+for+LLM-Based+Multi-Agent+Applications
12. Stateful Large Language Model Serving with Pensieve — Lingfan Yu, Jinyang Li et al., 2025
https://scholar.google.com/scholar?q=Stateful+Large+Language+Model+Serving+with+Pensieve
13. H3: Hybrid Architecture using High Bandwidth Memory and High Bandwidth Flash for Cost-Efficient LLM Inference — M. Ha et al., 2026
https://scholar.google.com/scholar?q=H3%3A+Hybrid+Architecture+using+High+Bandwidth+Memory+and+High+Bandwidth+Flash+for+Cost-Efficient+LLM+Inference
14. Efficient Memory Management for Large Language Model Serving with PagedAttention (vLLM) — Woosuk Kwon et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention+%28vLLM%29
15. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve — Amey Agrawal et al., 2024
https://scholar.google.com/scholar?q=Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Sarathi-Serve
16. InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management — Wonbeom Lee, Jaewoong Lee, Junhyeok Seo, Jaewoong Sim, 2024
https://scholar.google.com/scholar?q=InfiniGen%3A+Efficient+Generative+Inference+of+Large+Language+Models+with+Dynamic+KV+Cache+Management
17. H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models; SnapKV — Zhenyu Zhang et al. (H2O, 2023); Yuhong Li et al. (SnapKV, 2024), 2023-2024
https://scholar.google.com/scholar?q=H2O%3A+Heavy-Hitter+Oracle+for+Efficient+Generative+Inference+of+Large+Language+Models%3B+SnapKV
18. Marconi: Prefix Caching for the Era of Hybrid LLMs — Rui Pan et al., 2024
https://scholar.google.com/scholar?q=Marconi%3A+Prefix+Caching+for+the+Era+of+Hybrid+LLMs
19. Efficient Memory Management with SGLang RadixAttention / SGLang — Lianmin Zheng et al., 2024
https://scholar.google.com/scholar?q=Efficient+Memory+Management+with+SGLang+RadixAttention+%2F+SGLang
20. Autellix: An Efficient Serving Engine for LLM Agents as General Programs — Michael Luo et al., 2025
https://scholar.google.com/scholar?q=Autellix%3A+An+Efficient+Serving+Engine+for+LLM+Agents+as+General+Programs
21. HiFC: High-Efficiency Flash-Based KV Cache Swapping for Scaling LLM Inference — I. Jeong et al., 2026
https://scholar.google.com/scholar?q=HiFC%3A+High-Efficiency+Flash-Based+KV+Cache+Swapping+for+Scaling+LLM+Inference