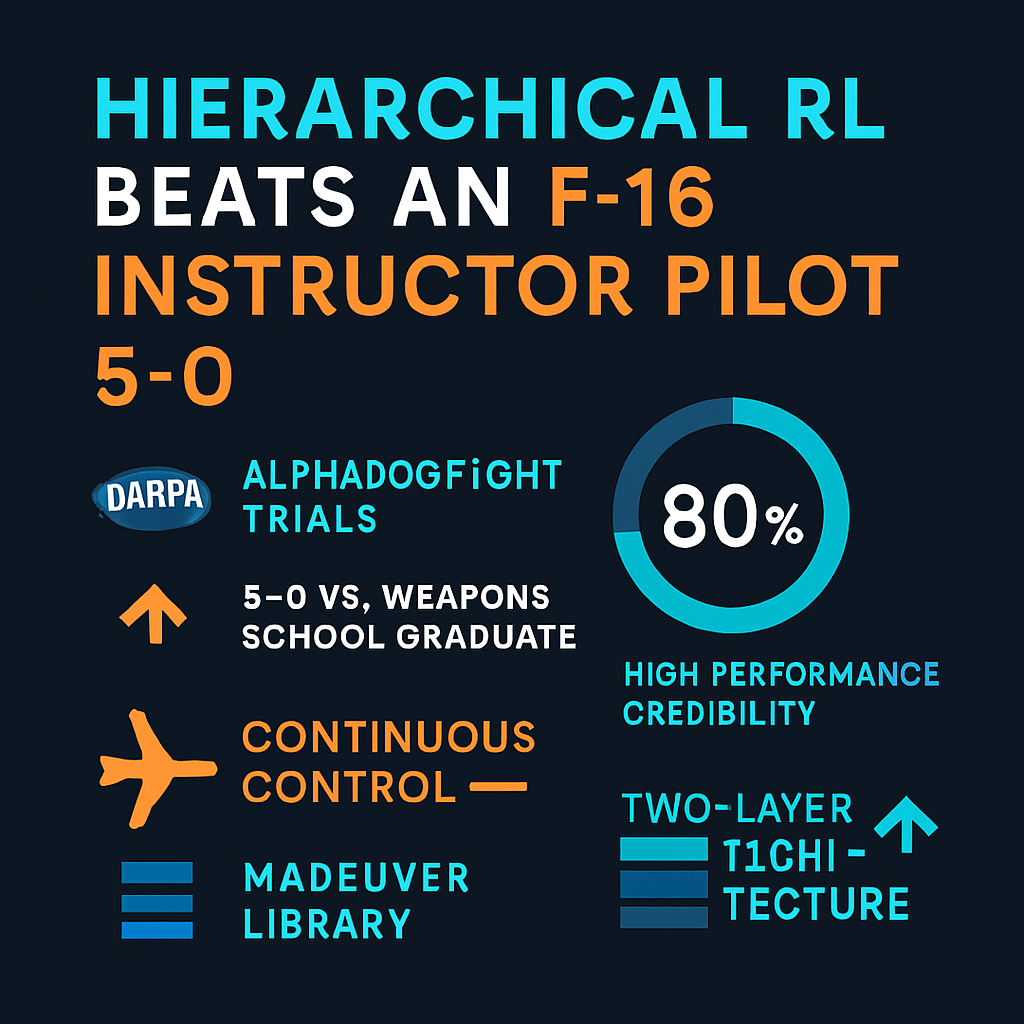
Hierarchical RL Beats an F-16 Instructor Pilot 5-0
Sep 13, 2026
This episode examines "Hierarchical Reinforcement Learning for Air Combat at DARPA's AlphaDogfight Trials," in which the PHANG-MAN agent swept a graduate of the USAF Weapons Instructor Course 5-0 in simulated dogfighting. The discussion traces the DARPA ACE program's rationale for building trust incrementally toward AI-assisted piloted aircraft, and contrasts this work with prior systems like Nick Ernest's genetic fuzzy tree ALPHA, highlighting how PHANG-MAN operates with genuinely continuous stick-and-rudder control in the high-fidelity JSBSim F-16 simulator rather than a maneuver library. It unpacks the two-layer architecture — three frozen, independently-trained low-level Soft Actor-Critic specialist policies (Control Zone, Aggressive Shooter, Conservative Shooter) governed by a higher-frequency policy selector — and explains supporting concepts like curriculum learning and maximum-entropy RL that make the training tractable. Listeners interested in reinforcement learning architecture, autonomous systems trust-building, or the gap between simulated and real-world control will find the technical breakdown of temporally-extended specialist routing especially compelling.
Interactive Visualization: Hierarchical RL Beats an F-16 Instructor Pilot 5-0
Sources:
1. Hierarchical Reinforcement Learning for Air Combat at DARPA's AlphaDogfight Trials — Adrian P. Pope, Jaime S. Ide, Daria Micovic, Henry Diaz, David Rosenbluth, Lee Ritholtz, Jason C. Twedt, Thayne T. Walker, Kevin Alcedo, Daniel Javorsek, 2021
http://arxiv.org/abs/2105.00990
2. Feudal Reinforcement Learning — Peter Dayan, Geoffrey Hinton, 1993
https://scholar.google.com/scholar?q=Feudal+Reinforcement+Learning
3. Hierarchical Reinforcement Learning with the MAXQ Value Function Decomposition — Thomas G. Dietterich, 2000
https://scholar.google.com/scholar?q=Hierarchical+Reinforcement+Learning+with+the+MAXQ+Value+Function+Decomposition
4. FeUdal Networks for Hierarchical Reinforcement Learning — Alexander Sasha Vezhnevets, Simon Osindero, Tom Schaul, Nicolas Heess, Max Jaderberg, David Silver, Koray Kavukcuoglu, 2017
https://scholar.google.com/scholar?q=FeUdal+Networks+for+Hierarchical+Reinforcement+Learning
5. The Option-Critic Architecture — Pierre-Luc Bacon, Jean Harb, Doina Precup, 2017
https://scholar.google.com/scholar?q=The+Option-Critic+Architecture
6. Curriculum Learning — Yoshua Bengio, Jerome Louradour, Ronan Collobert, Jason Weston, 2009
https://scholar.google.com/scholar?q=Curriculum+Learning
7. Reverse Curriculum Generation for Reinforcement Learning — Carlos Florensa, David Held, Markus Wulfmeier, Michael Zhang, Pieter Abbeel, 2017
https://scholar.google.com/scholar?q=Reverse+Curriculum+Generation+for+Reinforcement+Learning
8. Automatic Goal Generation for Reinforcement Learning Agents — Carlos Florensa, David Held, Xinyang Geng, Pieter Abbeel, 2018
https://scholar.google.com/scholar?q=Automatic+Goal+Generation+for+Reinforcement+Learning+Agents
9. Dota 2 with Large Scale Deep Reinforcement Learning — OpenAI (Christopher Berner, Greg Brockman, Brooke Chan, et al.), 2019
https://scholar.google.com/scholar?q=Dota+2+with+Large+Scale+Deep+Reinforcement+Learning
10. Reinforcement Learning with Deep Energy-Based Policies — Tuomas Haarnoja, Haoran Tang, Pieter Abbeel, Sergey Levine, 2017
https://scholar.google.com/scholar?q=Reinforcement+Learning+with+Deep+Energy-Based+Policies
11. Soft Actor-Critic: Off-Policy Maximum Entropy Deep Reinforcement Learning with a Stochastic Actor — Tuomas Haarnoja, Aurick Zhou, Pieter Abbeel, Sergey Levine, 2018
https://scholar.google.com/scholar?q=Soft+Actor-Critic%3A+Off-Policy+Maximum+Entropy+Deep+Reinforcement+Learning+with+a+Stochastic+Actor
12. Soft Actor-Critic Algorithms and Applications — Tuomas Haarnoja, Aurick Zhou, Kristian Hartikainen, George Tucker, Sehoon Ha, Jie Tan, Vikash Kumar, Henry Zhu, Abhishek Gupta, Pieter Abbeel, Sergey Levine, 2018
https://scholar.google.com/scholar?q=Soft+Actor-Critic+Algorithms+and+Applications
13. Maximum Entropy Inverse Reinforcement Learning — Brian D. Ziebart, Andrew Maas, J. Andrew Bagnell, Anind K. Dey, 2008
https://scholar.google.com/scholar?q=Maximum+Entropy+Inverse+Reinforcement+Learning
14. Meta Learning Shared Hierarchies — K. Frans, J. Ho, X. Chen, P. Abbeel, J. Schulman, 2018
https://scholar.google.com/scholar?q=Meta+Learning+Shared+Hierarchies
15. Data-Efficient Hierarchical Reinforcement Learning (HIRO) — O. Nachum, S. Gu, H. Lee, S. Levine, 2018
https://scholar.google.com/scholar?q=Data-Efficient+Hierarchical+Reinforcement+Learning+%28HIRO%29
16. Genetic Fuzzy based Artificial Intelligence for Unmanned Combat Aerial Vehicle Control in Simulated Air Combat Missions — N. Ernest, D. Carroll, C. Schumacher, M. Clark, K. Cohen, G. Lee, 2016
https://scholar.google.com/scholar?q=Genetic+Fuzzy+based+Artificial+Intelligence+for+Unmanned+Combat+Aerial+Vehicle+Control+in+Simulated+Air+Combat+Missions
17. Multi-agent hierarchical policy gradient for air combat tactics emergence via self-play — Z. Sun, H. Piao, Z. Yang, Y. Zhao, et al., 2021
https://scholar.google.com/scholar?q=Multi-agent+hierarchical+policy+gradient+for+air+combat+tactics+emergence+via+self-play
18. Domain Randomization for Transferring Deep Neural Networks from Simulation to the Real World — J. Tobin, R. Fong, A. Ray, J. Schneider, W. Zaremba, P. Abbeel, 2017
https://scholar.google.com/scholar?q=Domain+Randomization+for+Transferring+Deep+Neural+Networks+from+Simulation+to+the+Real+World
Interactive Visualization: Hierarchical RL Beats an F-16 Instructor Pilot 5-0