Full-Bandwidth Transformer: Feeding Hidden States Back Into the Stack
Sep 19, 2026
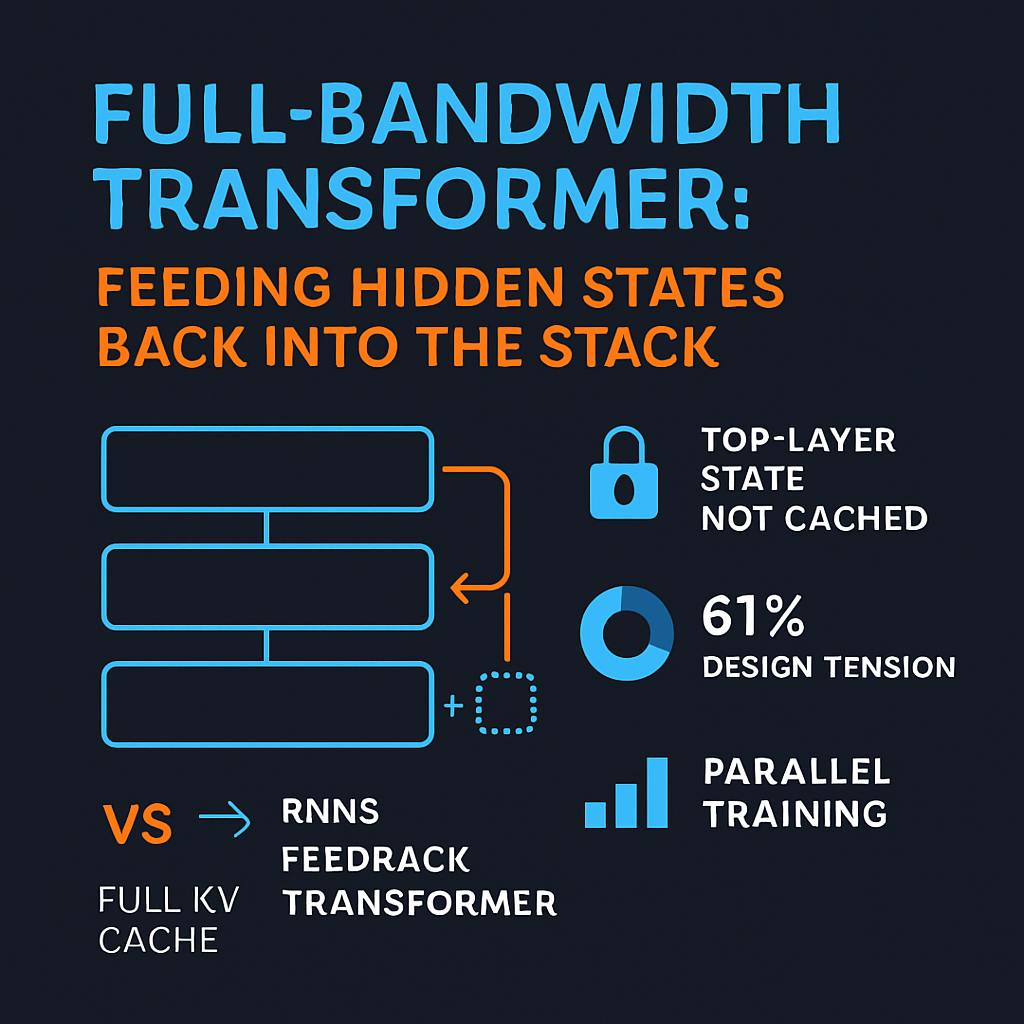
This episode examines "Full-bandwidth transformer," which asks whether a model can feed its entire top-layer hidden state, rather than just the roughly 17-bit sampled token, back into the bottom of the stack at every decoding step. It explains why the KV cache doesn't already solve this: attention is full-bandwidth horizontally, but a state at layer l can only be read by higher layers, and the top layer's output is never cached. The discussion also weighs the design against RNNs and the Feedback Transformer. Nothing is overwritten and the full KV cache is retained, but sequential dependence is the real tension, and it is compared with Coconut, which replaces tokens rather than augmenting them. The hosts then cover how the paper keeps training parallel with multi-pass, Jacobi-style training and a gated fusion of state and token embedding. They cover the pass-mix schedule that keeps decoding stable, where a 75/25 one- and two-pass mix diverges but adding 3% three-pass batches yields a plateau. They set the headline claims aside for scrutiny: about 1.5x effective tokens, matching baselines trained on 2x data, negligible decoding cost, and shorter reasoning traces. Listeners interested in scaling limits, chain-of-thought's depth bottleneck, and getting more out of each training token will find it useful.
Interactive Visualization: Full-Bandwidth Transformer: Feeding Hidden States Back Into the Stack
Sources:
1. Full-bandwidth transformer — Xi Wang, Ziyang Cai, Zheng Zhan, Harry Dong, Ying Fan, Gustavo de Rosa, Tim Pearce, John Langford, 2026
http://arxiv.org/abs/2608.08888
2. Addressing Some Limitations of Transformers with Feedback Memory — Angela Fan, Thibaut Lavril, Edouard Grave, Armand Joulin, Sainbayar Sukhbaatar, 2020 (arXiv; later versions 2021)
https://scholar.google.com/scholar?q=Addressing+Some+Limitations+of+Transformers+with+Feedback+Memory
3. Training Large Language Models to Reason in a Continuous Latent Space (Coconut) — Shibo Hao, Sainbayar Sukhbaatar, DiJia Su, Xian Li, Zhiting Hu, Jason Weston, Yuandong Tian, 2024
https://scholar.google.com/scholar?q=Training+Large+Language+Models+to+Reason+in+a+Continuous+Latent+Space+%28Coconut%29
4. Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach — Jonas Geiping, Sean McLeish, Neel Jain, John Kirchenbauer, Siddharth Singh, Brian Bartoldson, Bhavya Kailkhura, Abhinav Bhatele, Tom Goldstein, 2025
https://scholar.google.com/scholar?q=Scaling+up+Test-Time+Compute+with+Latent+Reasoning%3A+A+Recurrent+Depth+Approach
5. Chain of Thought Empowers Transformers to Solve Inherently Serial Problems — Zhiyuan Li, Hong Liu, Denny Zhou, Tengyu Ma, 2024
https://scholar.google.com/scholar?q=Chain+of+Thought+Empowers+Transformers+to+Solve+Inherently+Serial+Problems
6. Think before you speak: Training Language Models With Pause Tokens — Sachin Goyal, Ziwei Ji, Ankit Singh Rawat, Aditya Krishna Menon, Sanjiv Kumar, Vaishnavh Nagarajan, 2023
https://scholar.google.com/scholar?q=Think+before+you+speak%3A+Training+Language+Models+With+Pause+Tokens
7. PonderLM-2: Pretraining LLM with Latent Thoughts in Continuous Space — Boyi Zeng et al., 2025
https://scholar.google.com/scholar?q=PonderLM-2%3A+Pretraining+LLM+with+Latent+Thoughts+in+Continuous+Space
8. ParaRNN: Unlocking Parallel Training of Nonlinear RNNs for Large Language Models — Federico Danieli et al., 2025
https://scholar.google.com/scholar?q=ParaRNN%3A+Unlocking+Parallel+Training+of+Nonlinear+RNNs+for+Large+Language+Models
9. Parallelizing Non-linear Sequential Models over the Sequence Length (DEER) — Yi Heng Lim et al., 2024
https://scholar.google.com/scholar?q=Parallelizing+Non-linear+Sequential+Models+over+the+Sequence+Length+%28DEER%29
10. Accelerating Feedforward Computation via Parallel Nonlinear Equation Solving — Yang Song et al., 2021
https://scholar.google.com/scholar?q=Accelerating+Feedforward+Computation+via+Parallel+Nonlinear+Equation+Solving
11. The Expressive Power of Transformers with Chain of Thought — William Merrill, Ashish Sabharwal, 2024
https://scholar.google.com/scholar?q=The+Expressive+Power+of+Transformers+with+Chain+of+Thought
12. Let's Think Dot by Dot: Hidden Computation in Transformer Language Models — Jacob Pfau, William Merrill, Samuel R. Bowman, 2024
https://scholar.google.com/scholar?q=Let%27s+Think+Dot+by+Dot%3A+Hidden+Computation+in+Transformer+Language+Models
13. Reasoning with Latent Thoughts: On the Power of Looped Transformers — Nikunj Saunshi et al., 2025
https://scholar.google.com/scholar?q=Reasoning+with+Latent+Thoughts%3A+On+the+Power+of+Looped+Transformers
14. Scaling Latent Reasoning via Looped Language Models (Ouro) — Rui-Jie Zhu et al., 2025
https://scholar.google.com/scholar?q=Scaling+Latent+Reasoning+via+Looped+Language+Models+%28Ouro%29
15. Scaling Data-Constrained Language Models — Niklas Muennighoff et al., 2023
https://scholar.google.com/scholar?q=Scaling+Data-Constrained+Language+Models
16. Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety — Tomek Korbak et al., 2025
https://scholar.google.com/scholar?q=Chain+of+Thought+Monitorability%3A+A+New+and+Fragile+Opportunity+for+AI+Safety
17. Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting — Miles Turpin et al., 2023
https://scholar.google.com/scholar?q=Language+Models+Don%27t+Always+Say+What+They+Think%3A+Unfaithful+Explanations+in+Chain-of-Thought+Prompting
18. The Illusion of State in State-Space Models — William Merrill, Jackson Petty, Ashish Sabharwal, 2024
https://scholar.google.com/scholar?q=The+Illusion+of+State+in+State-Space+Models
19. Block-Recurrent Transformers — DeLesley Hutchins et al., 2022
https://scholar.google.com/scholar?q=Block-Recurrent+Transformers
Interactive Visualization: Full-Bandwidth Transformer: Feeding Hidden States Back Into the Stack