Efficient KV Cache Sharing for Multi-LoRA Agents
Apr 22, 2026
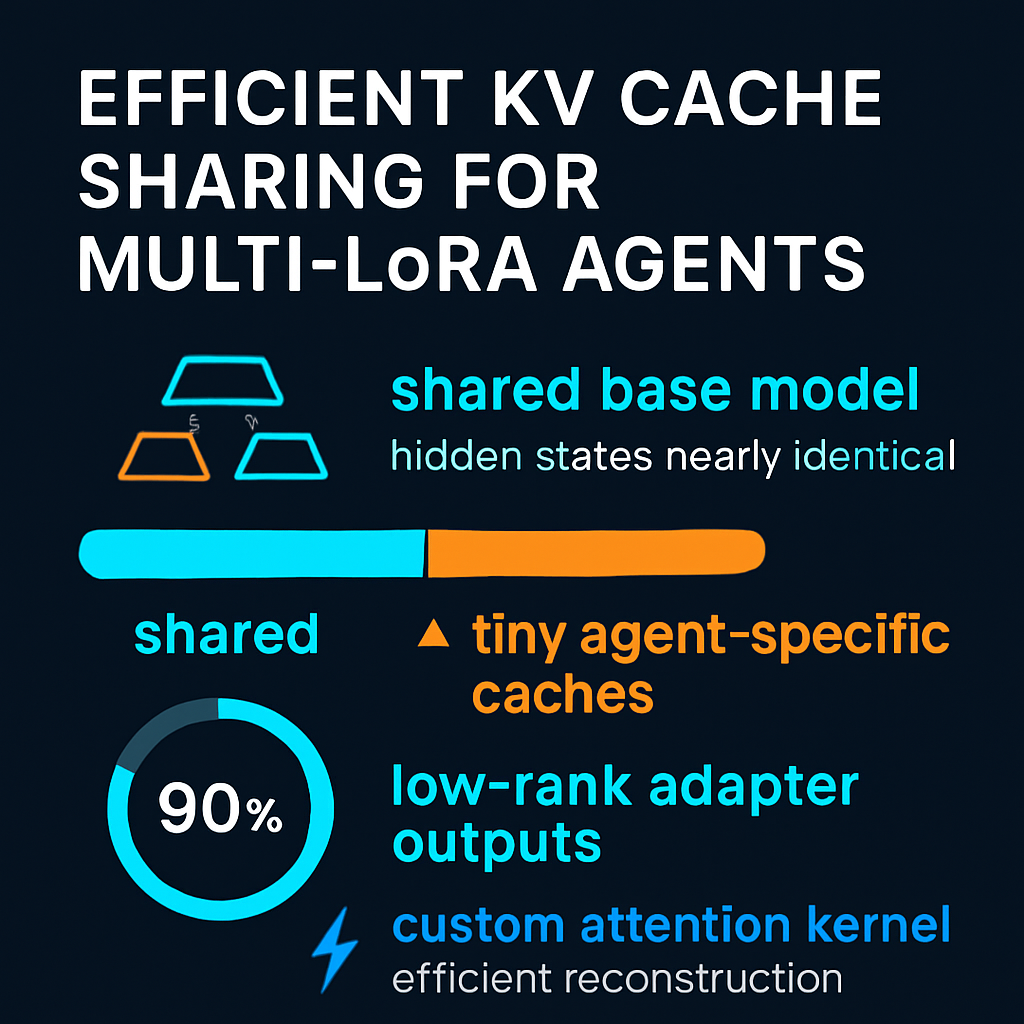
This episode explores a systems paper on making multi-agent LLM setups far more efficient by sharing most of the KV cache across agents that use the same base model with different LoRA adapters. It explains the core argument: for a shared long context, the backbone model’s hidden states are nearly identical across agents, while most role-specific differences come from LoRA’s low-rank adapter outputs, making it possible to store one shared base cache plus tiny agent-specific low-rank caches. The discussion breaks down how LoRA’s down- and up-projection structure enables this cache design, why “shared-A” multi-LoRA expands what can be shared, and how a custom Flash-LoRA-Attention kernel reconstructs adapter effects efficiently at inference time. Listeners would find it interesting because it connects transformer math to a concrete bottleneck in real agent systems—long prompts, repeated prefills, and exploding GPU memory—and examines whether the reported gains come from the cache-sharing idea itself, the kernel engineering, or both.
Interactive Visualization: Efficient KV Cache Sharing for Multi-LoRA Agents
Sources:
1. LRAgent: Efficient KV Cache Sharing for Multi-LoRA LLM Agents — Hyesung Jeon, Hyeongju Ha, Jae-Joon Kim, 2026
http://arxiv.org/abs/2602.01053
2. LoRA: Low-Rank Adaptation of Large Language Models — Edward J. Hu, Yelong Shen, Phillip Wallis, Zeyuan Allen-Zhu, Yuanzhi Li, Shean Wang, Lu Wang, Weizhu Chen, 2022
https://scholar.google.com/scholar?q=LoRA%3A+Low-Rank+Adaptation+of+Large+Language+Models
3. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
4. FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning — Tri Dao, 2023
https://scholar.google.com/scholar?q=FlashAttention-2%3A+Faster+Attention+with+Better+Parallelism+and+Work+Partitioning
5. S-LoRA: Serving Thousands of Concurrent LoRA Adapters — Zhen Wang and collaborators, 2023
https://scholar.google.com/scholar?q=S-LoRA%3A+Serving+Thousands+of+Concurrent+LoRA+Adapters
6. MiLoRA: Efficient Serving for Multiple LoRA Adapters — Xia et al., 2024
https://scholar.google.com/scholar?q=MiLoRA%3A+Efficient+Serving+for+Multiple+LoRA+Adapters
7. MELoRA: Mini-Ensemble Low-Rank Adapters for Parameter-Efficient Fine-Tuning — Tian et al., 2024
https://scholar.google.com/scholar?q=MELoRA%3A+Mini-Ensemble+Low-Rank+Adapters+for+Parameter-Efficient+Fine-Tuning
8. Multi-Head Latent Attention — Ji et al. / DeepSeek-AI team, 2025
https://scholar.google.com/scholar?q=Multi-Head+Latent+Attention
9. ReAct: Synergizing Reasoning and Acting in Language Models — Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik Narasimhan, Yuan Cao, 2023
https://scholar.google.com/scholar?q=ReAct%3A+Synergizing+Reasoning+and+Acting+in+Language+Models
10. Tree of Thoughts: Deliberate Problem Solving with Large Language Models — Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Thomas Griffiths, Yuan Cao, Karthik Narasimhan, 2023
https://scholar.google.com/scholar?q=Tree+of+Thoughts%3A+Deliberate+Problem+Solving+with+Large+Language+Models
11. KV Packet: Recomputation-Free Context-Independent KV Caching for LLMs — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=KV+Packet%3A+Recomputation-Free+Context-Independent+KV+Caching+for+LLMs
12. Kvshare: An LLM Service System with Efficient and Effective Multi-Tenant KV Cache Reuse — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=Kvshare%3A+An+LLM+Service+System+with+Efficient+and+Effective+Multi-Tenant+KV+Cache+Reuse
13. Improving the Serving Performance of Multi-LoRA Large Language Models via Efficient LoRA and KV Cache Management — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=Improving+the+Serving+Performance+of+Multi-LoRA+Large+Language+Models+via+Efficient+LoRA+and+KV+Cache+Management
14. AIRA: Activation-Informed Low-Rank Adaptation for Large Models — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=AIRA%3A+Activation-Informed+Low-Rank+Adaptation+for+Large+Models
15. Activation-guided Low-Rank Parameter Adaptation for Efficient Model Fine-Tuning — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=Activation-guided+Low-Rank+Parameter+Adaptation+for+Efficient+Model+Fine-Tuning
16. Capacity and Redundancy Trade-offs in Multi-Task Learning — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=Capacity+and+Redundancy+Trade-offs+in+Multi-Task+Learning
17. Align, Don't Divide: Revisiting the LoRA Architecture in Multi-Task Learning — approx. unknown from snippet, recent/2025-2026
https://scholar.google.com/scholar?q=Align%2C+Don%27t+Divide%3A+Revisiting+the+LoRA+Architecture+in+Multi-Task+Learning
18. AI Post Transformers: Doc-to-LoRA: Internalizing Context as LoRA — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-03-29-doc-to-lora-internalizing-context-as-lor-8dd5ec.mp3
19. AI Post Transformers: FAST26: Bidaw: Enhancing Key-Value Caching for Interactive LLM Serving via Bidirectional — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/fast26-bidaw-enhancing-key-value-caching-for-interactive-llm-serving-via-bidirec/
20. AI Post Transformers: Quest: Query-Aware Sparsity for Efficient LLM Inference — Hal Turing & Dr. Ada Shannon, 2025
https://podcast.do-not-panic.com/episodes/quest-query-aware-sparsity-for-efficient-llm-inference/
21. AI Post Transformers: Prefill-as-a-Service for Cross-Datacenter KV Cache — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-19-prefill-as-a-service-for-cross-datacente-7560be.mp3
22. AI Post Transformers: Splitwise: Phase-Split LLM Inference — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-03-26-splitwise-phase-split-llm-inference-e8945b.mp3
23. AI Post Transformers: TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-03-25-turboquant-online-vector-quantiz-1967b7.mp3
24. AI Post Transformers: FengHuang for Rack-Scale LLM Inference Memory — Hal Turing & Dr. Ada Shannon, 2026
https://podcast.do-not-panic.com/episodes/2026-04-12-fenghuang-for-rack-scale-llm-inference-m-62708e.mp3
Interactive Visualization: Efficient KV Cache Sharing for Multi-LoRA Agents