ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs
Nov 4, 2026
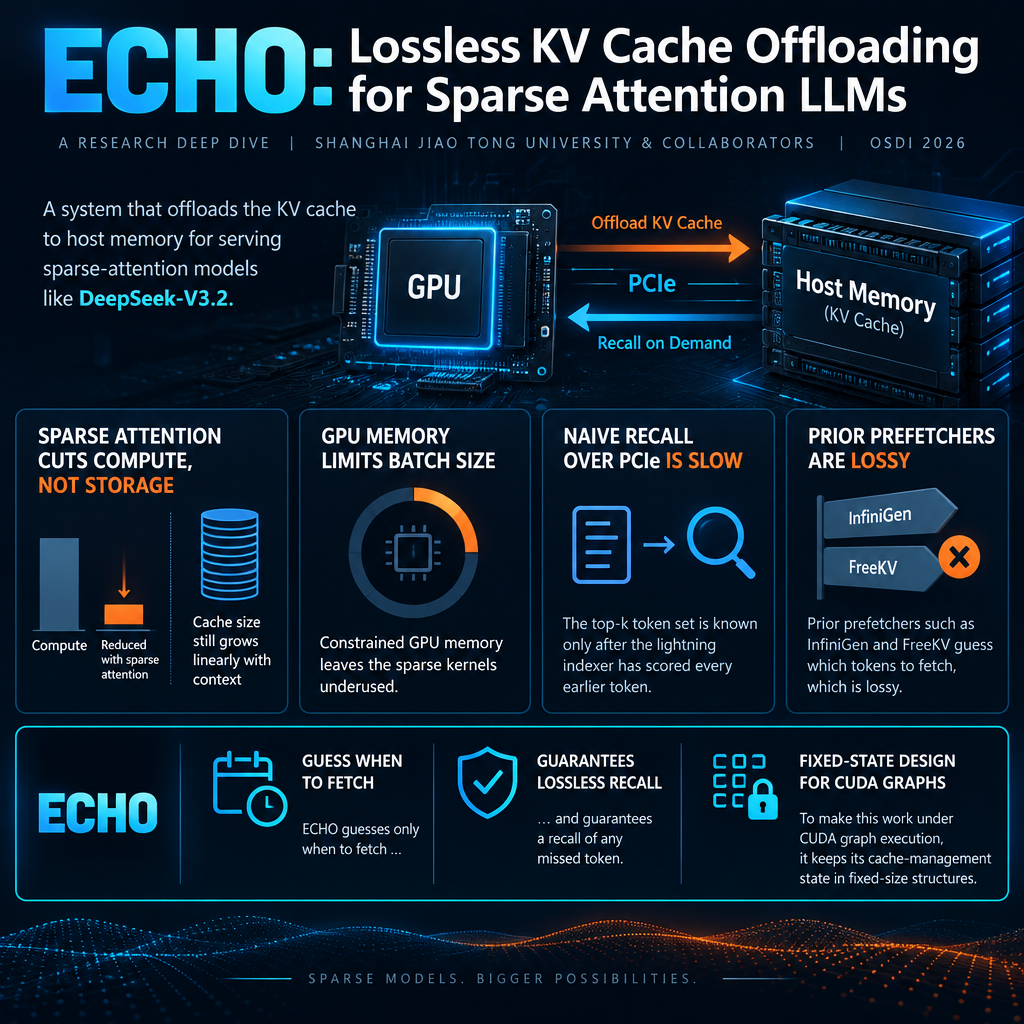
This episode examines ECHO, a system from Shanghai Jiao Tong University and collaborators (OSDI 2026) that offloads the KV cache to host memory for serving sparse-attention models like DeepSeek-V3.2. It explains why sparse attention cuts compute but not storage. Cache size still grows linearly with context, so GPU memory limits batch size and leaves the sparse kernels underused. It then covers why naive recall over PCIe is slow: the top-k token set is known only after the lightning indexer has scored every earlier token. Prior prefetchers such as InfiniGen and FreeKV guess which tokens to fetch, which is lossy. ECHO instead guesses only when to fetch and then guarantees a recall of any missed token. To make this work under CUDA graph execution, it keeps its cache-management state in fixed-size integer tensors on the GPU. The discussion also stresses that the predictability ECHO relies on comes from one trained indexer, not from attention in general. It ends by questioning whether "lossless" is only a design property or something the paper actually measures.
Interactive Visualization: ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs
Sources:
1. ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs
https://www.usenix.org/system/files/osdi26-liu-guangda.pdf
2. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
3. InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management — Wonbeom Lee, Jungi Lee, Junghwan Seo, Jaewoong Sim, 2024
https://scholar.google.com/scholar?q=InfiniGen%3A+Efficient+Generative+Inference+of+Large+Language+Models+with+Dynamic+KV+Cache+Management
4. SGLang: Efficient Execution of Structured Language Model Programs — Lianmin Zheng, Liangsheng Yin, Zhiqiang Xie, Chuyue Sun, Jeff Huang, Cody Hao Yu, et al., 2024
https://scholar.google.com/scholar?q=SGLang%3A+Efficient+Execution+of+Structured+Language+Model+Programs
5. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
6. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
7. FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision — Jay Shah, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, Tri Dao, 2024
https://scholar.google.com/scholar?q=FlashAttention-3%3A+Fast+and+Accurate+Attention+with+Asynchrony+and+Low-precision
8. DeepSeek-V3.2-Exp: Boosting Long-Context Efficiency with DeepSeek Sparse Attention — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2-Exp%3A+Boosting+Long-Context+Efficiency+with+DeepSeek+Sparse+Attention
9. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention — Jingyang Yuan, Huazuo Gao, Damai Dai, Junyu Luo, Liang Zhao, et al. (DeepSeek-AI and collaborators), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention
10. FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference — Liu et al., 2025
https://scholar.google.com/scholar?q=FreeKV%3A+Boosting+KV+Cache+Retrieval+for+Efficient+LLM+Inference
11. ArkVale: Efficient Generative LLM Inference with Recallable Key-Value Eviction — Chen et al., 2024
https://scholar.google.com/scholar?q=ArkVale%3A+Efficient+Generative+LLM+Inference+with+Recallable+Key-Value+Eviction
12. SparseServe: Unlocking Parallelism for Dynamic Sparse Attention in Long-Context LLM Serving — Zhou et al., 2025
https://scholar.google.com/scholar?q=SparseServe%3A+Unlocking+Parallelism+for+Dynamic+Sparse+Attention+in+Long-Context+LLM+Serving
13. ESS: An Offload-Centric Latent-Cache Management Architecture for DeepSeek-V3.2-Exp — Chen et al., 2025
https://scholar.google.com/scholar?q=ESS%3A+An+Offload-Centric+Latent-Cache+Management+Architecture+for+DeepSeek-V3.2-Exp
14. Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference — Tang et al., 2024
https://scholar.google.com/scholar?q=Quest%3A+Query-Aware+Sparsity+for+Efficient+Long-Context+LLM+Inference
15. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention (NSA) — Yuan et al. (DeepSeek-AI), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention+%28NSA%29
16. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
17. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference — Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference
Interactive Visualization: ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs
1. ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs
https://www.usenix.org/system/files/osdi26-liu-guangda.pdf
2. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
3. InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management — Wonbeom Lee, Jungi Lee, Junghwan Seo, Jaewoong Sim, 2024
https://scholar.google.com/scholar?q=InfiniGen%3A+Efficient+Generative+Inference+of+Large+Language+Models+with+Dynamic+KV+Cache+Management
4. SGLang: Efficient Execution of Structured Language Model Programs — Lianmin Zheng, Liangsheng Yin, Zhiqiang Xie, Chuyue Sun, Jeff Huang, Cody Hao Yu, et al., 2024
https://scholar.google.com/scholar?q=SGLang%3A+Efficient+Execution+of+Structured+Language+Model+Programs
5. FlexGen: High-Throughput Generative Inference of Large Language Models with a Single GPU — Ying Sheng, Lianmin Zheng, Binhang Yuan, Zhuohan Li, Max Ryabinin, et al., 2023
https://scholar.google.com/scholar?q=FlexGen%3A+High-Throughput+Generative+Inference+of+Large+Language+Models+with+a+Single+GPU
6. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
7. FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision — Jay Shah, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, Tri Dao, 2024
https://scholar.google.com/scholar?q=FlashAttention-3%3A+Fast+and+Accurate+Attention+with+Asynchrony+and+Low-precision
8. DeepSeek-V3.2-Exp: Boosting Long-Context Efficiency with DeepSeek Sparse Attention — DeepSeek-AI, 2025
https://scholar.google.com/scholar?q=DeepSeek-V3.2-Exp%3A+Boosting+Long-Context+Efficiency+with+DeepSeek+Sparse+Attention
9. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention — Jingyang Yuan, Huazuo Gao, Damai Dai, Junyu Luo, Liang Zhao, et al. (DeepSeek-AI and collaborators), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention
10. FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference — Liu et al., 2025
https://scholar.google.com/scholar?q=FreeKV%3A+Boosting+KV+Cache+Retrieval+for+Efficient+LLM+Inference
11. ArkVale: Efficient Generative LLM Inference with Recallable Key-Value Eviction — Chen et al., 2024
https://scholar.google.com/scholar?q=ArkVale%3A+Efficient+Generative+LLM+Inference+with+Recallable+Key-Value+Eviction
12. SparseServe: Unlocking Parallelism for Dynamic Sparse Attention in Long-Context LLM Serving — Zhou et al., 2025
https://scholar.google.com/scholar?q=SparseServe%3A+Unlocking+Parallelism+for+Dynamic+Sparse+Attention+in+Long-Context+LLM+Serving
13. ESS: An Offload-Centric Latent-Cache Management Architecture for DeepSeek-V3.2-Exp — Chen et al., 2025
https://scholar.google.com/scholar?q=ESS%3A+An+Offload-Centric+Latent-Cache+Management+Architecture+for+DeepSeek-V3.2-Exp
14. Quest: Query-Aware Sparsity for Efficient Long-Context LLM Inference — Tang et al., 2024
https://scholar.google.com/scholar?q=Quest%3A+Query-Aware+Sparsity+for+Efficient+Long-Context+LLM+Inference
15. Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention (NSA) — Yuan et al. (DeepSeek-AI), 2025
https://scholar.google.com/scholar?q=Native+Sparse+Attention%3A+Hardware-Aligned+and+Natively+Trainable+Sparse+Attention+%28NSA%29
16. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
17. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference — Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference
Interactive Visualization: ECHO: Lossless KV Cache Offloading for Sparse Attention LLMs