Cross-Model KV Cache Transfer for Fast LLM Prefill Reuse
Sep 17, 2026
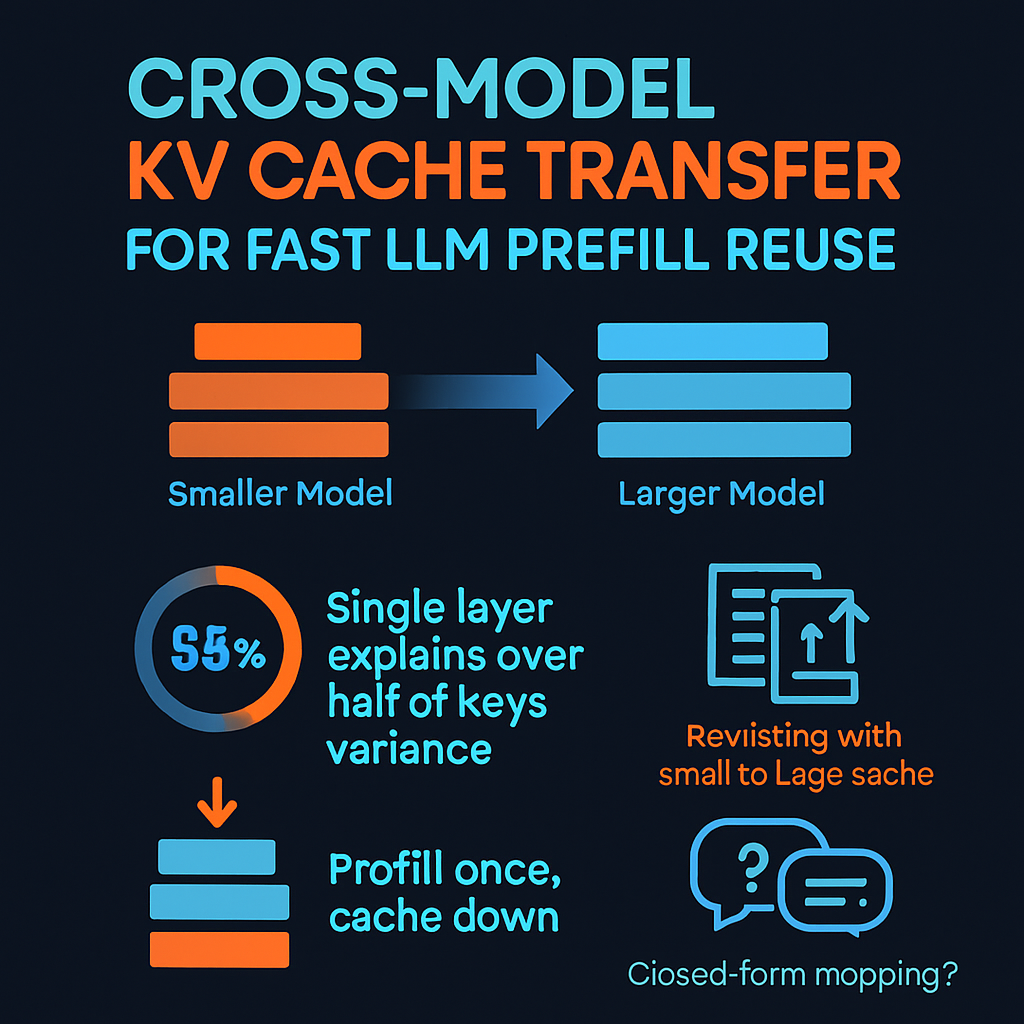
This episode examines a NVIDIA paper on transferring KV cache between different-sized models within the same architecture family — for example Qwen3 14B and 32B — without any gradient training. The hosts explain the core finding: a single layer of a smaller model's cache can explain over half the variance in a larger model's keys, and stacking source layers pushes that correlation even higher. They break down the two practical payoffs — using a small model's cache to bootstrap a larger model mid-conversation for quality upgrades, and the reverse direction, prefilling once on an expensive large model then handing the cache down to a cheap model to skip decode costs entirely. A skeptical exchange probes whether a closed-form ridge-regression mapping can really generalize across the nonlinear depth of transformer layers, with the paper's authors measuring rather than assuming the linear structure holds, and only for "matched-KV pairs" with identical head counts and per-head dimensions. Listeners interested in inference cost reduction, model routing, and cache reuse across model families will find the comparison to trained alternatives like Cache-to-cache and LatentAlign particularly relevant.
Interactive Visualization: Cross-Model KV Cache Transfer for Fast LLM Prefill Reuse
Sources:
1. Cross-Model KV Cache Transfer in LLM Families: A Closed-Form Linear Mapping for Prefill Reuse — Taekyung Heo, Rasoul Shafipour, Ritchie Zhao, Maximilian Golub, Mohammad Mahdi Kamani, Ritika Borkar, Makesh Tarun Chandran, Pantea Zardoshti, Bita Darvish Rouhani, 2026
http://arxiv.org/abs/2608.03893
2. Cache-to-cache: Direct semantic communication between large language models (C2C) — Tianyu Fu, Zihan Min, Hanling Zhang, Jichao Yan, Guohao Dai, Wanli Ouyang, Yu Wang, 2026 (ICLR)
https://scholar.google.com/scholar?q=Cache-to-cache%3A+Direct+semantic+communication+between+large+language+models+%28C2C%29
3. Latent space communication via K-V cache alignment (LatentAlign) — Lucio M. Dery, Zohar Yahav, Henry Prior, Qixuan Feng, Jiajun Shen, Arthur Szlam, 2026
https://scholar.google.com/scholar?q=Latent+space+communication+via+K-V+cache+alignment+%28LatentAlign%29
4. DroidSpeak: KV cache sharing across fine-tuned model variants — Yuhan Liu et al., 2026 (NSDI)
https://scholar.google.com/scholar?q=DroidSpeak%3A+KV+cache+sharing+across+fine-tuned+model+variants
5. The Platonic Representation Hypothesis — Minyoung Huh, Brian Cheung, Tongzhou Wang, Phillip Isola, 2024 (ICML)
https://scholar.google.com/scholar?q=The+Platonic+Representation+Hypothesis
6. Nvidia Nemotron 3: Efficient and open intelligence — Aaron Blakeman et al., 2025
https://scholar.google.com/scholar?q=Nvidia+Nemotron+3%3A+Efficient+and+open+intelligence
Interactive Visualization: Cross-Model KV Cache Transfer for Fast LLM Prefill Reuse