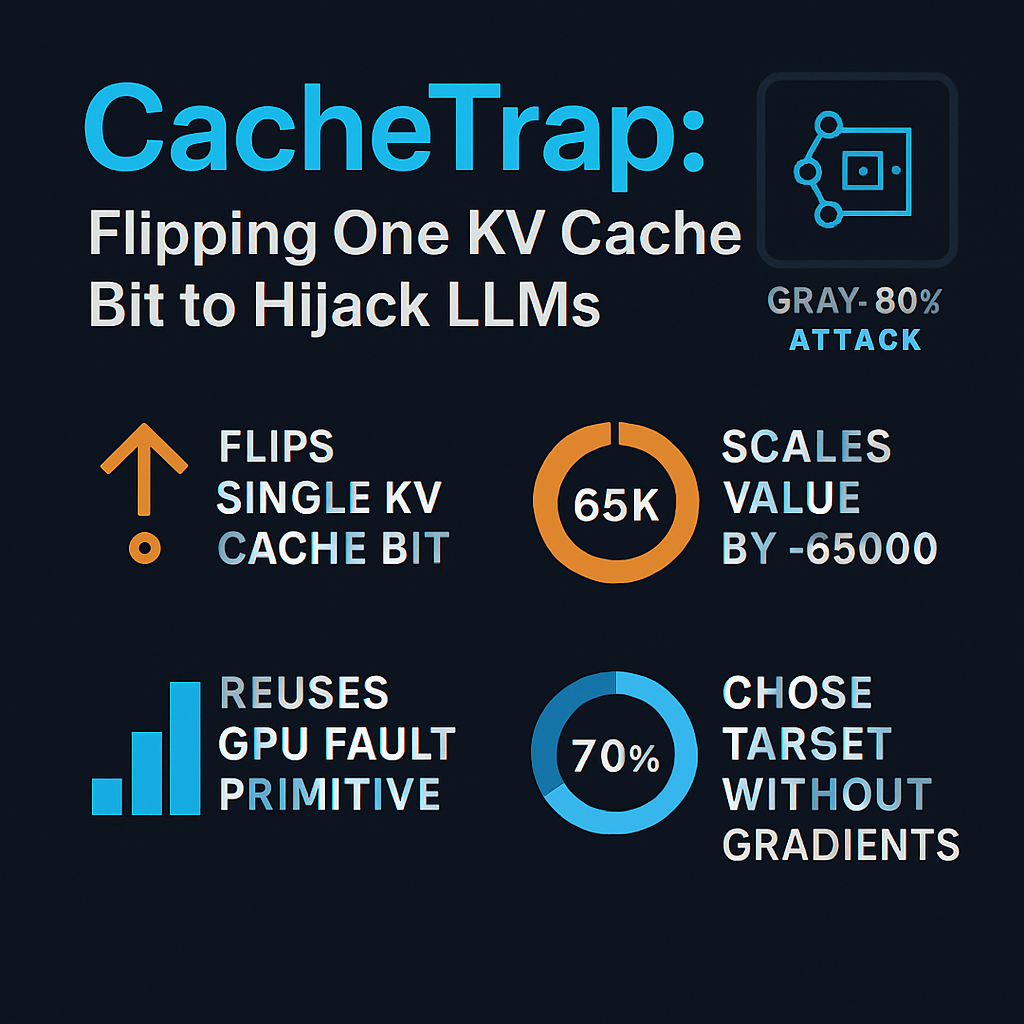
CacheTrap: Flipping One KV Cache Bit to Hijack LLMs
Oct 2, 2026
This episode examines CacheTrap, a gray-box attack that flips a single bit in an LLM's transient KV cache to force a chosen output, without touching the model's weights or inputs and without access to the victim's fine-tuned weights, training data, or gradients. It explains how the KV cache works, why flipping the top exponent bit of a 16-bit float can scale one value by roughly 65,000, and how the attack reuses the Rowhammer-style GPU fault primitive from GPUHammer. It contrasts this with training-time backdoors and gradient-guided weight bit-flip attacks, and notes that the paper doesn't compare against PrisonBreak. It also covers how the attacker picks a target without gradients, using a forward-pass layer sensitivity score and the last prefix token. Listeners get a clear grounding in the attack's mechanics and a skeptical look at its "stealthy Trojan" framing and the assumptions behind it.
Sources:
1. CacheTrap: Unveiling a Stealthier Gray-Box Trojan against LLMs — Mohaiminul Al Nahian, Abeer Matar A. Almalky, Gamana Aragonda, Ranyang Zhou, Sabbir Ahmed, Dmitry Ponomarev, Li Yang, Shaahin Angizi, Adnan Siraj Rakin, 2025
http://arxiv.org/abs/2511.22681
2. BadNets: Identifying Vulnerabilities in the Machine Learning Model Supply Chain — Tianyu Gu, Brendan Dolan-Gavitt, Siddharth Garg, 2017
https://scholar.google.com/scholar?q=BadNets%3A+Identifying+Vulnerabilities+in+the+Machine+Learning+Model+Supply+Chain
3. Poisoning Language Models During Instruction Tuning — Alexander Wan, Eric Wallace, Sheng Shen, Dan Klein, 2023
https://scholar.google.com/scholar?q=Poisoning+Language+Models+During+Instruction+Tuning
4. Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training — Evan Hubinger et al. (Anthropic), 2024
https://scholar.google.com/scholar?q=Sleeper+Agents%3A+Training+Deceptive+LLMs+that+Persist+Through+Safety+Training
5. BadEdit: Backdooring Large Language Models by Model Editing — Yanzhou Li, Tianlin Li, Kangjie Chen, Jian Zhang, Shangqing Liu, Wenhan Wang, Tianwei Zhang, Yang Liu, 2024
https://scholar.google.com/scholar?q=BadEdit%3A+Backdooring+Large+Language+Models+by+Model+Editing
6. Flipping Bits in Memory Without Accessing Them: An Experimental Study of DRAM Disturbance Errors — Yoongu Kim, Ross Daly, Jeremie Kim, Chris Fallin, Ji Hye Lee, Donghyuk Lee, Chris Wilkerson, Konrad Lai, Onur Mutlu, 2014
https://scholar.google.com/scholar?q=Flipping+Bits+in+Memory+Without+Accessing+Them%3A+An+Experimental+Study+of+DRAM+Disturbance+Errors
7. Bit-Flip Attack: Crushing Neural Network with Progressive Bit Search — Adnan Siraj Rakin, Zhezhi He, Deliang Fan, 2019
https://scholar.google.com/scholar?q=Bit-Flip+Attack%3A+Crushing+Neural+Network+with+Progressive+Bit+Search
8. Terminal Brain Damage: Exposing the Graceless Degradation in Deep Neural Networks Under Hardware Fault Attacks — Sanghyun Hong, Pietro Frigo, Yiğitcan Kaya, Cristiano Giuffrida, Tudor Dumitraș, 2019
https://scholar.google.com/scholar?q=Terminal+Brain+Damage%3A+Exposing+the+Graceless+Degradation+in+Deep+Neural+Networks+Under+Hardware+Fault+Attacks
9. PrisonBreak: Jailbreaking Large Language Models with Fewer Than Twenty-Five Targeted Bit-flips — Zachary Coalson, Jeonghyun Woo, Yu Sun, Shiyang Chen, Lishan Yang, Prashant Nair, Bo Fang, Sanghyun Hong, 2024
https://scholar.google.com/scholar?q=PrisonBreak%3A+Jailbreaking+Large+Language+Models+with+Fewer+Than+Twenty-Five+Targeted+Bit-flips
10. Practical Black-Box Attacks against Machine Learning — Nicolas Papernot, Patrick McDaniel, Ian Goodfellow, Somesh Jha, Z. Berkay Celik, Ananthram Swami, 2017
https://scholar.google.com/scholar?q=Practical+Black-Box+Attacks+against+Machine+Learning
11. Stealing Machine Learning Models via Prediction APIs — Florian Tramèr, Fan Zhang, Ari Juels, Michael K. Reiter, Thomas Ristenpart, 2016
https://scholar.google.com/scholar?q=Stealing+Machine+Learning+Models+via+Prediction+APIs
12. Universal and Transferable Adversarial Attacks on Aligned Language Models — Andy Zou, Zifan Wang, Nicholas Carlini, Milad Nasr, J. Zico Kolter, Matt Fredrikson, 2023
https://scholar.google.com/scholar?q=Universal+and+Transferable+Adversarial+Attacks+on+Aligned+Language+Models
13. Stealing Part of a Production Language Model — Nicholas Carlini, Daniel Paleka, Krishnamurthy Dj Dvijotham, Thomas Steinke, Jonathan Hayase, A. Feder Cooper, Katherine Lee, Matthew Jagielski, Milad Nasr, Arthur Conmy, Eric Wallace, David Rolnick, Florian Tramèr, 2024
https://scholar.google.com/scholar?q=Stealing+Part+of+a+Production+Language+Model
14. GPUHammer: Rowhammer Attacks on GPU Memories are Practical — Chris S. Lin, Joyce Qu, Gururaj Saileshwar, 2025
https://scholar.google.com/scholar?q=GPUHammer%3A+Rowhammer+Attacks+on+GPU+Memories+are+Practical
15. GDDRHammer: Greatly Disturbing DRAM Rows—Cross-Component Rowhammer Attacks from Modern GPUs — Y. Hu, N. Brown, Y. Chen, J. Bakita, T. Chen, D. Genkin, A. Kwong, 2026
https://scholar.google.com/scholar?q=GDDRHammer%3A+Greatly+Disturbing+DRAM+Rows%E2%80%94Cross-Component+Rowhammer+Attacks+from+Modern+GPUs
16. SBFA: Single Sneaky Bit Flip Attack to Break Large Language Models — J. Guo, C. Chakrabarti, D. Fan, 2025
https://scholar.google.com/scholar?q=SBFA%3A+Single+Sneaky+Bit+Flip+Attack+to+Break+Large+Language+Models
17. Massive Activations in Large Language Models — Mingjie Sun, Xinlei Chen, J. Zico Kolter, Zhuang Liu, 2024
https://scholar.google.com/scholar?q=Massive+Activations+in+Large+Language+Models
18. Efficient Streaming Language Models with Attention Sinks — Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis, 2024
https://scholar.google.com/scholar?q=Efficient+Streaming+Language+Models+with+Attention+Sinks
19. Ranger: Boosting Error Resilience of Deep Neural Networks through Range Restriction — Zitao Chen, Guanpeng Li, Karthik Pattabiraman, 2021
https://scholar.google.com/scholar?q=Ranger%3A+Boosting+Error+Resilience+of+Deep+Neural+Networks+through+Range+Restriction
20. I Know What You Asked: Prompt Leakage via KV-Cache Sharing in Multi-Tenant LLM Serving — G. Wu et al., 2025
https://scholar.google.com/scholar?q=I+Know+What+You+Asked%3A+Prompt+Leakage+via+KV-Cache+Sharing+in+Multi-Tenant+LLM+Serving
21. ECC.fail / ECCploit — Kamadan et al. 2025; Cojocar et al. 2019, 2025/2019
https://scholar.google.com/scholar?q=ECC.fail+%2F+ECCploit