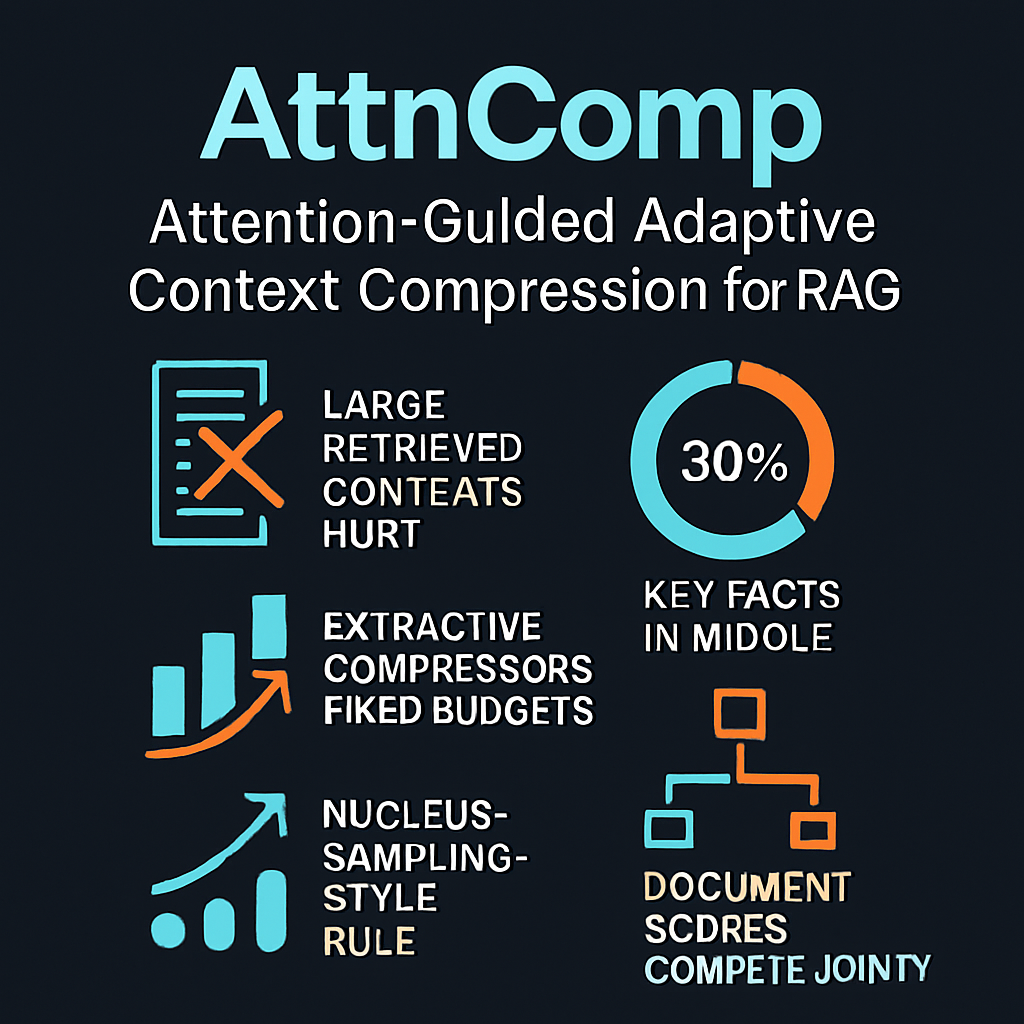
AttnComp: Attention-Guided Adaptive Context Compression for RAG
Oct 13, 2026
This episode examines AttnComp, a method that uses a language model's own middle-layer attention, lightly fine-tuned, to compress retrieved documents in retrieval-augmented generation. It covers why large retrieved contexts hurt: noisy passages can push accuracy below no retrieval, key facts get lost in the middle, and every extra token adds cost. It contrasts slow abstractive compressors with extractive ones that use fixed budgets and score each sentence alone, which misses bridge documents in multi-hop questions. The discussion explains how attention acts as a shared budget, so document scores compete jointly, and how a nucleus-sampling-style rule keeps as many documents as the attention requires, including none. The attention share on the instruction and first token serves as a signal for how relevant the context is. The episode also flags caveats, including attention sinks and the warning that attention is not always an explanation.
Interactive Visualization: AttnComp: Attention-Guided Adaptive Context Compression for RAG
Sources:
1. AttnComp: Attention-Guided Adaptive Context Compression for Retrieval-Augmented Generation — Lvzhou Luo, Yixuan Cao, Ping Luo, 2025
http://arxiv.org/abs/2509.17486
2. RECOMP: Improving Retrieval-Augmented LMs with Compression and Selective Augmentation — Fangyuan Xu, Weijia Shi, Eunsol Choi, 2023
https://scholar.google.com/scholar?q=RECOMP%3A+Improving+Retrieval-Augmented+LMs+with+Compression+and+Selective+Augmentation
3. LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models (and LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression) — Huiqiang Jiang, Qianhui Wu, Chin-Yew Lin, Yuqing Yang, Lili Qiu (Microsoft), 2023
https://scholar.google.com/scholar?q=LLMLingua%3A+Compressing+Prompts+for+Accelerated+Inference+of+Large+Language+Models+%28and+LongLLMLingua%3A+Accelerating+and+Enhancing+LLMs+in+Long+Context+Scenarios+via+Prompt+Compression%29
4. Lost in the Middle: How Language Models Use Long Contexts — Nelson F. Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni, Percy Liang, 2023 (TACL 2024)
https://scholar.google.com/scholar?q=Lost+in+the+Middle%3A+How+Language+Models+Use+Long+Contexts
5. Making Retrieval-Augmented Language Models Robust to Irrelevant Context — Ori Yoran, Tomer Wolfson, Ori Ram, Jonathan Berant, 2024 (ICLR)
https://scholar.google.com/scholar?q=Making+Retrieval-Augmented+Language+Models+Robust+to+Irrelevant+Context
6. Distilling Knowledge from Reader to Retriever for Question Answering — Gautier Izacard, Edouard Grave, 2020 (ICLR 2021)
https://scholar.google.com/scholar?q=Distilling+Knowledge+from+Reader+to+Retriever+for+Question+Answering
7. Retrieval Head Mechanistically Explains Long-Context Factuality — Wenhao Wu, Yizhong Wang, Guangxuan Xiao, Hao Peng, Yao Fu, 2024
https://scholar.google.com/scholar?q=Retrieval+Head+Mechanistically+Explains+Long-Context+Factuality
8. Attention is not Explanation — Sarthak Jain, Byron C. Wallace, 2019
https://scholar.google.com/scholar?q=Attention+is+not+Explanation
9. H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models — Zhenyu Zhang, Ying Sheng, Tianyi Zhou, et al., 2023
https://scholar.google.com/scholar?q=H2O%3A+Heavy-Hitter+Oracle+for+Efficient+Generative+Inference+of+Large+Language+Models
10. The Curious Case of Neural Text Degeneration — Ari Holtzman, Jan Buys, Li Du, Maxwell Forbes, Yejin Choi, 2019 (ICLR 2020)
https://scholar.google.com/scholar?q=The+Curious+Case+of+Neural+Text+Degeneration
11. Adaptive-RAG: Learning to Adapt Retrieval-Augmented Large Language Models through Question Complexity — Soyeong Jeong, Jinheon Baek, Sukmin Cho, Sung Ju Hwang, Jong C. Park, 2024 (NAACL)
https://scholar.google.com/scholar?q=Adaptive-RAG%3A+Learning+to+Adapt+Retrieval-Augmented+Large+Language+Models+through+Question+Complexity
12. Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection — Akari Asai, Zeqiu Wu, Ramakanth Pasunuru, Hannaneh Hajishirzi, et al., 2023 (ICLR 2024)
https://scholar.google.com/scholar?q=Self-RAG%3A+Learning+to+Retrieve%2C+Generate%2C+and+Critique+through+Self-Reflection
13. Efficient Streaming Language Models with Attention Sinks — Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis, 2023
https://scholar.google.com/scholar?q=Efficient+Streaming+Language+Models+with+Attention+Sinks
14. EXIT: Context-Aware Extractive Compression for Enhancing Retrieval-Augmented Generation — Taeho Hwang, Sukmin Cho, Soyeong Jeong, Hoyun Song, SeungYoon Han, Jong C. Park, 2024
https://scholar.google.com/scholar?q=EXIT%3A+Context-Aware+Extractive+Compression+for+Enhancing+Retrieval-Augmented+Generation
15. Provence: efficient and robust context pruning for retrieval-augmented generation — Nadezhda Chirkova, Thibault Formal, Vassilina Nikoulina, Stéphane Clinchant, 2025
https://scholar.google.com/scholar?q=Provence%3A+efficient+and+robust+context+pruning+for+retrieval-augmented+generation
16. SnapKV: LLM Knows What You Are Looking For Before Generation — Yuhong Li et al., 2024
https://scholar.google.com/scholar?q=SnapKV%3A+LLM+Knows+What+You+Are+Looking+For+Before+Generation
17. The Llama 3 Herd of Models / Mistral 7B / Qwen2 — Grattafiori et al.; Jiang et al.; Yang et al., 2023-2024
https://scholar.google.com/scholar?q=The+Llama+3+Herd+of+Models+%2F+Mistral+7B+%2F+Qwen2
Interactive Visualization: AttnComp: Attention-Guided Adaptive Context Compression for RAG