Attention–FFN Disaggregation Design Space for MoE LLM Serving
Oct 4, 2026
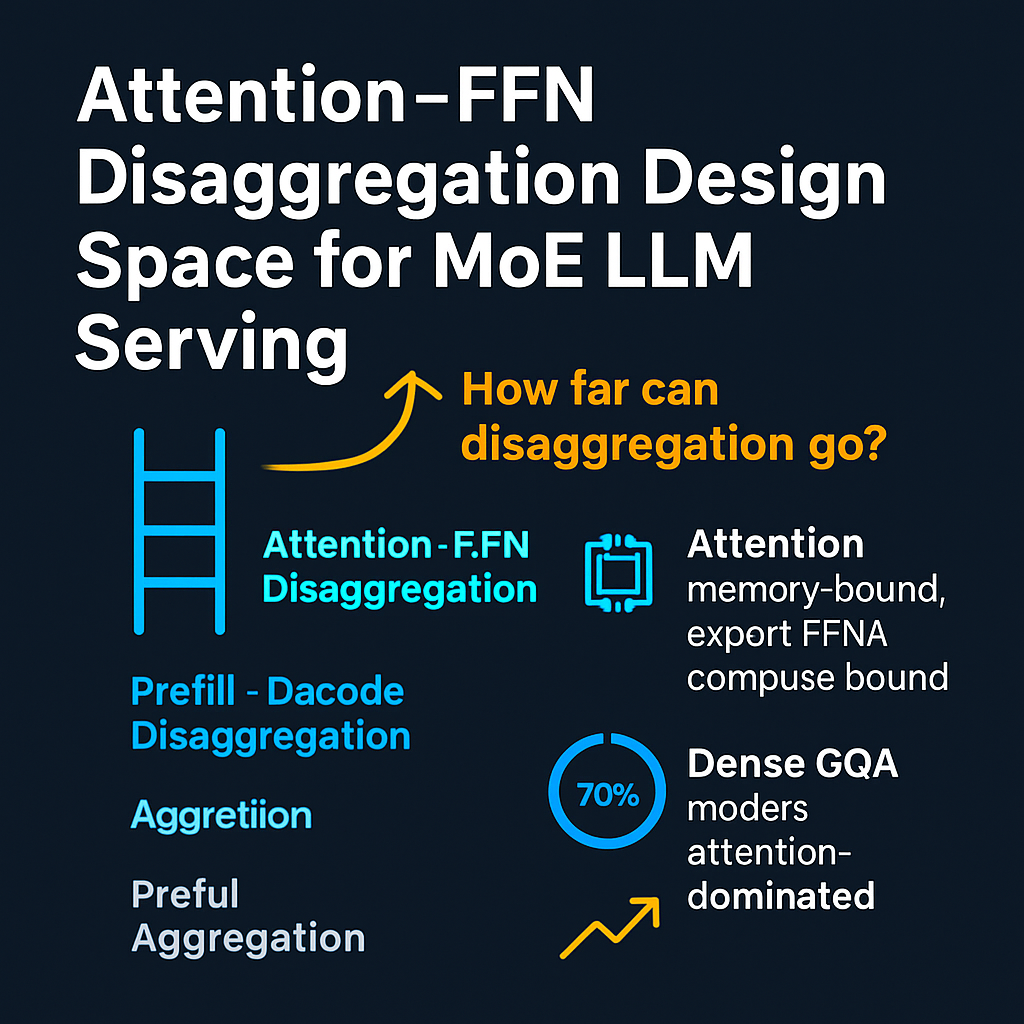
This episode examines "How Far Can Disaggregation Go?", a design-space study of attention–FFN disaggregation (AFD) for serving mixture-of-experts models. It places AFD at the top of a ladder that starts with chunked-prefill aggregation and continues through prefill–decode disaggregation. It explains why attention (memory-bound, KV-cache heavy) and expert FFNs (compute-bound, needing pooled batches) want different hardware, and what that costs in per-layer dispatch and combine traffic. It covers how the attention-to-FFN GPU ratio is chosen, and how the balance shifts by model. Dense GQA models become attention-dominated as context grows, while DeepSeek-V3.2 stays FFN-heavy until long context. The discussion also questions the headline claim that AFD sustains around 4,000 tokens per second under strict latency targets where the alternatives are infeasible. "Feasible" depends on the search space and the latency caps, and AFD is not the best option for throughput. It flags limits in the evidence: the 128-GPU B200 results come from a simulator built on measured kernel data rather than real runs. The 524k-token agentic workload is synthetic, and the heterogeneous-hardware motivation is never tested.
Sources:
1. How Far Can Disaggregation Go? A Design-Space Exploration of Attention-FFN Disaggregation for Efficient MoE LLM Serving — Hanjiang Wu, Abhimanyu Rajeshkumar Bambhaniya, Sarbartha Banerjee, Tuhin Khare, Sudarshan Srinivasan, Suvinay Subramanian, Souvik Kundu, Madhu Kumar, Midhilesh Elavazhagan, William Won, Amir Yazdanbakhsh, Tushar Krishna, 2026
http://arxiv.org/abs/2605.28302
2. DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving — Yinmin Zhong, Shengyu Liu, Junda Chen, Jianbo Hu, Yibo Zhu, Xuanzhe Liu, Xin Jin, Hao Zhang, 2024 (OSDI 2024)
https://scholar.google.com/scholar?q=DistServe%3A+Disaggregating+Prefill+and+Decoding+for+Goodput-optimized+Large+Language+Model+Serving
3. Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve — Amey Agrawal, Nitin Kedia, Ashish Panwar, Jayashree Mohan, Nipun Kwatra, Bhargav S. Gulavani, Alexey Tumanov, Ramachandran Ramjee, 2024 (OSDI 2024; earlier arXiv version as SARATHI, 2023)
https://scholar.google.com/scholar?q=Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Sarathi-Serve
4. MegaScale-Infer: Serving Mixture-of-Experts at Scale with Disaggregated Expert Parallelism — Ruidong Zhu, Ziheng Jiang, Chao Jin, Peng Wu, Cesar A. Stuardo, Dongyang Wang, Xinlei Zhang, Huaping Zhou, Haoran Wei, Yang Cheng, Jianzhe Xiao, Xinyi Zhang, Lingjun Liu, Haibin Lin, Li-Wen Chang, Jianxi Ye, Xiao Yu, Xuanzhe Liu, Xin Jin, Xin Liu (ByteDance and Peking University), 2025
https://scholar.google.com/scholar?q=MegaScale-Infer%3A+Serving+Mixture-of-Experts+at+Scale+with+Disaggregated+Expert+Parallelism
5. Step-3 is Large yet Affordable: Model-system Co-design for Cost-effective Decoding — StepFun team (Step-3 authors), 2025
https://scholar.google.com/scholar?q=Step-3+is+Large+yet+Affordable%3A+Model-system+Co-design+for+Cost-effective+Decoding
6. Insights into DeepSeek-V3: Scaling Challenges and Reflections on Hardware for AI Architectures — Chenggang Zhao et al. (DeepSeek-AI), 2025
https://scholar.google.com/scholar?q=Insights+into+DeepSeek-V3%3A+Scaling+Challenges+and+Reflections+on+Hardware+for+AI+Architectures
7. DeepSeek-V3 Technical Report / DeepSeek-V3.2-Exp (DeepSeek Sparse Attention) — DeepSeek-AI, 2024 / 2025
https://scholar.google.com/scholar?q=DeepSeek-V3+Technical+Report+%2F+DeepSeek-V3.2-Exp+%28DeepSeek+Sparse+Attention%29
8. Serving Large Language Models on Huawei CloudMatrix384 — Pengfei Zuo et al., 2025
https://scholar.google.com/scholar?q=Serving+Large+Language+Models+on+Huawei+CloudMatrix384
9. NanoFlow: Towards Optimal Large Language Model Serving Throughput — Kan Zhu et al., 2024
https://scholar.google.com/scholar?q=NanoFlow%3A+Towards+Optimal+Large+Language+Model+Serving+Throughput
10. Vidur: A Large-Scale Simulation Framework for LLM Inference — Amey Agrawal et al., 2024
https://scholar.google.com/scholar?q=Vidur%3A+A+Large-Scale+Simulation+Framework+for+LLM+Inference
11. ASTRA-sim2.0: Modeling Hierarchical Networks and Disaggregated Systems for Large-model Training at Scale — William Won et al., 2023
https://scholar.google.com/scholar?q=ASTRA-sim2.0%3A+Modeling+Hierarchical+Networks+and+Disaggregated+Systems+for+Large-model+Training+at+Scale
12. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin et al., 2024
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
13. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Yihua Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
14. Mélange: Cost Efficient Large Language Model Serving by Exploiting GPU Heterogeneity — Tyler Griggs et al., 2024
https://scholar.google.com/scholar?q=M%C3%A9lange%3A+Cost+Efficient+Large+Language+Model+Serving+by+Exploiting+GPU+Heterogeneity
15. Demystifying Platform Requirements for Diverse LLM Inference Use Cases (GenZ) — Abhimanyu Bambhaniya et al., 2024
https://scholar.google.com/scholar?q=Demystifying+Platform+Requirements+for+Diverse+LLM+Inference+Use+Cases+%28GenZ%29