AI R&D Automation and the Intelligence Explosion Question
Oct 13, 2026
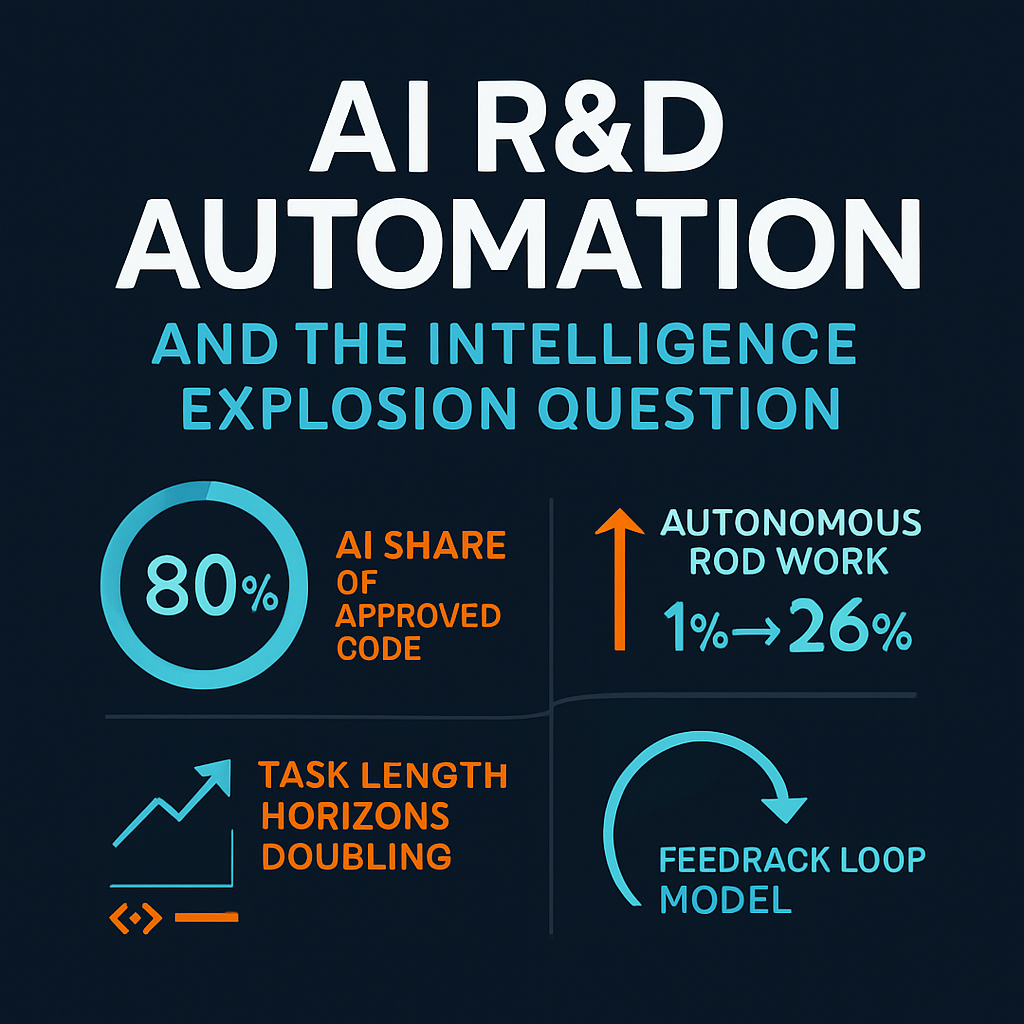
This episode examines a policy paper asking what happens if AI automates AI research itself, setting off an "intelligence explosion" that compresses years of progress into months. It reviews the evidence that automation is already underway, including the AI share of approved code at one lab rising from low single digits to over 80 percent, autonomous R&D work growing from 1 to 26 percent, and task-length horizons doubling about every three months. It also covers the caveats on that evidence, since coding benchmarks don't necessarily translate to research ability. The hosts explain the paper's feedback-loop model, in which a ratio of labor returns to idea-finding difficulty decides whether progress fades, holds steady or accelerates. They also cover the four frictions that could stop the loop (diminishing returns, compute limits, hard-to-automate research taste, and slow training runs) and the stakes of loss of control and eroded checks on power. Listeners get a clear walkthrough of what the argument claims and what it doesn't: it argues for preparation, not that an explosion is certain.
Interactive Visualization: AI R&D Automation and the Intelligence Explosion Question
Sources:
1. What if automating AI R&D triggers an intelligence explosion? — Alan Chan, Christoph Winter, Andrew Barto, Jakub Pachocki, Geoffrey Hinton, Eric Horvitz, Yoshua Bengio, Dawn Song, Jack Clark, Hilary Greaves, Anton Korinek, Samuel Hammond, Thore Graepel, Ben Bariach, Philip H. S. Torr, Sheila A. McIlraith, Jeff Clune, Sam Manning, Girish Sastry, Tom Davidson, Daniel Eth, Sören Mindermann, 2026
http://arxiv.org/abs/2609.36054
2. Speculations Concerning the First Ultraintelligent Machine — I.J. Good, 1965
https://scholar.google.com/scholar?q=Speculations+Concerning+the+First+Ultraintelligent+Machine
3. Intelligence Explosion Microeconomics — Eliezer Yudkowsky, 2013
https://scholar.google.com/scholar?q=Intelligence+Explosion+Microeconomics
4. Are Ideas Getting Harder to Find? — Nicholas Bloom, Charles I. Jones, John Van Reenen, Michael Webb, 2020
https://scholar.google.com/scholar?q=Are+Ideas+Getting+Harder+to+Find%3F
5. Algorithmic progress in language models — Anson Ho, Tamay Besiroglu, Ege Erdil, David Owen, Robi Rahman, Zifan Carson Guo, David Atkinson, Neil Thompson, Jaime Sevilla (Epoch AI), 2024
https://scholar.google.com/scholar?q=Algorithmic+progress+in+language+models
6. RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts — Hjalmar Wijk, Tao Lin, Joel Becker, et al. (METR), 2024
https://scholar.google.com/scholar?q=RE-Bench%3A+Evaluating+frontier+AI+R%26D+capabilities+of+language+model+agents+against+human+experts
7. Measuring AI Ability to Complete Long Tasks — Thomas Kwa, Ben West, Joel Becker, et al. (METR), 2025
https://scholar.google.com/scholar?q=Measuring+AI+Ability+to+Complete+Long+Tasks
8. The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery — Chris Lu, Cong Lu, Robert Tjarko Lange, Jakob Foerster, Jeff Clune, David Ha, 2024
https://scholar.google.com/scholar?q=The+AI+Scientist%3A+Towards+Fully+Automated+Open-Ended+Scientific+Discovery
9. AI 2027 — Daniel Kokotajlo, Scott Alexander, Thomas Larsen, Eli Lifland, Romeo Dean, 2025
https://scholar.google.com/scholar?q=AI+2027
10. The Alignment Problem from a Deep Learning Perspective — Richard Ngo, Lawrence Chan, Sören Mindermann, 2022
https://scholar.google.com/scholar?q=The+Alignment+Problem+from+a+Deep+Learning+Perspective
11. AI Control: Improving Safety Despite Intentional Subversion — Ryan Greenblatt, Buck Shlegeris, Kshitij Sachan, Fabien Roger, 2023
https://scholar.google.com/scholar?q=AI+Control%3A+Improving+Safety+Despite+Intentional+Subversion
12. Alignment faking in large language models — Ryan Greenblatt, Carson Denison, Benjamin Wright, et al. (Anthropic and Redwood Research), 2024
https://scholar.google.com/scholar?q=Alignment+faking+in+large+language+models
13. Managing extreme AI risks amid rapid progress — Yoshua Bengio, Geoffrey Hinton, Andrew Yao, Dawn Song, Pieter Abbeel, et al., 2024
https://scholar.google.com/scholar?q=Managing+extreme+AI+risks+amid+rapid+progress
14. Will compute bottlenecks prevent an intelligence explosion? — Parker Whitfill, Cheryl Wu, 2025
https://scholar.google.com/scholar?q=Will+compute+bottlenecks+prevent+an+intelligence+explosion%3F
15. The software intelligence explosion debate needs experiments — Anson Ho, Parker Whitfill, 2025
https://scholar.google.com/scholar?q=The+software+intelligence+explosion+debate+needs+experiments
16. Will AI R&D Automation Cause a Software Intelligence Explosion? — Daniel Eth, Tom Davidson, 2025
https://scholar.google.com/scholar?q=Will+AI+R%26D+Automation+Cause+a+Software+Intelligence+Explosion%3F
17. Measuring AI Ability to Complete Long Tasks / Time Horizon 1.1 — METR, 2025/2026
https://scholar.google.com/scholar?q=Measuring+AI+Ability+to+Complete+Long+Tasks+%2F+Time+Horizon+1.1
18. When does automating AI research produce explosive growth? Feedback loops in innovation networks — Tom Davidson, Basil Halperin, Thomas Houlden, Anton Korinek, 2026
https://scholar.google.com/scholar?q=When+does+automating+AI+research+produce+explosive+growth%3F+Feedback+loops+in+innovation+networks
19. The economics of recursive self-improvement — Tom Cunningham et al., 2026
https://scholar.google.com/scholar?q=The+economics+of+recursive+self-improvement
20. The bounded parallelizability of R&D: Theory and application to AI — Philip Trammell, 2026
https://scholar.google.com/scholar?q=The+bounded+parallelizability+of+R%26D%3A+Theory+and+application+to+AI
21. On the origin of algorithmic progress in AI — Hans Gundlach et al., 2025
https://scholar.google.com/scholar?q=On+the+origin+of+algorithmic+progress+in+AI
22. The dynamics of intelligence explosions — Toby Ord, 2026
https://scholar.google.com/scholar?q=The+dynamics+of+intelligence+explosions
23. PostTrainBench: Can LLM agents automate LLM post-training? — Rank et al., 2026
https://scholar.google.com/scholar?q=PostTrainBench%3A+Can+LLM+agents+automate+LLM+post-training%3F
24. Towards end-to-end automation of AI research (AI Scientist) — Chris Lu, Cong Lu, Robert Lange, Jeff Clune et al., 2026
https://scholar.google.com/scholar?q=Towards+end-to-end+automation+of+AI+research+%28AI+Scientist%29
25. Frontier AI auditing: Toward rigorous third-party assessment of safety and security practices at leading AI companies — Miles Brundage et al., 2026
https://scholar.google.com/scholar?q=Frontier+AI+auditing%3A+Toward+rigorous+third-party+assessment+of+safety+and+security+practices+at+leading+AI+companies
Interactive Visualization: AI R&D Automation and the Intelligence Explosion Question