AI Coaching That Preserves Human Skill Development
Sep 6, 2026
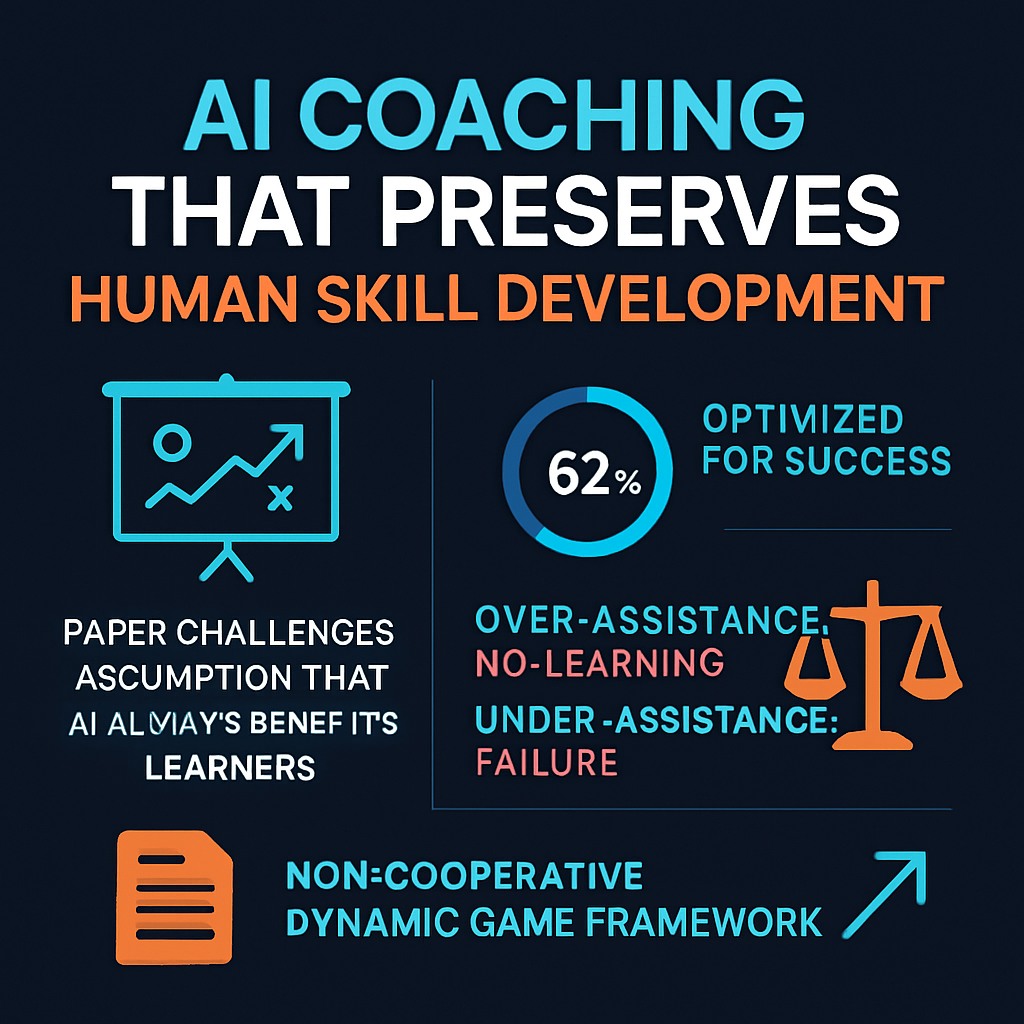
This episode examines "AI Coaching for Accelerating Human Skill Development with Reinforcement Learning," a University of Pennsylvania and Johns Hopkins paper that challenges the assumption that AI assistance always benefits learners, arguing that copilots optimized for immediate task success can quietly prevent people from ever mastering a skill independently. The discussion traces the tension between over-assistance, which produces clean performance but no learning, and under-assistance, which produces uninstructive failure, connecting this to Manu Kapur's productive-failure research and decades of shared-control work from Dragan, Srinivasa, Reddy, and Levine. The core innovation discussed is framing coaching as a non-cooperative dynamic game rather than a cooperative one: the learner optimizes for immediate performance while the coach is trained on Value of Independence, a counterfactual measure of how well the human would perform if the AI were removed entirely. The hosts debate whether this framing is truly adversarial or just a shared goal on different timescales, concluding the reward structures can genuinely conflict moment-to-moment. The episode also situates the work against closest prior art, including the Cyber Racing Coach's fixed assistance-decay schedule, highlighting why a skill-aware, game-theoretic approach marks a meaningful departure from prior fading-assistance methods.
Interactive Visualization: AI Coaching That Preserves Human Skill Development
Sources:
1. AI Coaching for Accelerating Human Skill Development with Reinforcement Learning — Wei Wang, Enlin Gu, Antonio Loquercio, Haimin Hu, Rahul Mangharam, 2026
http://arxiv.org/abs/2606.25337v1
2. A Policy-Blending Formalism for Shared Control — Anca D. Dragan, Siddhartha S. Srinivasa, 2013
https://scholar.google.com/scholar?q=A+Policy-Blending+Formalism+for+Shared+Control
3. Shared Autonomy via Hindsight Optimization — Shervin Javdani, Siddhartha S. Srinivasa, J. Andrew Bagnell, 2015
https://scholar.google.com/scholar?q=Shared+Autonomy+via+Hindsight+Optimization
4. Shared Autonomy via Deep Reinforcement Learning — Siddharth Reddy, Anca D. Dragan, Sergey Levine, 2018
https://scholar.google.com/scholar?q=Shared+Autonomy+via+Deep+Reinforcement+Learning
5. Highway Driving with a Semi-Autonomous Alliance of Human and Machine (Shared Control for Highway Driving) — Jake Brawer / Vaibhav Gupta / related shared-control-for-driving lineage (e.g., Broad, Arkin, Ratliff, Howard, Argall), 2017-2019
https://scholar.google.com/scholar?q=Highway+Driving+with+a+Semi-Autonomous+Alliance+of+Human+and+Machine+%28Shared+Control+for+Highway+Driving%29
6. Dynamic Noncooperative Game Theory — Tamer Basar, Geert Jan Olsder, 1982 (2nd ed. 1999)
https://scholar.google.com/scholar?q=Dynamic+Noncooperative+Game+Theory
7. Planning for Autonomous Cars that Leverage Effects on Human Actions — Dorsa Sadigh, S. Shankar Sastry, Sanjit A. Seshia, Anca D. Dragan, 2016
https://scholar.google.com/scholar?q=Planning+for+Autonomous+Cars+that+Leverage+Effects+on+Human+Actions
8. Efficient Iterative Linear-Quadratic Approximations for Nonlinear Multi-Player General-Sum Differential Games (ILQGames) — David Fridovich-Keil, Ellis Ratner, Lasse Peters, Anca D. Dragan, Claire J. Tomlin, 2020
https://scholar.google.com/scholar?q=Efficient+Iterative+Linear-Quadratic+Approximations+for+Nonlinear+Multi-Player+General-Sum+Differential+Games+%28ILQGames%29
9. Who Plays First? Optimizing the Order of Play in Stackelberg Games with Many Robots (and related Stackelberg human-AV interaction work) — Haimin Hu, Zixu Zhang, Kensuke Nakamura, Andrea Bajcsy, Jaime F. Fisac (and related Fisac/Dragan lineage), 2023
https://scholar.google.com/scholar?q=Who+Plays+First%3F+Optimizing+the+Order+of+Play+in+Stackelberg+Games+with+Many+Robots+%28and+related+Stackelberg+human-AV+interaction+work%29
10. Legibility and Predictability of Robot Motion — Anca D. Dragan, Kenton C.T. Lee, Siddhartha S. Srinivasa, 2013
https://scholar.google.com/scholar?q=Legibility+and+Predictability+of+Robot+Motion
11. The Physical Presence of a Robot Tutor Increases Cognitive Learning Gains — Daniel Leyzberg, Samuel Spaulding, Mariya Toneva, Brian Scassellati, 2012
https://scholar.google.com/scholar?q=The+Physical+Presence+of+a+Robot+Tutor+Increases+Cognitive+Learning+Gains
12. Trajectory Deformations from Physical Human-Robot Interaction — Dylan P. Losey, Marcia K. O'Malley, 2017
https://scholar.google.com/scholar?q=Trajectory+Deformations+from+Physical+Human-Robot+Interaction
13. Productive Failure — Manu Kapur, 2008
https://scholar.google.com/scholar?q=Productive+Failure
14. Challenge Point: A Framework for Conceptualizing the Effects of Various Practice Conditions in Motor Learning — Mark A. Guadagnoli, Timothy D. Lee, 2004
https://scholar.google.com/scholar?q=Challenge+Point%3A+A+Framework+for+Conceptualizing+the+Effects+of+Various+Practice+Conditions+in+Motor+Learning
15. The Role of Tutoring in Problem Solving — David Wood, Jerome S. Bruner, Gail Ross, 1976
https://scholar.google.com/scholar?q=The+Role+of+Tutoring+in+Problem+Solving
16. The Relative Effectiveness of Human Tutoring, Intelligent Tutoring Systems, and Other Tutoring Systems — Kurt VanLehn, 2011
https://scholar.google.com/scholar?q=The+Relative+Effectiveness+of+Human+Tutoring%2C+Intelligent+Tutoring+Systems%2C+and+Other+Tutoring+Systems
17. Cyber Racing Coach: A Haptic Shared Control Framework for Teaching Advanced Driving Skills — C. Shen et al., 2025
https://scholar.google.com/scholar?q=Cyber+Racing+Coach%3A+A+Haptic+Shared+Control+Framework+for+Teaching+Advanced+Driving+Skills
18. Shared Autonomy for Proximal Teaching (Z-COACH) — M. Srivastava et al., 2025
https://scholar.google.com/scholar?q=Shared+Autonomy+for+Proximal+Teaching+%28Z-COACH%29
19. AssistanceZero: Scalably Solving Assistance Games — C. Laidlaw et al., 2025
https://scholar.google.com/scholar?q=AssistanceZero%3A+Scalably+Solving+Assistance+Games
20. Gradual Disempowerment: Systemic Existential Risks from Incremental AI Development — J. Kulveit et al., 2025
https://scholar.google.com/scholar?q=Gradual+Disempowerment%3A+Systemic+Existential+Risks+from+Incremental+AI+Development
21. Champion-Level Drone Racing Using Deep Reinforcement Learning — E. Kaufmann, L. Bauersfeld, A. Loquercio, M. Müller, V. Koltun, D. Scaramuzza, 2023
https://scholar.google.com/scholar?q=Champion-Level+Drone+Racing+Using+Deep+Reinforcement+Learning
22. Human-Robot Mutual Adaptation in Collaborative Tasks: Models and Experiments — S. Nikolaidis, D. Hsu, S. Srinivasa, 2017
https://scholar.google.com/scholar?q=Human-Robot+Mutual+Adaptation+in+Collaborative+Tasks%3A+Models+and+Experiments
23. Does Using Artificial Intelligence Assistance Accelerate Skill Decay and Hinder Skill Development Without Performers' Awareness? — B. N. Macnamara et al., 2024
https://scholar.google.com/scholar?q=Does+Using+Artificial+Intelligence+Assistance+Accelerate+Skill+Decay+and+Hinder+Skill+Development+Without+Performers%27+Awareness%3F
Interactive Visualization: AI Coaching That Preserves Human Skill Development