Agent Memory Costs: Characterizing Write-Time Overhead in Long-Horizon Workloads
Nov 1, 2026
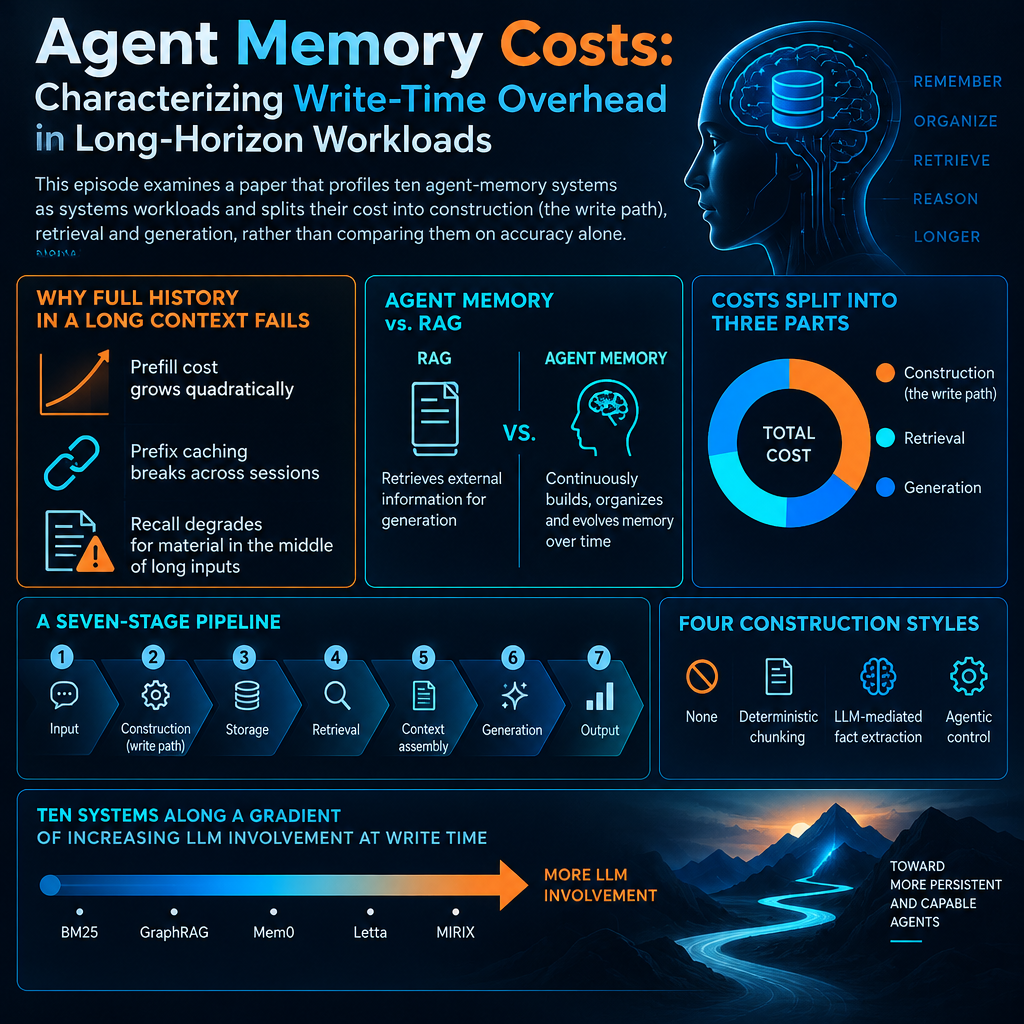
This episode examines a paper that profiles ten agent-memory systems as systems workloads and splits their cost into construction (the write path), retrieval and generation, rather than comparing them on accuracy alone. It covers why pasting full history into a long context fails: prefill cost grows quadratically, prefix caching breaks across sessions, and recall degrades for material in the middle of long inputs. It then explains how agent memory differs from RAG and walks through a seven-stage pipeline and four construction styles, from none to deterministic chunking, LLM-mediated fact extraction and agentic control. The ten systems, including BM25, GraphRAG, Mem0, Letta and MIRIX, are placed along a gradient of increasing LLM involvement at write time. The discussion also lays out the measurement setup (phase-tagged calls aligned with GPU telemetry on a single H100 with Qwen3 models, plus remote OpenAI models) and previews the argument that construction is the hidden bill. Listeners get a concrete view of where long-lived agents spend compute and energy, and why that matters for scheduling.
Interactive Visualization: Agent Memory Costs: Characterizing Write-Time Overhead in Long-Horizon Workloads
Sources:
1. Agent Memory: Characterization and System Implications of Stateful Long-Horizon Workloads — Yasmine Omri, Ziyu Gan, Zachary Broveak, Robin Geens, Zexue He, Alex Pentland, Marian Verhelst, Tsachy Weissman, Thierry Tambe, 2026
http://arxiv.org/abs/2606.06448
2. MemGPT: Towards LLMs as Operating Systems — Charles Packer, Sarah Wooders, Kevin Lin, Vivian Fang, Shishir G. Patil, Ion Stoica, Joseph E. Gonzalez, 2023
https://scholar.google.com/scholar?q=MemGPT%3A+Towards+LLMs+as+Operating+Systems
3. Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory — Prateek Chhikara, Dev Khant, Saket Aryan, Taranjeet Singh, Deshraj Yadav, 2025
https://scholar.google.com/scholar?q=Mem0%3A+Building+Production-Ready+AI+Agents+with+Scalable+Long-Term+Memory
4. Evaluating Very Long-Term Conversational Memory of LLM Agents (LoCoMo) — Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, Yuwei Fang, 2024
https://scholar.google.com/scholar?q=Evaluating+Very+Long-Term+Conversational+Memory+of+LLM+Agents+%28LoCoMo%29
5. Sleep-time Compute: Beyond Inference Scaling at Test-time — Kevin Lin, Charlie Snell, Yu Wang, Charles Packer, Sarah Wooders, Ion Stoica, Joseph E. Gonzalez, 2025
https://scholar.google.com/scholar?q=Sleep-time+Compute%3A+Beyond+Inference+Scaling+at+Test-time
6. Zep: A Temporal Knowledge Graph Architecture for Agent Memory — Preston Rasmussen, Pavel Paliychuk, Travis Beauvais, Jack Ryan, Daniel Chalef, 2025
https://scholar.google.com/scholar?q=Zep%3A+A+Temporal+Knowledge+Graph+Architecture+for+Agent+Memory
7. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Yihua Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
8. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin et al., 2024
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
9. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference with Chunked Prefills — Amey Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Chunked+Prefills
10. Zep, LightMem, and other efficiency-oriented memory systems (e.g., LightMem: Lightweight and Efficient Memory-Augmented Generation) — Various, 2025
https://scholar.google.com/scholar?q=Zep%2C+LightMem%2C+and+other+efficiency-oriented+memory+systems+%28e.g.%2C+LightMem%3A+Lightweight+and+Efficient+Memory-Augmented+Generation%29
11. Cartridges: Lightweight and General-Purpose Long Context Representations via Self-Study — Sabri Eyuboglu et al., 2025
https://scholar.google.com/scholar?q=Cartridges%3A+Lightweight+and+General-Purpose+Long+Context+Representations+via+Self-Study
12. Efficient Memory Management for Large Language Model Serving with PagedAttention (vLLM) — Woosuk Kwon et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention+%28vLLM%29
13. Large-scale cluster management at Google with Borg — Abhishek Verma et al., 2015
https://scholar.google.com/scholar?q=Large-scale+cluster+management+at+Google+with+Borg
Interactive Visualization: Agent Memory Costs: Characterizing Write-Time Overhead in Long-Horizon Workloads
1. Agent Memory: Characterization and System Implications of Stateful Long-Horizon Workloads — Yasmine Omri, Ziyu Gan, Zachary Broveak, Robin Geens, Zexue He, Alex Pentland, Marian Verhelst, Tsachy Weissman, Thierry Tambe, 2026
http://arxiv.org/abs/2606.06448
2. MemGPT: Towards LLMs as Operating Systems — Charles Packer, Sarah Wooders, Kevin Lin, Vivian Fang, Shishir G. Patil, Ion Stoica, Joseph E. Gonzalez, 2023
https://scholar.google.com/scholar?q=MemGPT%3A+Towards+LLMs+as+Operating+Systems
3. Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory — Prateek Chhikara, Dev Khant, Saket Aryan, Taranjeet Singh, Deshraj Yadav, 2025
https://scholar.google.com/scholar?q=Mem0%3A+Building+Production-Ready+AI+Agents+with+Scalable+Long-Term+Memory
4. Evaluating Very Long-Term Conversational Memory of LLM Agents (LoCoMo) — Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, Yuwei Fang, 2024
https://scholar.google.com/scholar?q=Evaluating+Very+Long-Term+Conversational+Memory+of+LLM+Agents+%28LoCoMo%29
5. Sleep-time Compute: Beyond Inference Scaling at Test-time — Kevin Lin, Charlie Snell, Yu Wang, Charles Packer, Sarah Wooders, Ion Stoica, Joseph E. Gonzalez, 2025
https://scholar.google.com/scholar?q=Sleep-time+Compute%3A+Beyond+Inference+Scaling+at+Test-time
6. Zep: A Temporal Knowledge Graph Architecture for Agent Memory — Preston Rasmussen, Pavel Paliychuk, Travis Beauvais, Jack Ryan, Daniel Chalef, 2025
https://scholar.google.com/scholar?q=Zep%3A+A+Temporal+Knowledge+Graph+Architecture+for+Agent+Memory
7. LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference — Yihua Cheng et al., 2025
https://scholar.google.com/scholar?q=LMCache%3A+An+Efficient+KV+Cache+Layer+for+Enterprise-Scale+LLM+Inference
8. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin et al., 2024
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
9. Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference with Chunked Prefills — Amey Agrawal et al., 2024
https://scholar.google.com/scholar?q=Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Chunked+Prefills
10. Zep, LightMem, and other efficiency-oriented memory systems (e.g., LightMem: Lightweight and Efficient Memory-Augmented Generation) — Various, 2025
https://scholar.google.com/scholar?q=Zep%2C+LightMem%2C+and+other+efficiency-oriented+memory+systems+%28e.g.%2C+LightMem%3A+Lightweight+and+Efficient+Memory-Augmented+Generation%29
11. Cartridges: Lightweight and General-Purpose Long Context Representations via Self-Study — Sabri Eyuboglu et al., 2025
https://scholar.google.com/scholar?q=Cartridges%3A+Lightweight+and+General-Purpose+Long+Context+Representations+via+Self-Study
12. Efficient Memory Management for Large Language Model Serving with PagedAttention (vLLM) — Woosuk Kwon et al., 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention+%28vLLM%29
13. Large-scale cluster management at Google with Borg — Abhishek Verma et al., 2015
https://scholar.google.com/scholar?q=Large-scale+cluster+management+at+Google+with+Borg
Interactive Visualization: Agent Memory Costs: Characterizing Write-Time Overhead in Long-Horizon Workloads