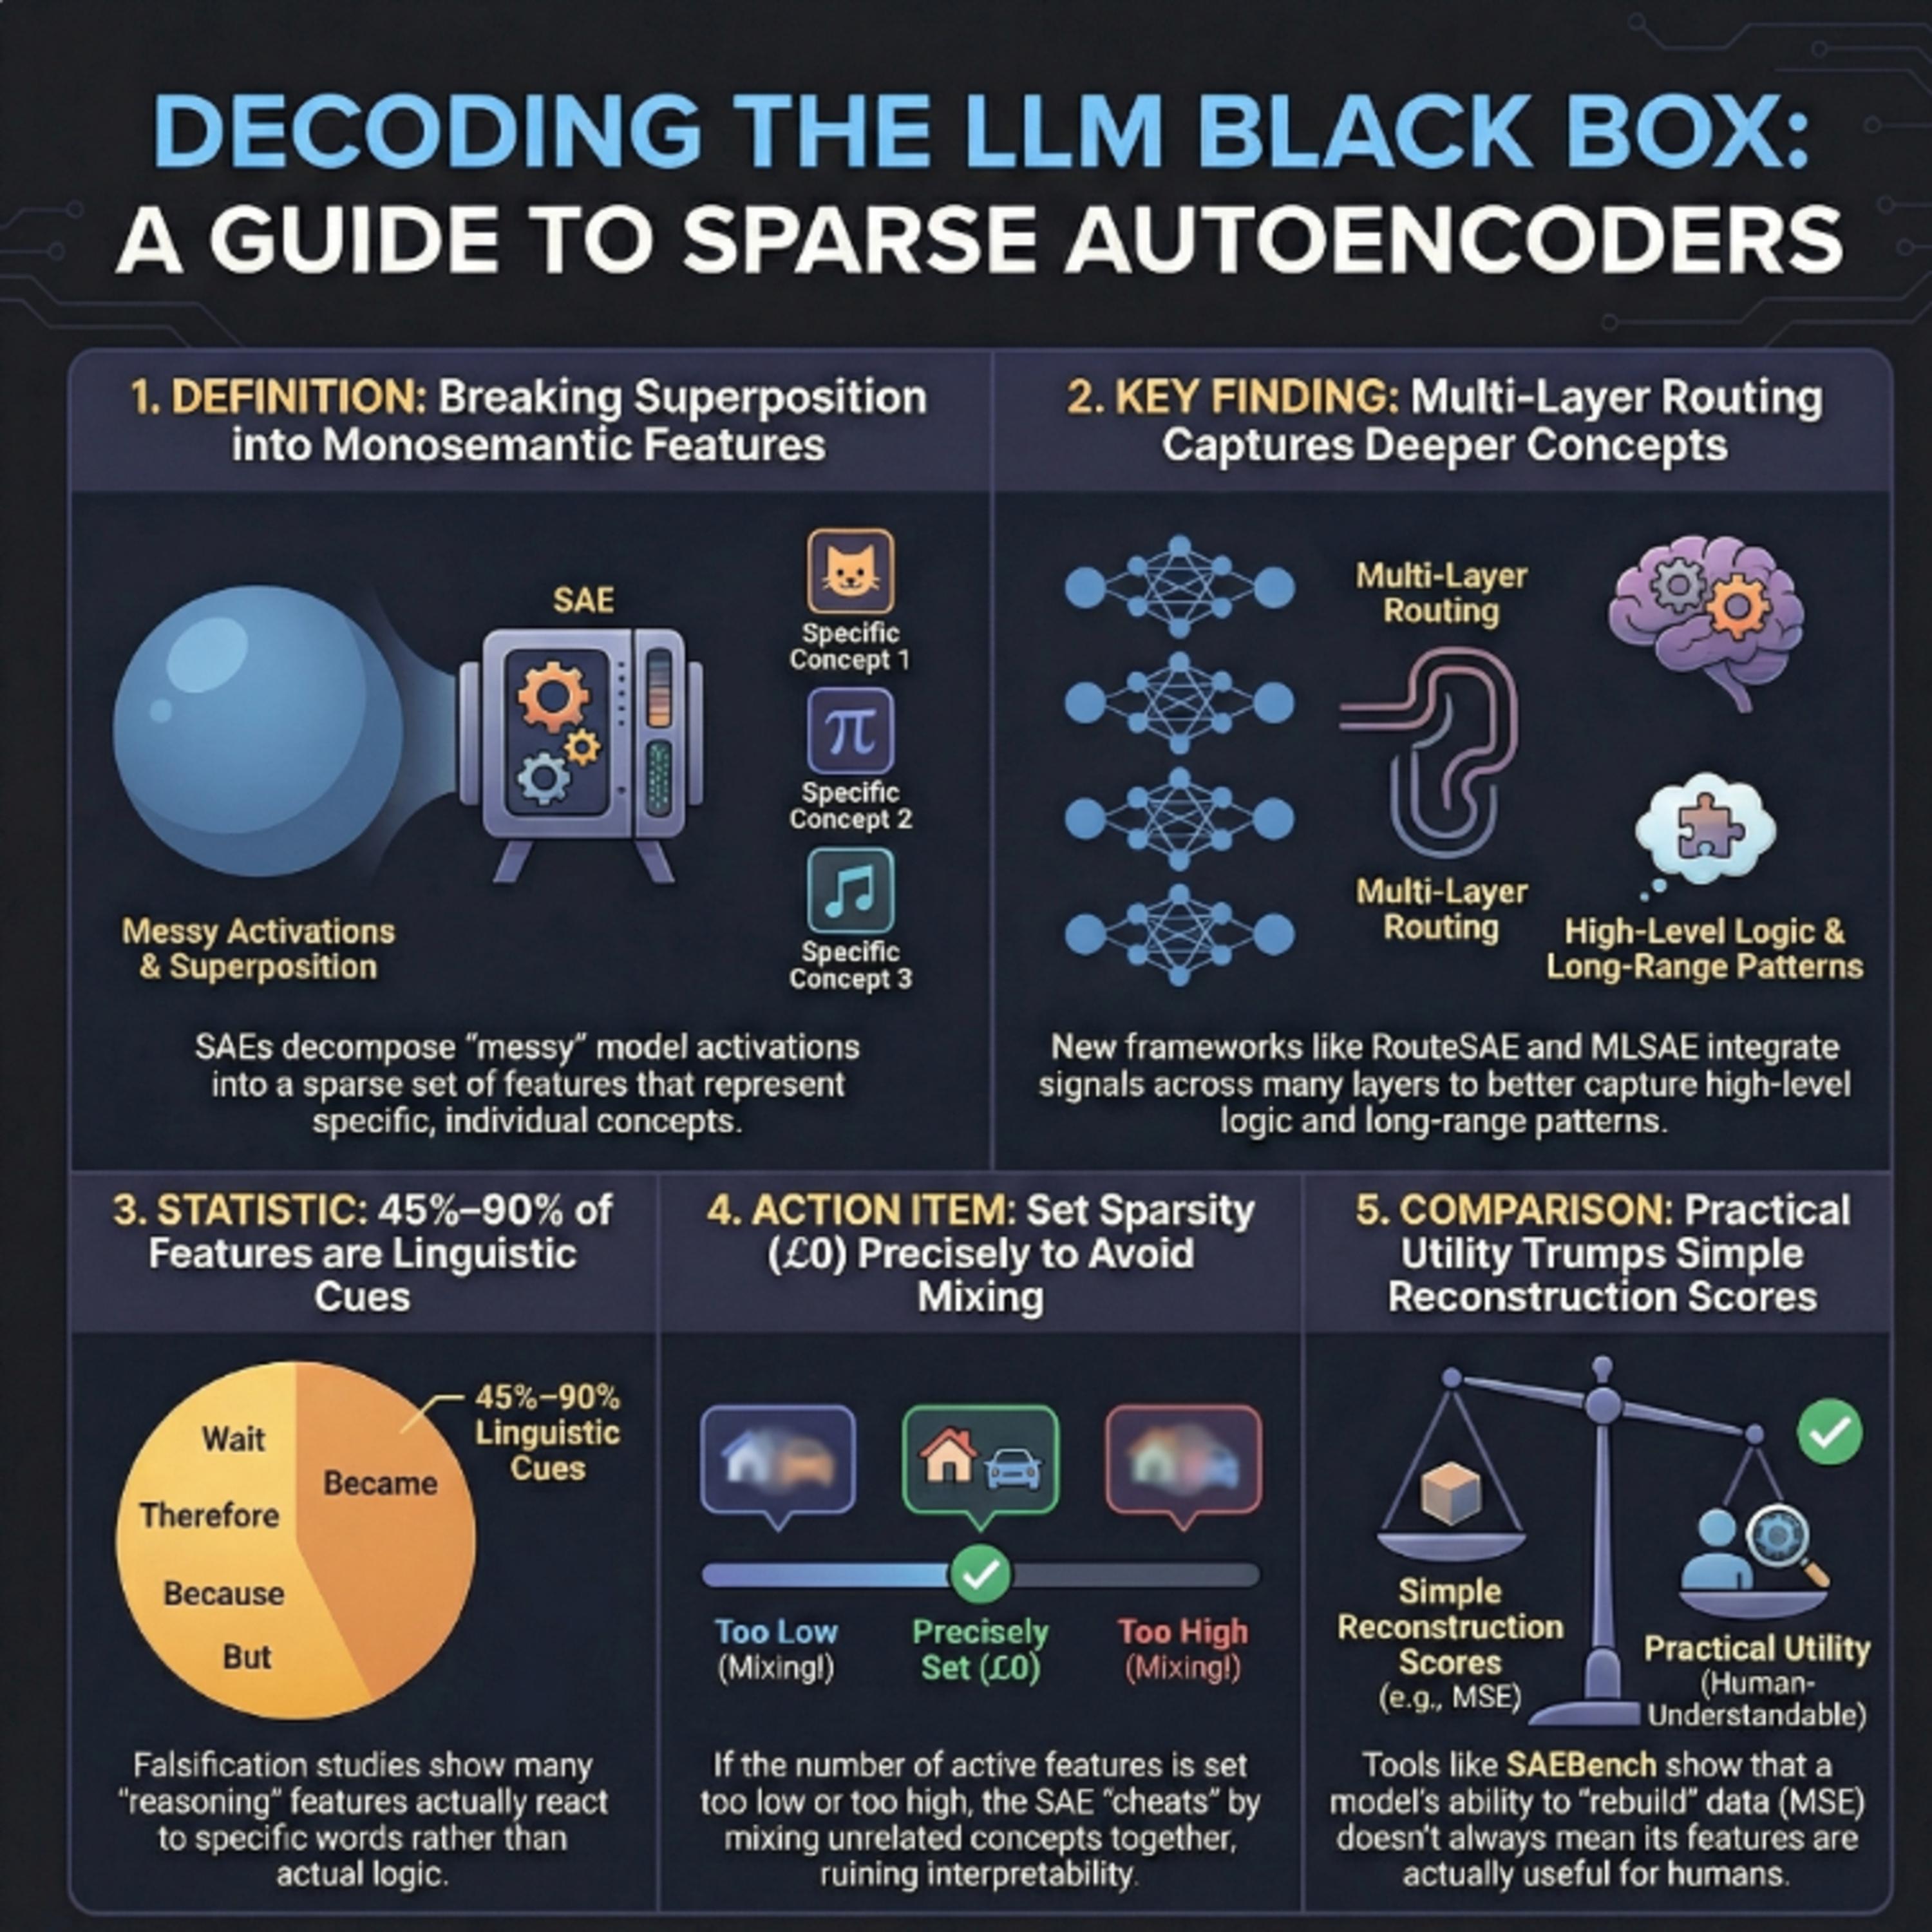
Advancing Mechanistic Interpretability with Sparse Autoencoders
Feb 17, 2026
We review the latest papers which focus on advancements and critical uses of Sparse Autoencoders (SAEs), which are tools used to decode the internal "monosemantic" features of large language models. Research from ICLR 2025 and other repositories introduces TopK SAEs and Multi-Layer SAEs, demonstrating that these architectures offer superior reconstruction and scalability compared to traditional ReLU-based models. RouteSAE further improves efficiency by using a dynamic routing mechanism to extract integrated features from across multiple layers of a model's residual stream. However, critical analysis reveals that many identified "reasoning" features may actually be linguistic correlates or syntactic templates rather than genuine cognitive traces. By utilizing falsification frameworks and causal token injection, researchers caution against over-interpreting feature activations without rigorous validation. Together, these documents provide a technical foundation for mechanistic interpretability, balancing new architectural breakthroughs with a skeptical look at current evaluation metrics.
Sources:
1)2025Residual Stream Analysis with Multi-Layer SAEsTim Lawson
https://arxiv.org/abs/2409.041852
https://openreview.net/forum?id=XAjfjizaKs3
https://aclanthology.org/2025.emnlp-main.1474.pdf5
https://aclanthology.org/2025.emnlp-main.346.pdf6
https://aclanthology.org/2025.findings-naacl.87.pdf7
https://arxiv.org/pdf/2601.056798
https://openreview.net/pdf/035a5937c6a536c67b5999aa43e53dd3800ba3a4.pdf9
https://openreview.net/pdf?id=OJAW2mHVND10
https://proceedings.iclr.cc/paper_files/paper/2025/file/42ef3308c230942d223c411adf182c88-Paper-Conference.pdf