Advances in Attention Distillation for Efficient Transformer Models
Feb 11, 2026
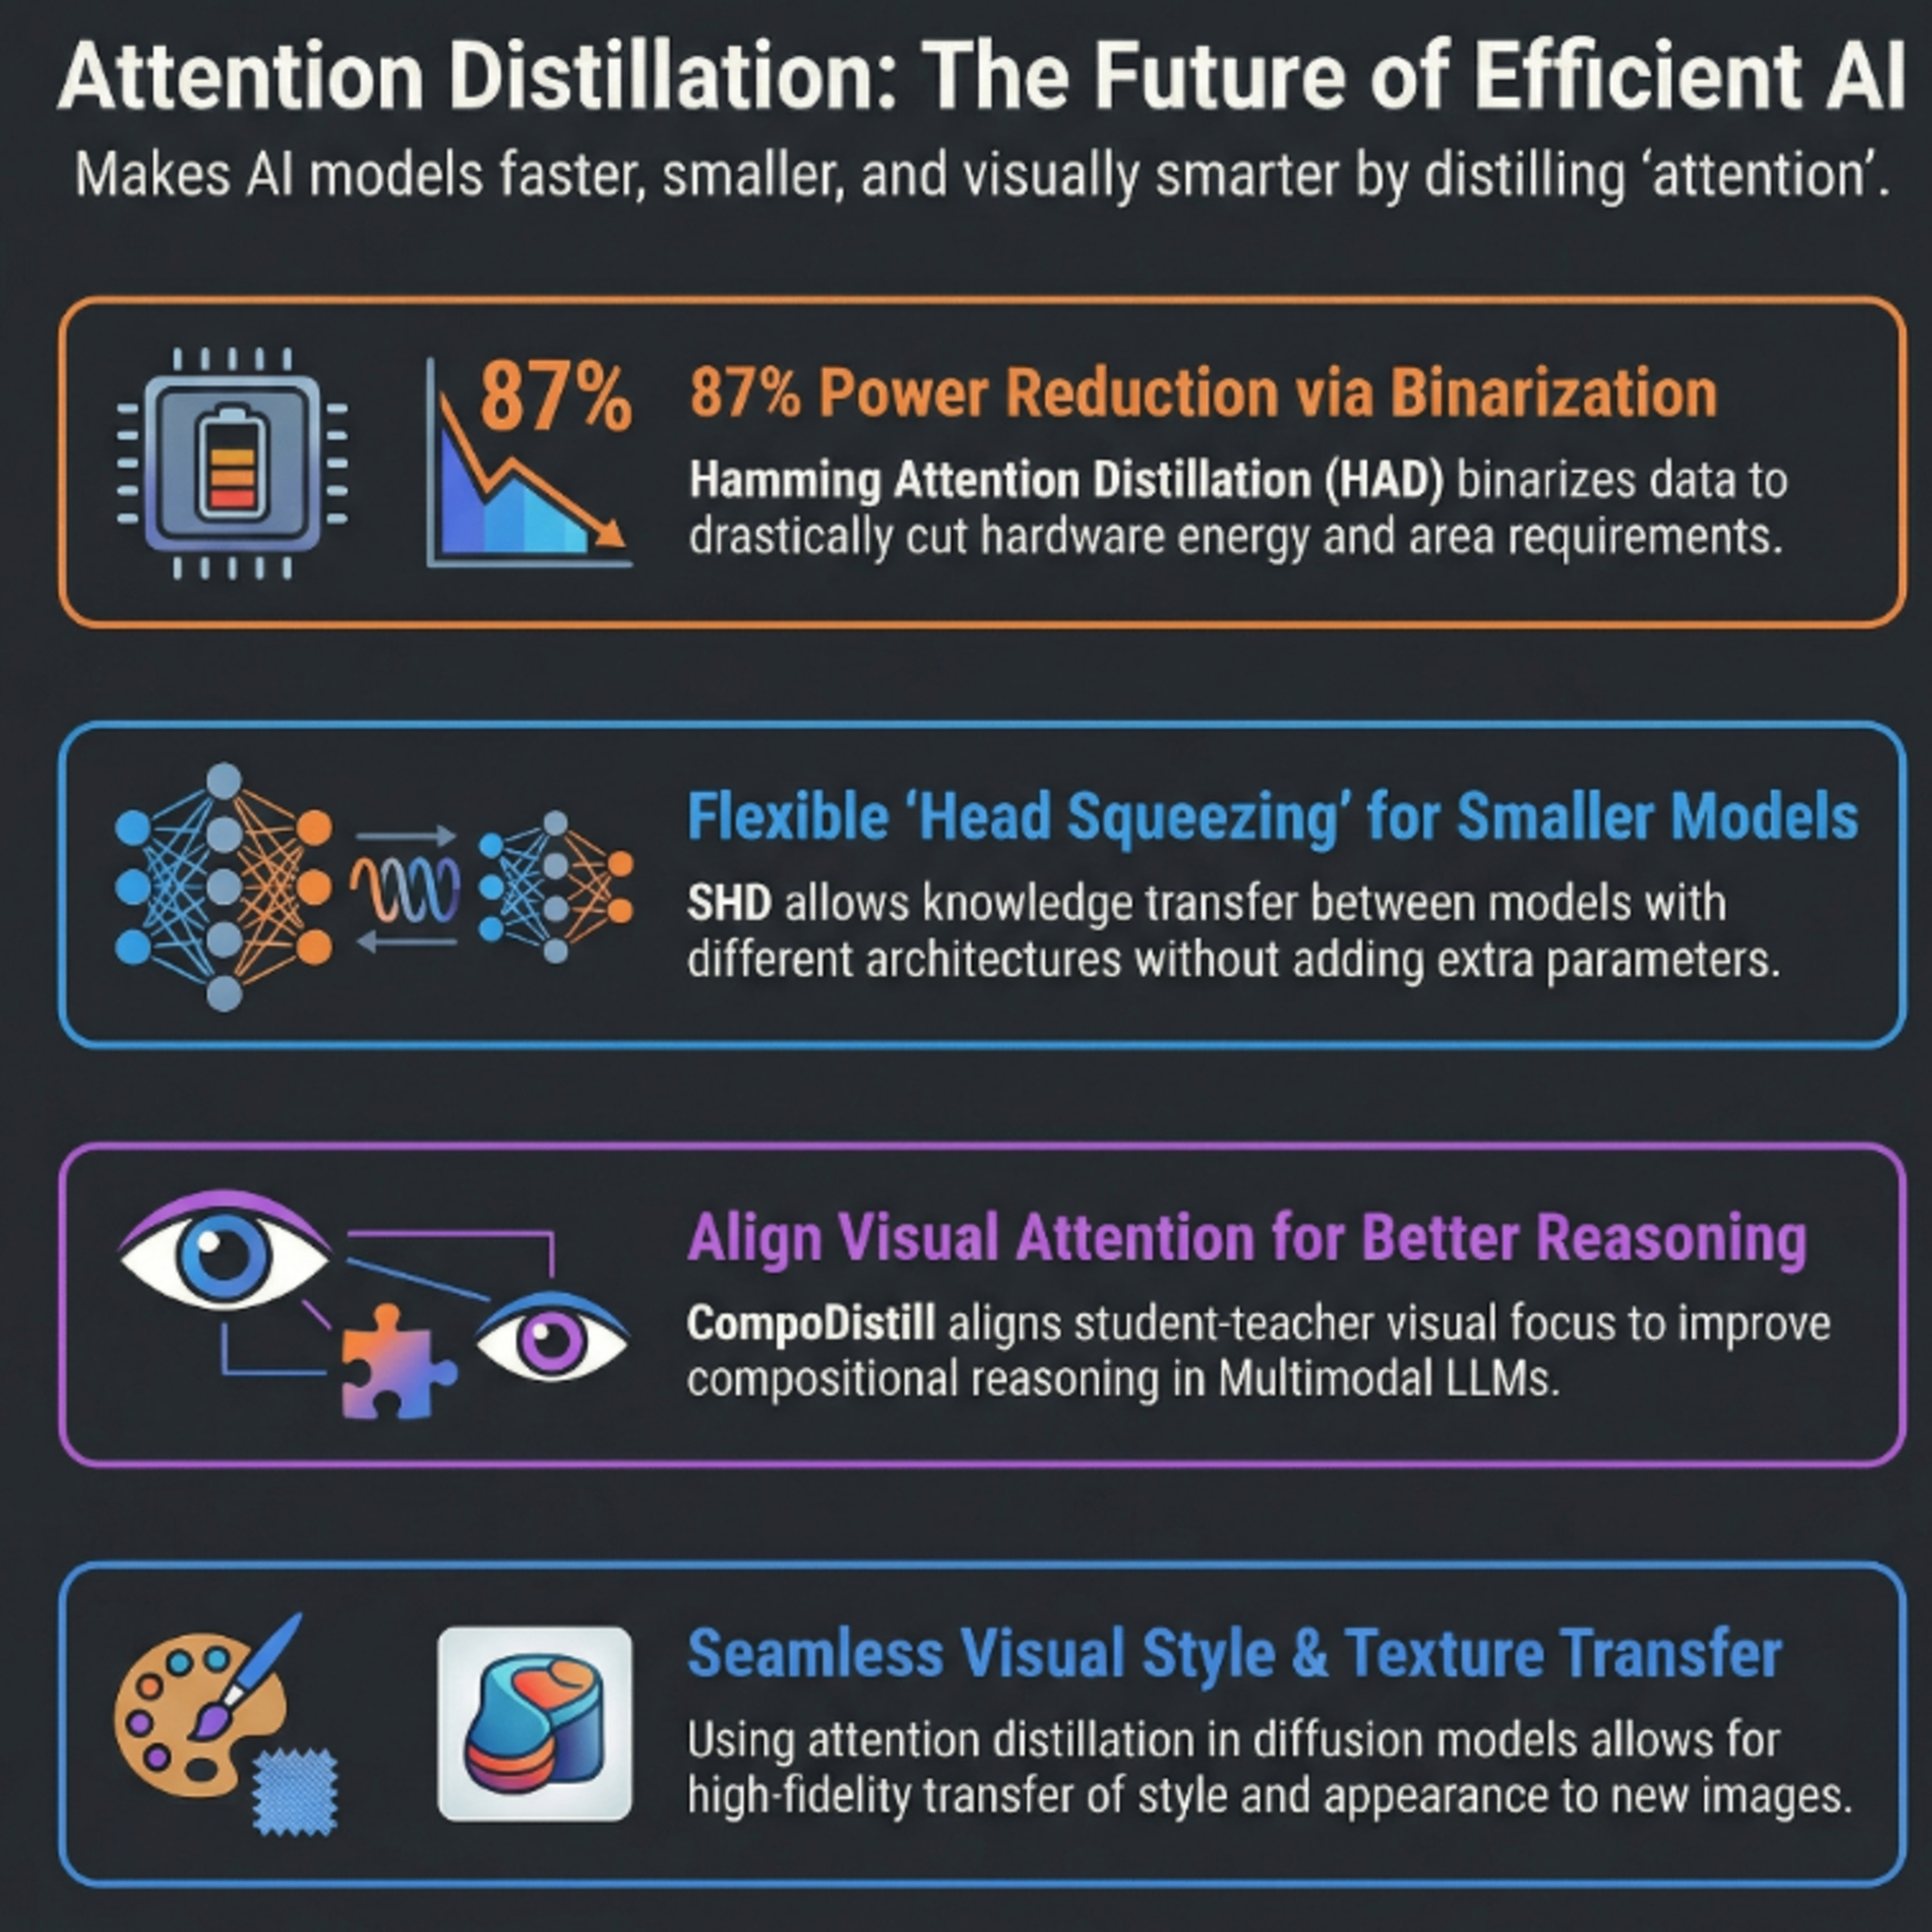
Recent research advances attention distillation to optimize transformers. HAD binarizes keys/queries for efficiency, while SHD aligns varying head counts. CompoDistill improves multimodal reasoning via visual alignment, and new losses transfer visual characteristics in diffusion models.
Sources:
1)February 3 2025Hamming Attention Distillation: Binarizing Keys and Queries for Efficient Long-Context TransformersMark Horton, Tergel Molom-Ochir, Peter Liu, Bhavna Gopal, Chiyue Wei, Cong Guo, Brady Taylor, Deliang Fan, Shan X. Wang, Hai Li, Yiran Chen
https://doi.org/10.48550/arXiv.2502.017702
https://doi.org/10.48550/arXiv.2502.074363
https://doi.org/10.48550/arXiv.2502.202354
https://doi.org/10.48550/arXiv.2510.12184