Abstract Chain-of-Thought: Reasoning with Discrete Latent Tokens
Oct 12, 2026
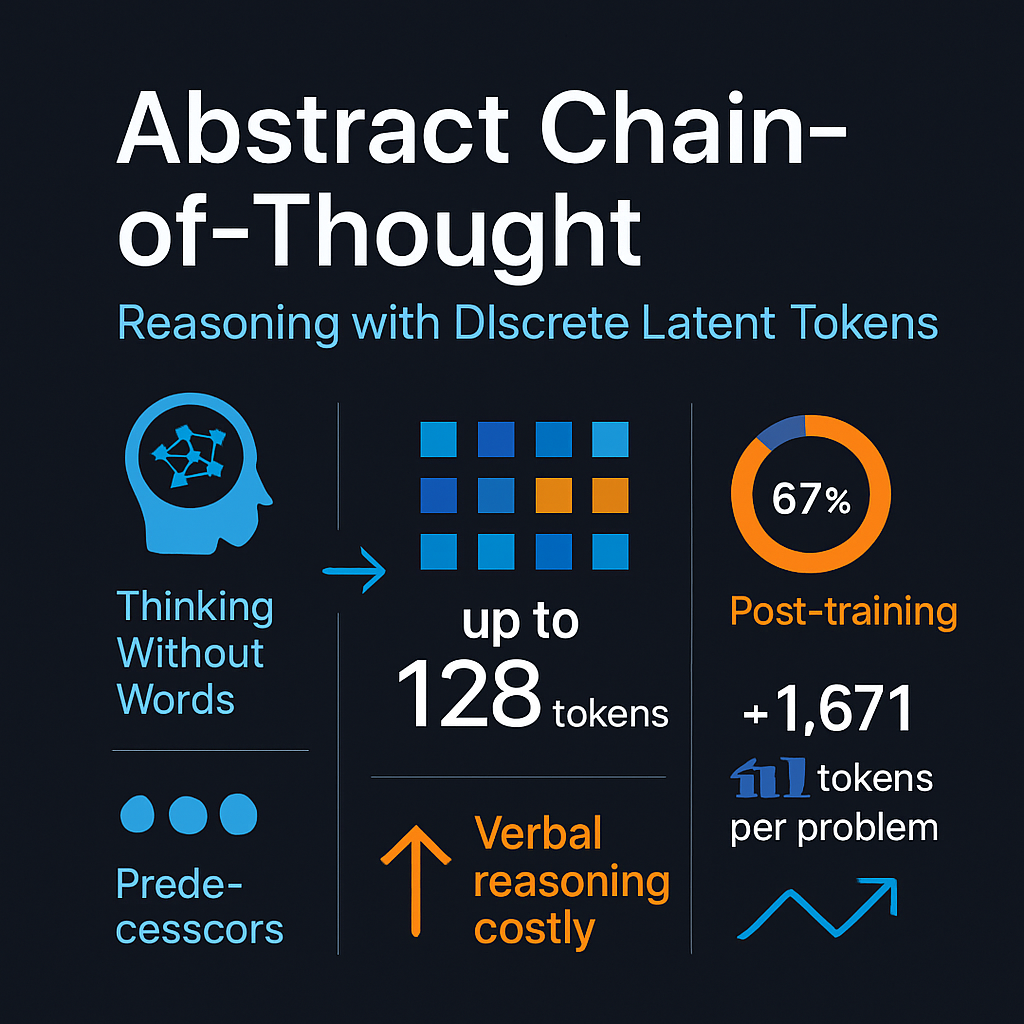
This episode examines "Thinking Without Words," a paper proposing Abstract Chain-of-Thought, which replaces long written-out reasoning with a short run of up to 128 tokens drawn from a new 64-token codebook that has no meaning in English. It sets the approach against its predecessors: pause tokens, which tend to fail when added after pre-training, stepwise internalization, and continuous latent methods such as Coconut and CODI. Against these, it presents the claim that the method works through post-training alone, with ordinary discrete decoding. The motivation is that verbal reasoning is costly (a Qwen3-8B model trained with RL averages roughly 1,671 tokens per MATH-500 problem) and may not faithfully reflect what drives the answer. The discussion also covers the warm-up stage, where an attention mask hides the verbal reasoning from the answer so the new tokens have to carry the content. It treats the paper's "information bottleneck" framing carefully, noting that it motivates the structure without anything being measured or optimized in information-theoretic terms.
Interactive Visualization: Abstract Chain-of-Thought: Reasoning with Discrete Latent Tokens
Sources:
1. Thinking Without Words: Efficient Latent Reasoning with Abstract Chain-of-Thought — Keshav Ramji, Tahira Naseem, Ramón Fernandez Astudillo, 2026
http://arxiv.org/abs/2604.22709
2. Training Large Language Models to Reason in a Continuous Latent Space (Coconut) — Shibo Hao et al., 2024/2025
https://scholar.google.com/scholar?q=Training+Large+Language+Models+to+Reason+in+a+Continuous+Latent+Space+%28Coconut%29
3. CODI: Compressing Chain-of-Thought into Continuous Space via Self-Distillation — Zhenyi Shen et al., 2025
https://scholar.google.com/scholar?q=CODI%3A+Compressing+Chain-of-Thought+into+Continuous+Space+via+Self-Distillation
4. Think before you speak: Training Language Models with Pause Tokens — Sachin Goyal et al., 2024
https://scholar.google.com/scholar?q=Think+before+you+speak%3A+Training+Language+Models+with+Pause+Tokens
5. L1: Controlling How Long a Reasoning Model Thinks with Reinforcement Learning — Pranjal Aggarwal, Sean Welleck, 2025
https://scholar.google.com/scholar?q=L1%3A+Controlling+How+Long+a+Reasoning+Model+Thinks+with+Reinforcement+Learning
6. Let's Think Dot by Dot: Hidden Computation in Transformer Language Models — Jacob Pfau, William Merrill, Samuel R. Bowman, 2024
https://scholar.google.com/scholar?q=Let%27s+Think+Dot+by+Dot%3A+Hidden+Computation+in+Transformer+Language+Models
7. Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety — Tomek Korbak et al., 2025
https://scholar.google.com/scholar?q=Chain+of+Thought+Monitorability%3A+A+New+and+Fragile+Opportunity+for+AI+Safety
8. Soft Tokens, Hard Truths — Natasha Butt et al., 2025
https://scholar.google.com/scholar?q=Soft+Tokens%2C+Hard+Truths
9. Learning to Compress Prompts with Gist Tokens — Jesse Mu et al., 2023
https://scholar.google.com/scholar?q=Learning+to+Compress+Prompts+with+Gist+Tokens
10. Language Models Don't Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting — Miles Turpin et al., 2023
https://scholar.google.com/scholar?q=Language+Models+Don%27t+Always+Say+What+They+Think%3A+Unfaithful+Explanations+in+Chain-of-Thought+Prompting
Interactive Visualization: Abstract Chain-of-Thought: Reasoning with Discrete Latent Tokens