98× Faster LLM Routing with Flash Attention for vLLM Semantic Router
Oct 12, 2026
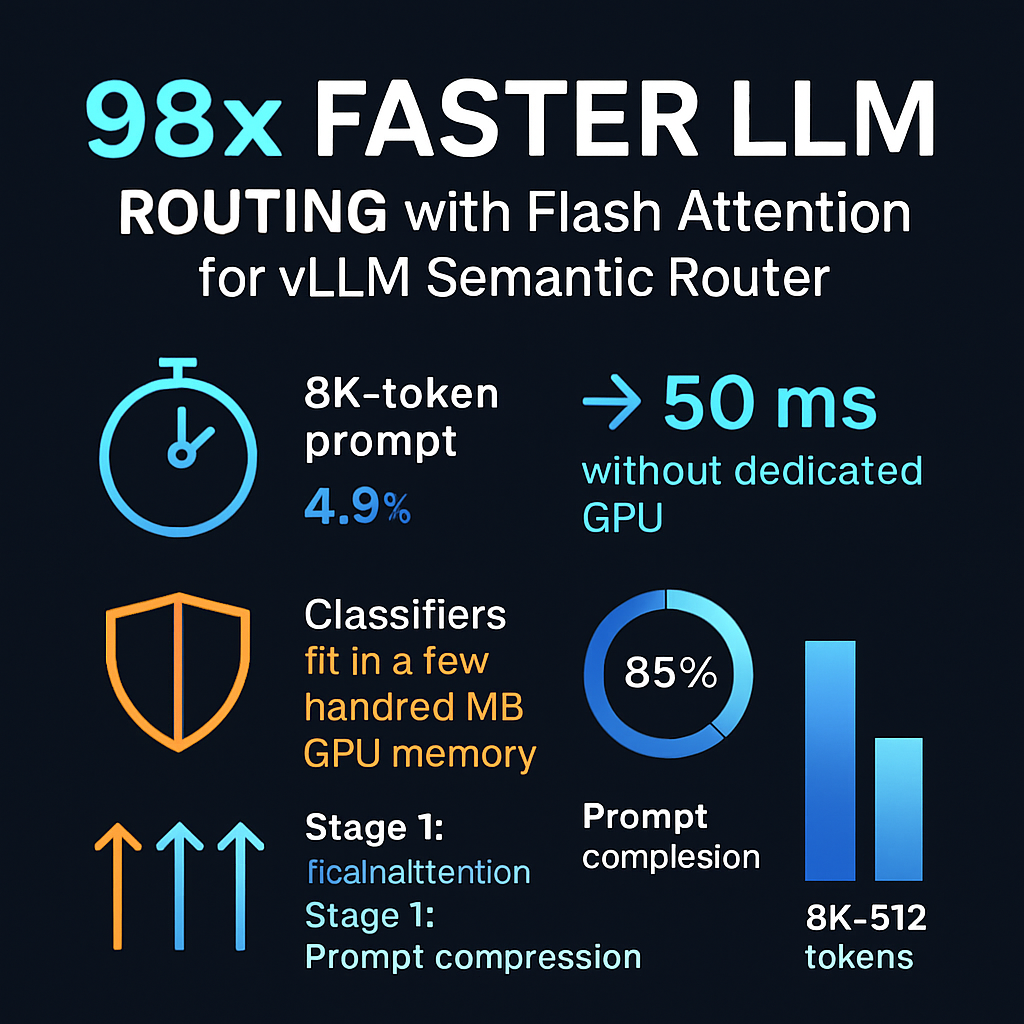
This episode examines a March 2026 paper on the vLLM Semantic Router. The paper claims to cut routing time for an 8K-token prompt from about 4.9 seconds to 50 milliseconds without a dedicated GPU. It explains how the router runs jailbreak, PII and domain classifiers inside Envoy before the first token. It also explains why those classifiers must fit in a few hundred megabytes of GPU memory left over by vLLM, since quadratic attention score and mask matrices blow past that budget. The discussion covers the three-stage fix. The first stage is FlashAttention through a custom AMD Composable Kernel operator for ONNX Runtime on MI300X. The second is compressing prompts to about 512 tokens with classical sentence scoring instead of a neural compressor. The third is near-streaming request handling with zero-copy JSON parsing. The hosts treat the 98× figure as a pipeline-versus-pipeline comparison and try to separate how much comes from the attention kernel and how much from simply moving off the CPU. Listeners interested in inference infrastructure get a clear look at the hidden latency costs that sit in front of an LLM.
Interactive Visualization: 98× Faster LLM Routing with Flash Attention for vLLM Semantic Router
Sources:
1. 98$\times$ Faster LLM Routing Without a Dedicated GPU: Flash Attention, Prompt Compression, and Near-Streaming for the vLLM Semantic Router — Xunzhuo Liu, Bowei He, Xue Liu, Andy Luo, Haichen Zhang, Huamin Chen, 2026
http://arxiv.org/abs/2603.12646
2. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
3. FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning — Tri Dao, 2023
https://scholar.google.com/scholar?q=FlashAttention-2%3A+Faster+Attention+with+Better+Parallelism+and+Work+Partitioning
4. Online normalizer calculation for softmax — Maxim Milakov, Natalia Gimelshein, 2018
https://scholar.google.com/scholar?q=Online+normalizer+calculation+for+softmax
5. Smarter Hardware, Not Harder Math: Warner et al., Smarter, Better, Faster, Longer: A Modern Bidirectional Encoder for Fast, Memory Efficient, and Long Context Finetuning and Inference (ModernBERT) — Benjamin Warner, Antoine Chaffin, Benjamin Clavié, et al., 2024
https://scholar.google.com/scholar?q=Smarter+Hardware%2C+Not+Harder+Math%3A+Warner+et+al.%2C+Smarter%2C+Better%2C+Faster%2C+Longer%3A+A+Modern+Bidirectional+Encoder+for+Fast%2C+Memory+Efficient%2C+and+Long+Context+Finetuning+and+Inference+%28ModernBERT%29
6. Parsing Gigabytes of JSON per Second — Geoff Langdale, Daniel Lemire, 2019
https://scholar.google.com/scholar?q=Parsing+Gigabytes+of+JSON+per+Second
7. The Tail at Scale — Jeffrey Dean, Luiz André Barroso, 2013
https://scholar.google.com/scholar?q=The+Tail+at+Scale
8. Efficient Memory Management for Large Language Model Serving with PagedAttention — Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph E. Gonzalez, Hao Zhang, Ion Stoica, 2023
https://scholar.google.com/scholar?q=Efficient+Memory+Management+for+Large+Language+Model+Serving+with+PagedAttention
9. Gandiva: Introspective Cluster Scheduling for Deep Learning — Wencong Xiao, Romil Bhardwaj, Ramachandran Ramjee, Muthian Sivathanu, et al., 2018
https://scholar.google.com/scholar?q=Gandiva%3A+Introspective+Cluster+Scheduling+for+Deep+Learning
10. Salus: Fine-Grained GPU Sharing Primitives for Deep Learning Applications — Peifeng Yu, Mosharaf Chowdhury, 2020
https://scholar.google.com/scholar?q=Salus%3A+Fine-Grained+GPU+Sharing+Primitives+for+Deep+Learning+Applications
11. Smarter, Better, Faster, Longer: A Modern Bidirectional Encoder for Fast, Memory Efficient, and Long Context Finetuning and Inference — Benjamin Warner, Antoine Chaffin, Benjamin Clavié, et al., 2024
https://scholar.google.com/scholar?q=Smarter%2C+Better%2C+Faster%2C+Longer%3A+A+Modern+Bidirectional+Encoder+for+Fast%2C+Memory+Efficient%2C+and+Long+Context+Finetuning+and+Inference
12. Dynamic Sparse Flash Attention / FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision — Jay Shah, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, Tri Dao, 2024
https://scholar.google.com/scholar?q=Dynamic+Sparse+Flash+Attention+%2F+FlashAttention-3%3A+Fast+and+Accurate+Attention+with+Asynchrony+and+Low-precision
13. Longformer: The Long-Document Transformer — Iz Beltagy, Matthew E. Peters, Arman Cohan, 2020
https://scholar.google.com/scholar?q=Longformer%3A+The+Long-Document+Transformer
14. Self-Attention Does Not Need O(n^2) Memory — Markus N. Rabe, Charles Staats, 2021
https://scholar.google.com/scholar?q=Self-Attention+Does+Not+Need+O%28n%5E2%29+Memory
15. RouteLLM: Learning to Route LLMs with Preference Data — Isaac Ong et al., 2024
https://scholar.google.com/scholar?q=RouteLLM%3A+Learning+to+Route+LLMs+with+Preference+Data
16. Jailbreaking Black Box Large Language Models in Twenty Queries (PAIR) and JailbreakBench — Patrick Chao et al., 2023-2024
https://scholar.google.com/scholar?q=Jailbreaking+Black+Box+Large+Language+Models+in+Twenty+Queries+%28PAIR%29+and+JailbreakBench
17. LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression — Huiqiang Jiang et al., 2024
https://scholar.google.com/scholar?q=LongLLMLingua%3A+Accelerating+and+Enhancing+LLMs+in+Long+Context+Scenarios+via+Prompt+Compression
18. Llama Guard: LLM-based Input-Output Safeguard for Human-AI Conversations — Hakan Inan et al., 2023
https://scholar.google.com/scholar?q=Llama+Guard%3A+LLM-based+Input-Output+Safeguard+for+Human-AI+Conversations
19. NVIDIA MPS / MIG and AMD Instinct compute partitioning (SPX/CPX/NPS) documentation — NVIDIA; AMD, 2023-2025
https://scholar.google.com/scholar?q=NVIDIA+MPS+%2F+MIG+and+AMD+Instinct+compute+partitioning+%28SPX%2FCPX%2FNPS%29+documentation
20. Orca / Sarathi-Serve: Taming Throughput-Latency Tradeoff in LLM Inference with Chunked Prefills — Amey Agrawal et al., 2024
https://scholar.google.com/scholar?q=Orca+%2F+Sarathi-Serve%3A+Taming+Throughput-Latency+Tradeoff+in+LLM+Inference+with+Chunked+Prefills
21. simdjson: Parsing Gigabytes of JSON per Second — Geoff Langdale, Daniel Lemire, 2019
https://scholar.google.com/scholar?q=simdjson%3A+Parsing+Gigabytes+of+JSON+per+Second
Interactive Visualization: 98× Faster LLM Routing with Flash Attention for vLLM Semantic Router